Agentic data science with the Data Agent Kit
cloud.google.com·6h ago
TL;DR
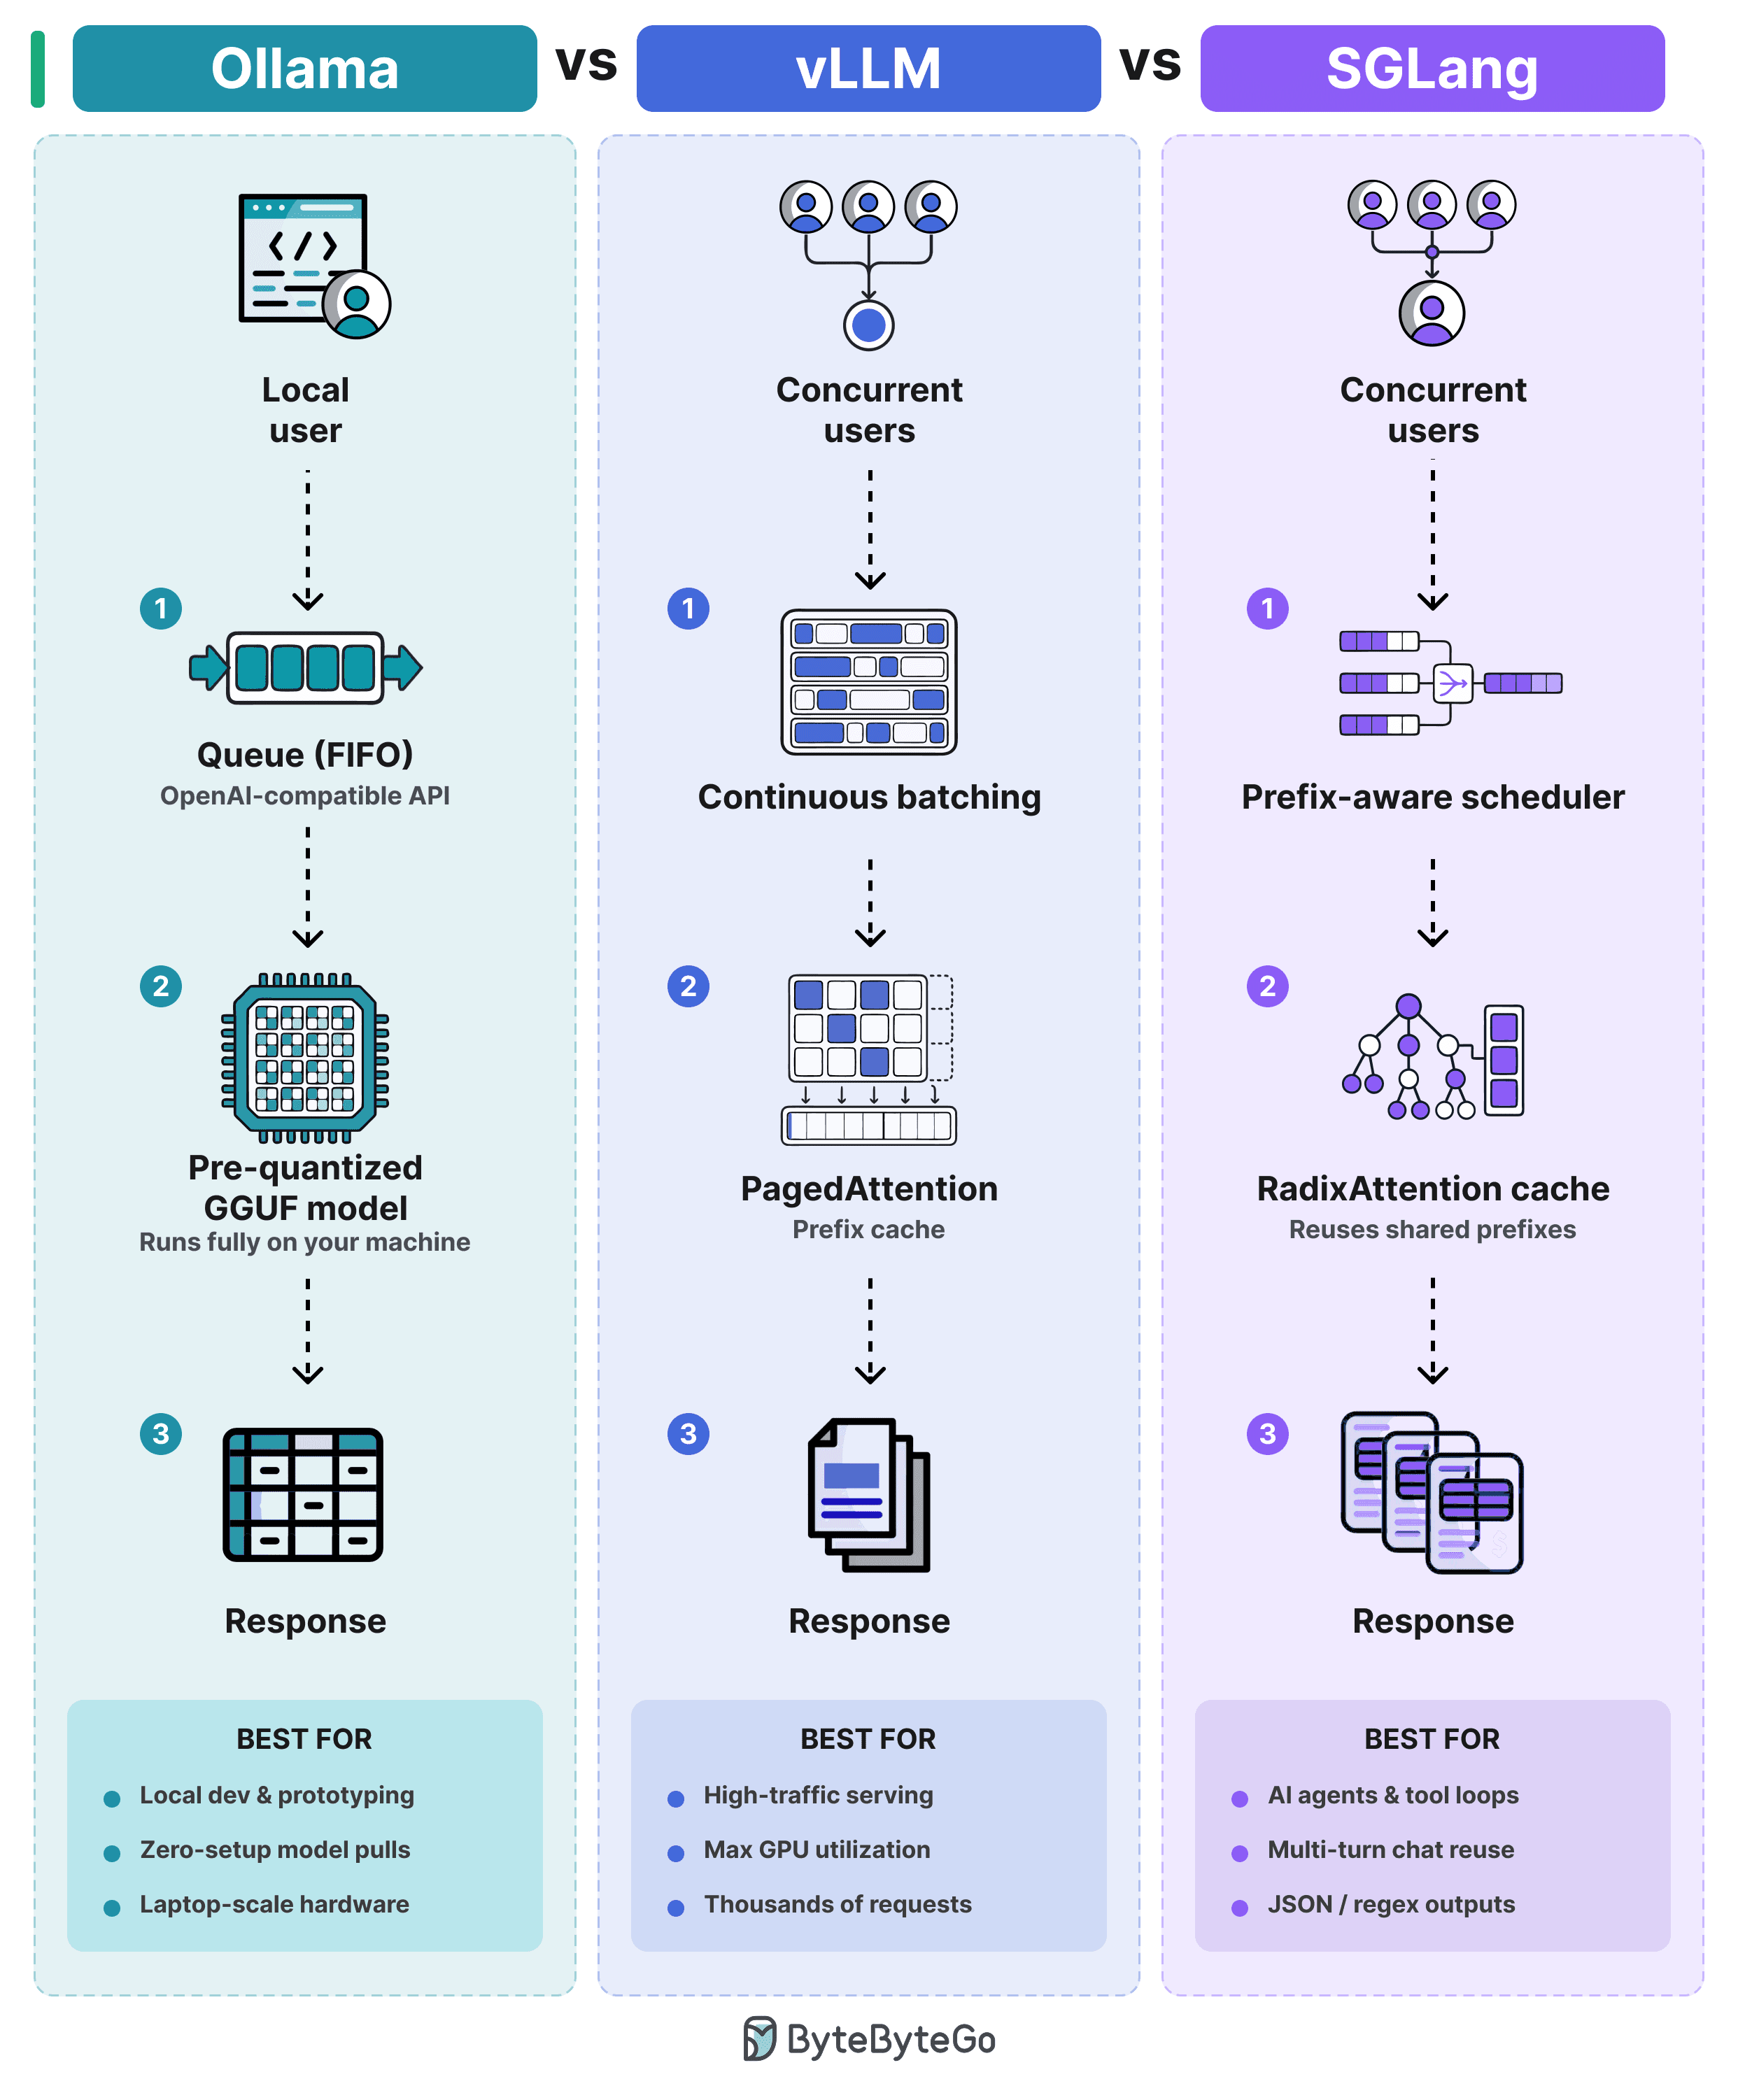
Ollama, vLLM, and SGLang are three engines for running open-weight models locally, each with unique request handling methods. Understanding these differences can help developers choose the right tool for their needs.
✦ Why It Matters
Evaluate your project needs today to select the most suitable engine for running open-weight models.
Key Takeaways
How It Works
Ollama processes requests in a FIFO queue using a pre-quantized GGUF model, while vLLM batches requests continuously to maximize GPU usage. SGLang employs a prefix-aware scheduler that reuses shared prompts to optimize multi-turn conversations.
Related