BerriAI / litellm
github.com·3d ago
TL;DR
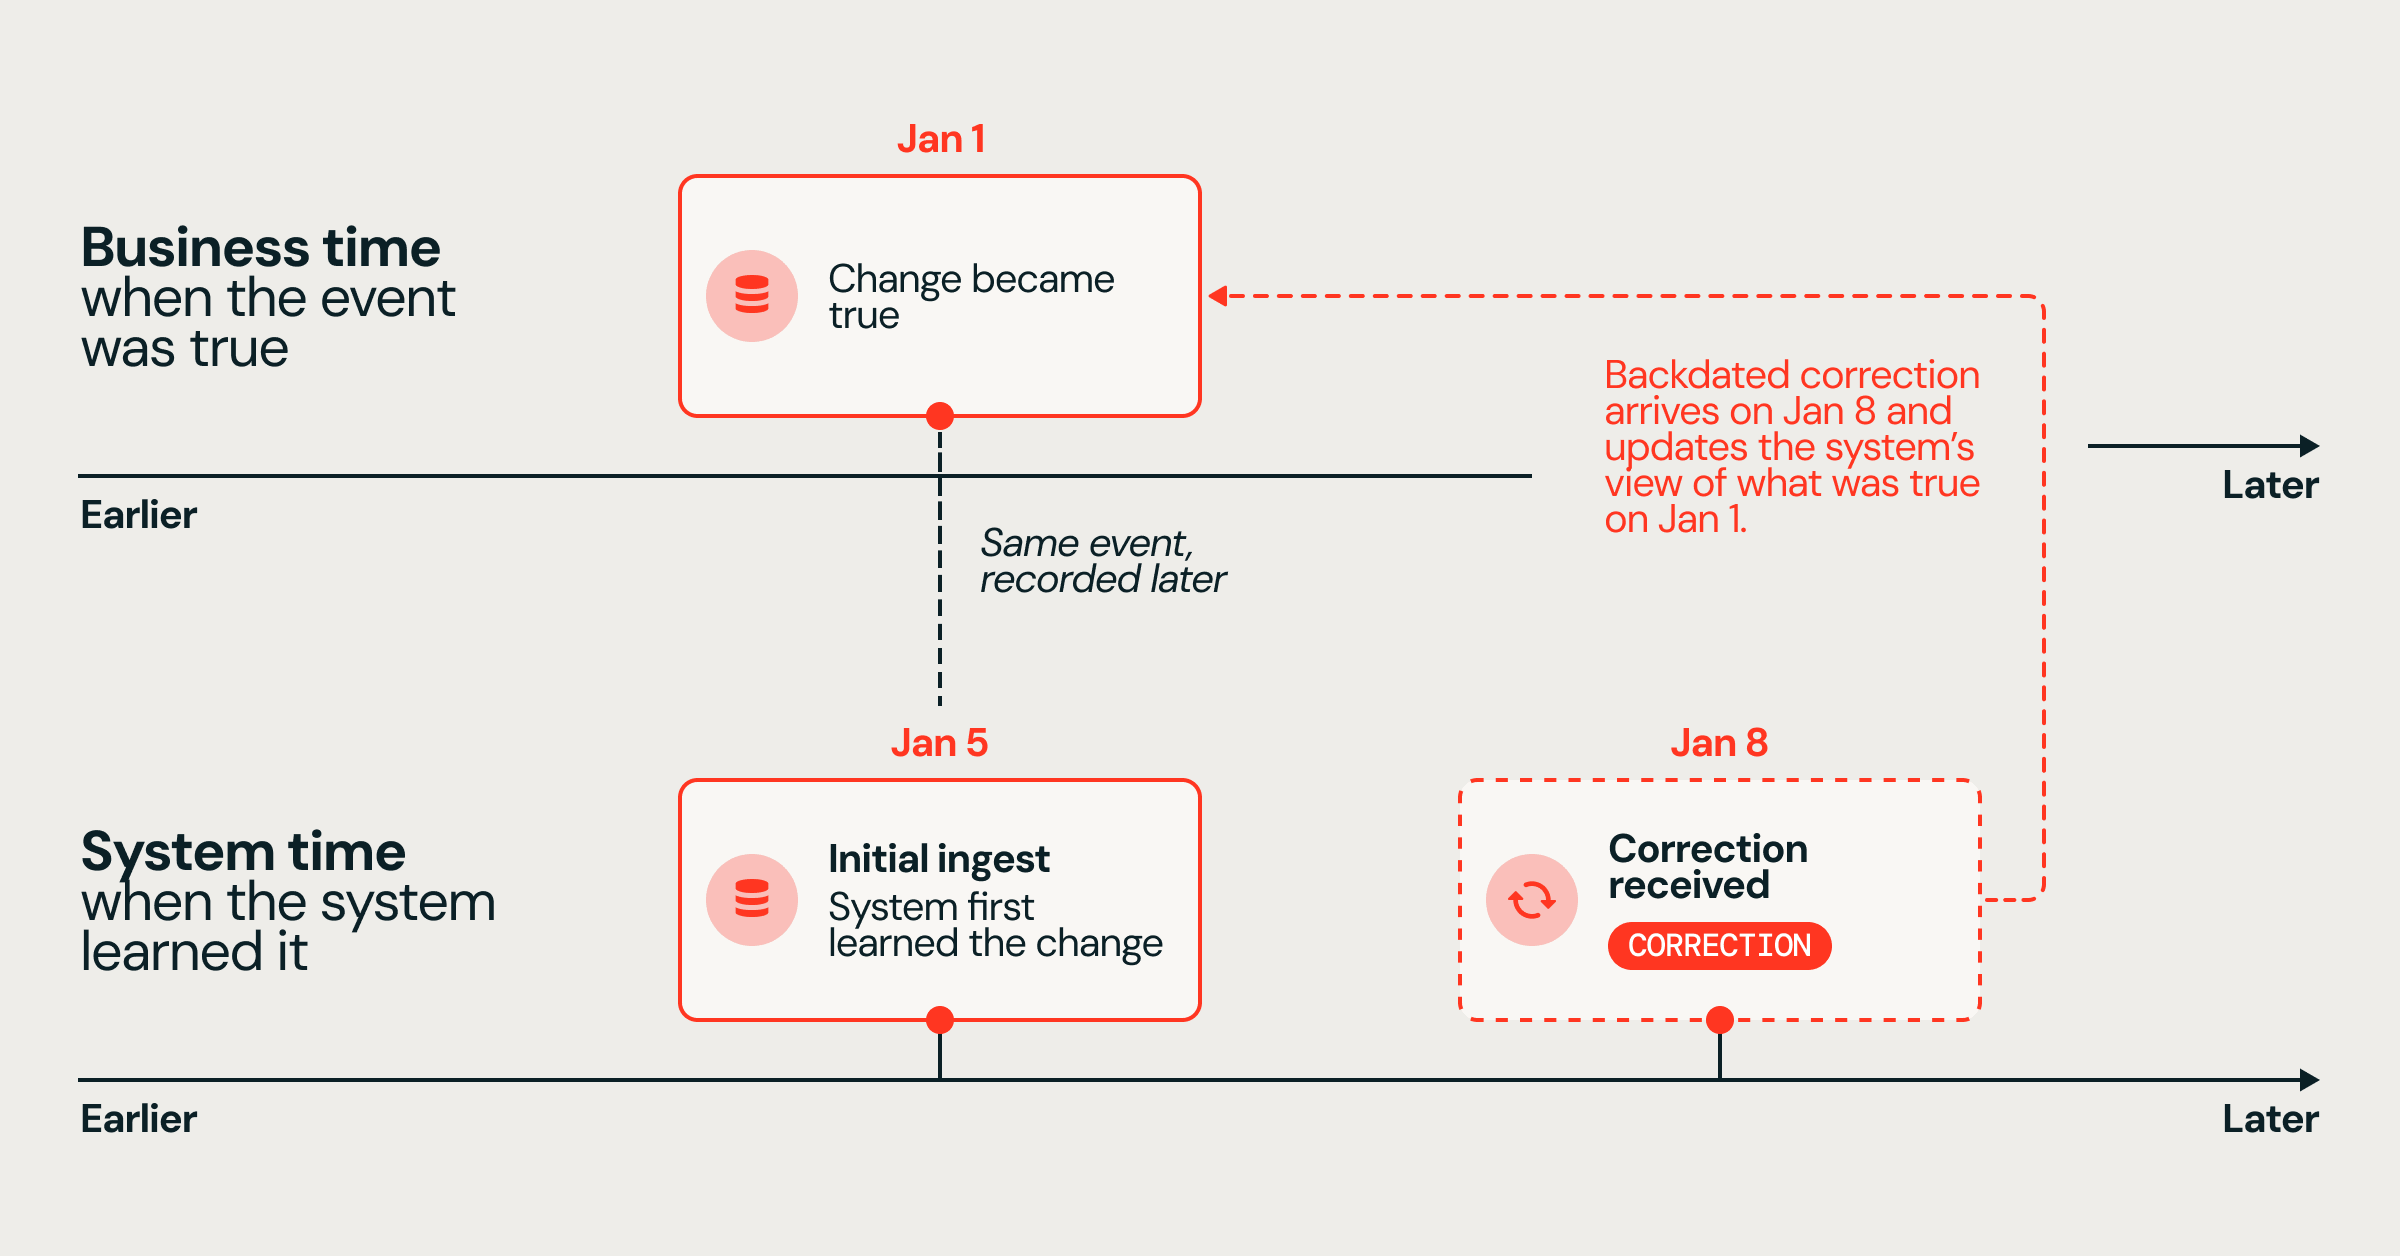
AUTO CDC in Apache Spark has been enhanced to address complex real-world change data capture (CDC) challenges, particularly for regulatory compliance. This advancement allows for better historical data reconstruction, crucial for firms under strict recordkeeping rules.
✦ Why It Matters
Implement AUTO CDC to ensure compliance with SEC recordkeeping rules and avoid costly fines.
Key Takeaways
How It Works
Bitemporal AUTO CDC introduces four system-managed columns to track both business and system time independently. This allows for accurate historical data reconstruction, even when corrections arrive out of order.
The engine rewrites history as needed, maintaining data integrity without requiring complex hand-coded logic.