Agentic data science with the Data Agent Kit
cloud.google.com·6h ago
TL;DR
Researchers have developed techniques to effectively reduce the size of language models without significantly sacrificing their performance. This addresses the growing disparity between model size and available consumer hardware resources.
✦ Why It Matters
Consider implementing model compression techniques to optimize your AI applications for better performance on available hardware.
Key Takeaways
How It Works
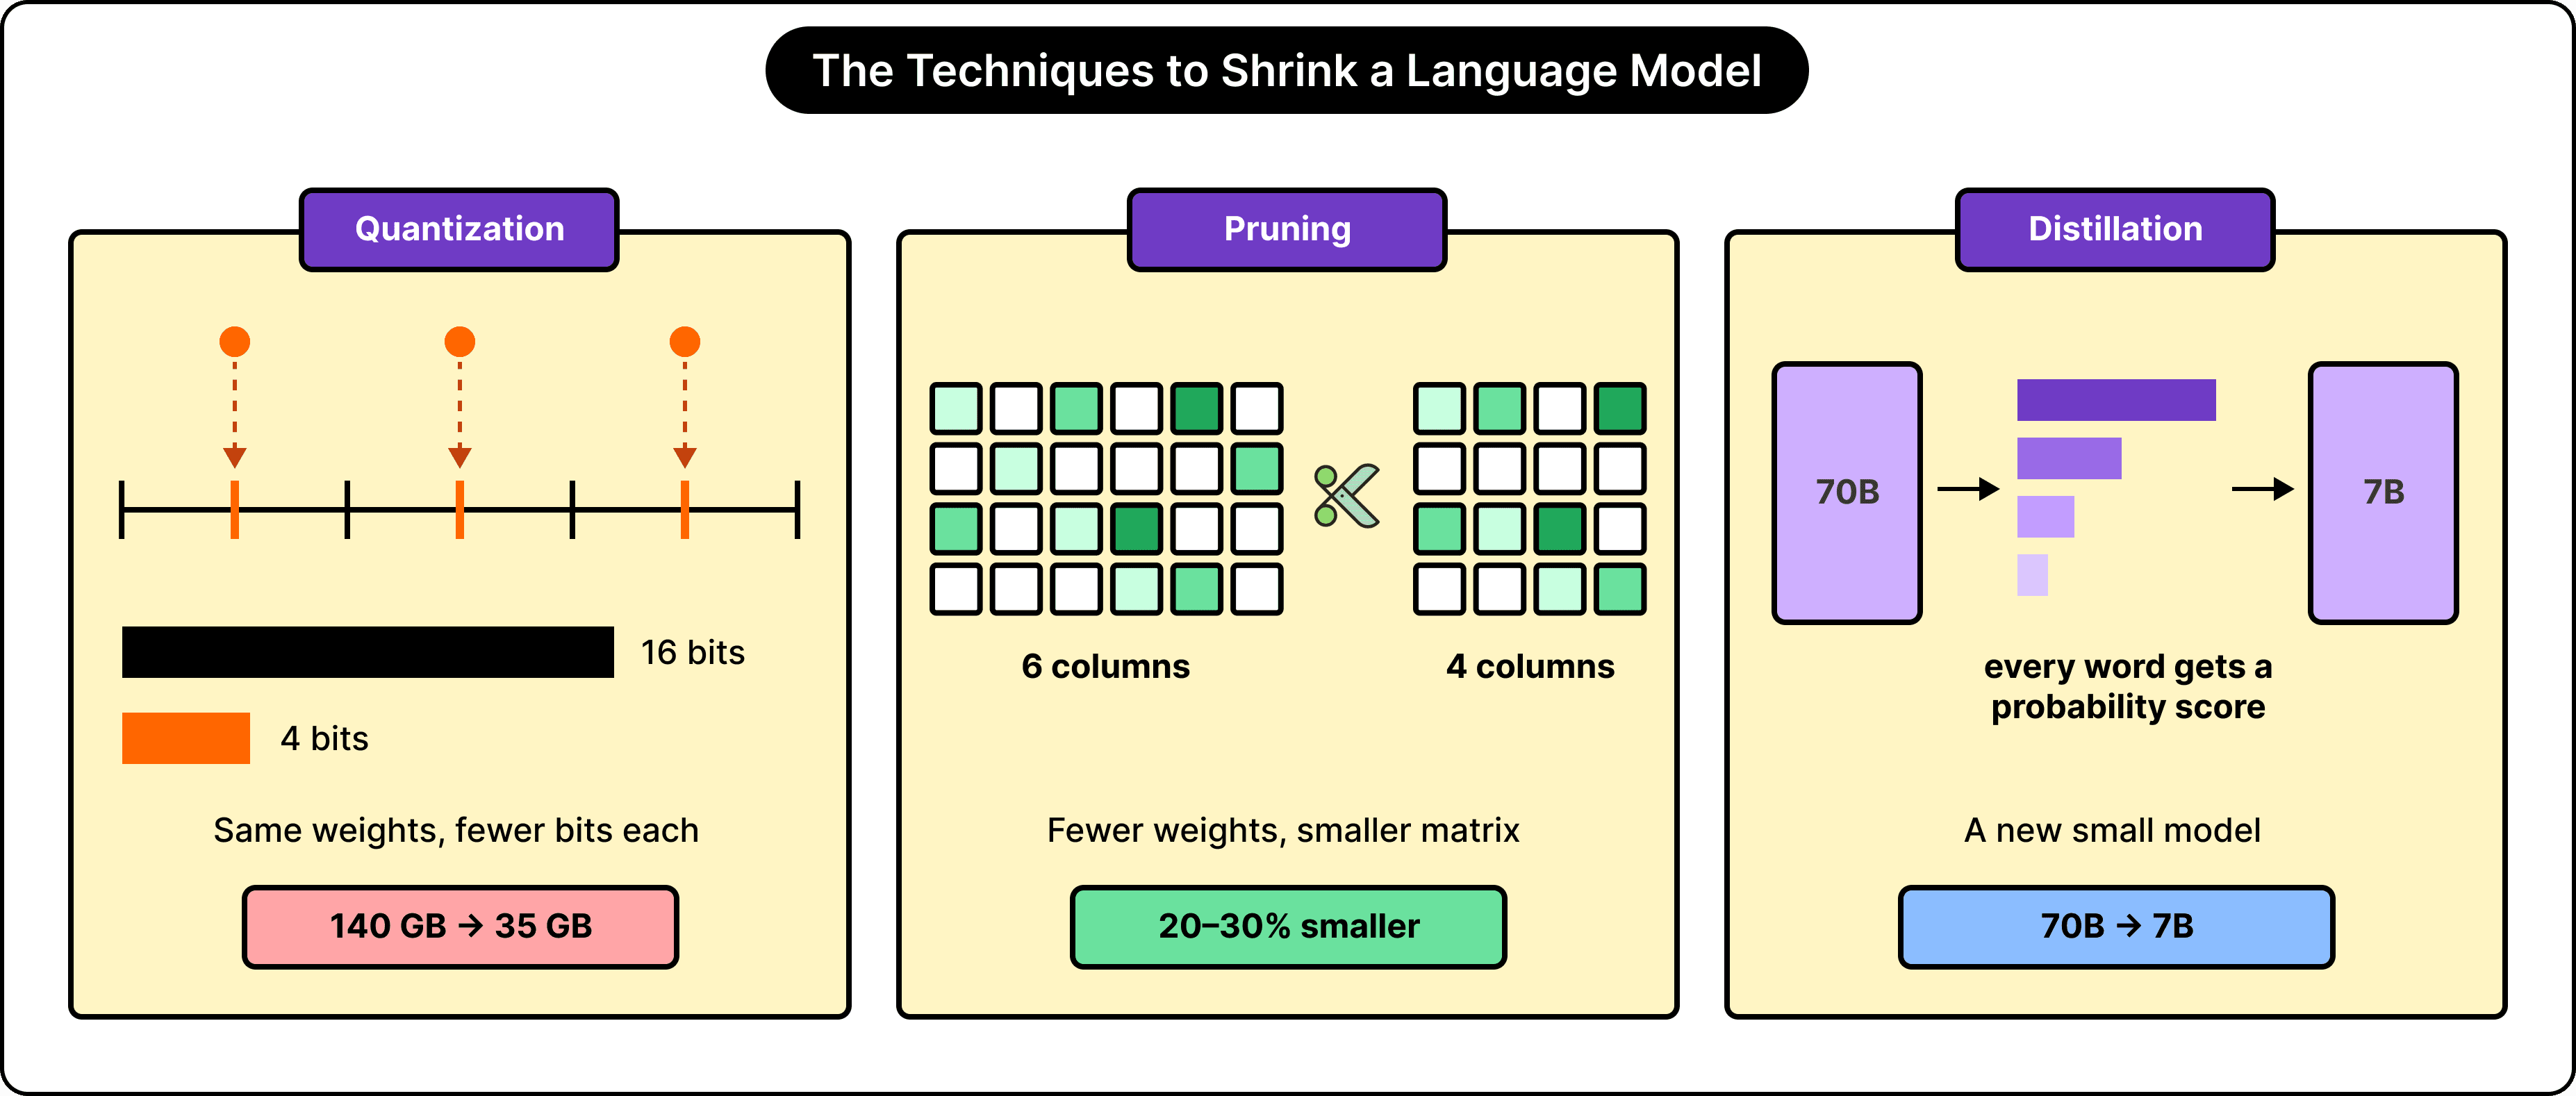
Quantization reduces the precision of weights, allowing models to use less memory without significantly impacting output quality. Pruning removes weights that contribute minimally to performance, while knowledge distillation trains a smaller model to replicate the behavior of a larger one, effectively transferring knowledge.
Related