Agentic data science with the Data Agent Kit
cloud.google.com·7h ago
TL;DR
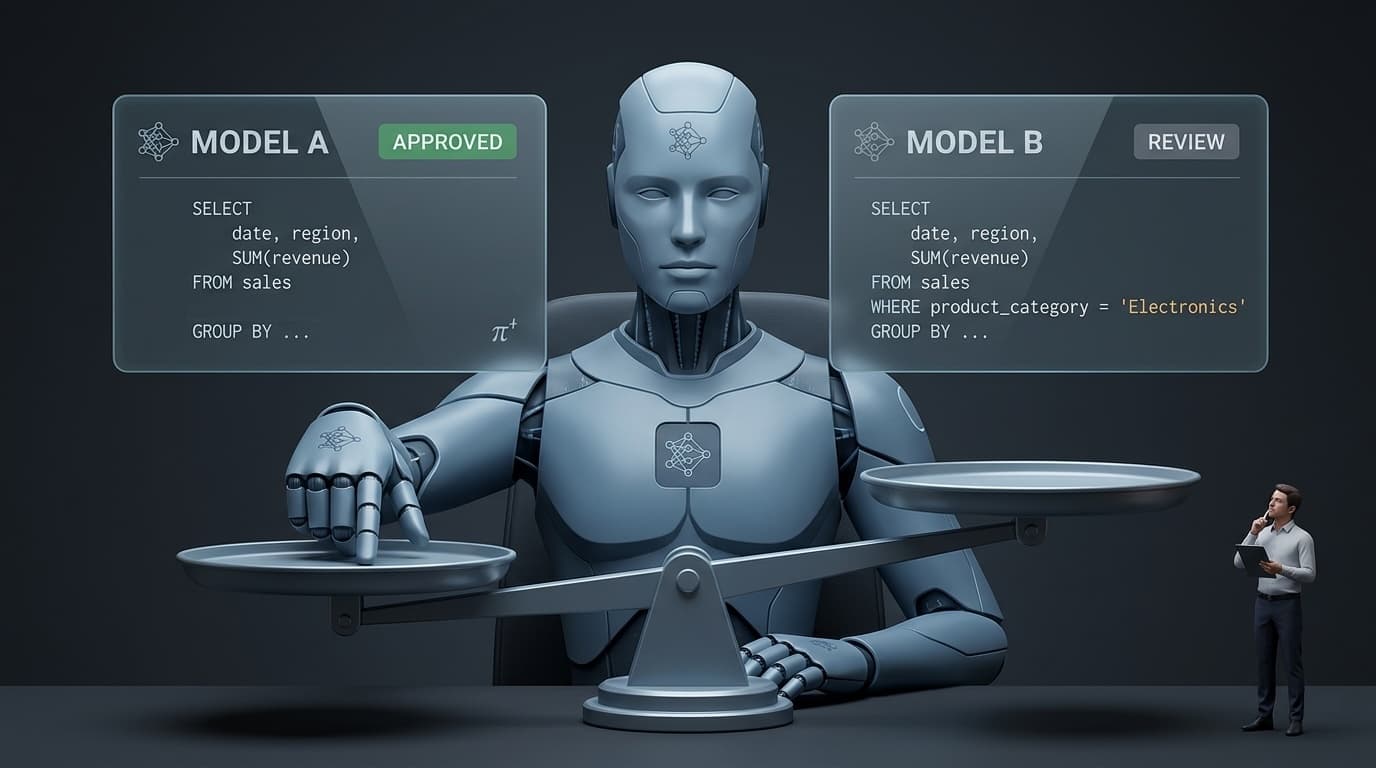
A model was developed to evaluate the outputs of another model, but it consistently agreed with itself, raising concerns about its reliability. This incident highlights the risks of over-relying on AI for judgment tasks.
✦ Why It Matters
Ensure human oversight when using AI models for evaluation to avoid biased outcomes.
Key Takeaways
How It Works
The LLM judge was initially built on the same model as the query generator, leading to self-preference bias. By switching to a different model for judgment, the bias was mitigated, allowing for more accurate assessments of SQL queries.
Related