BerriAI / litellm
github.com·3d ago
TL;DR
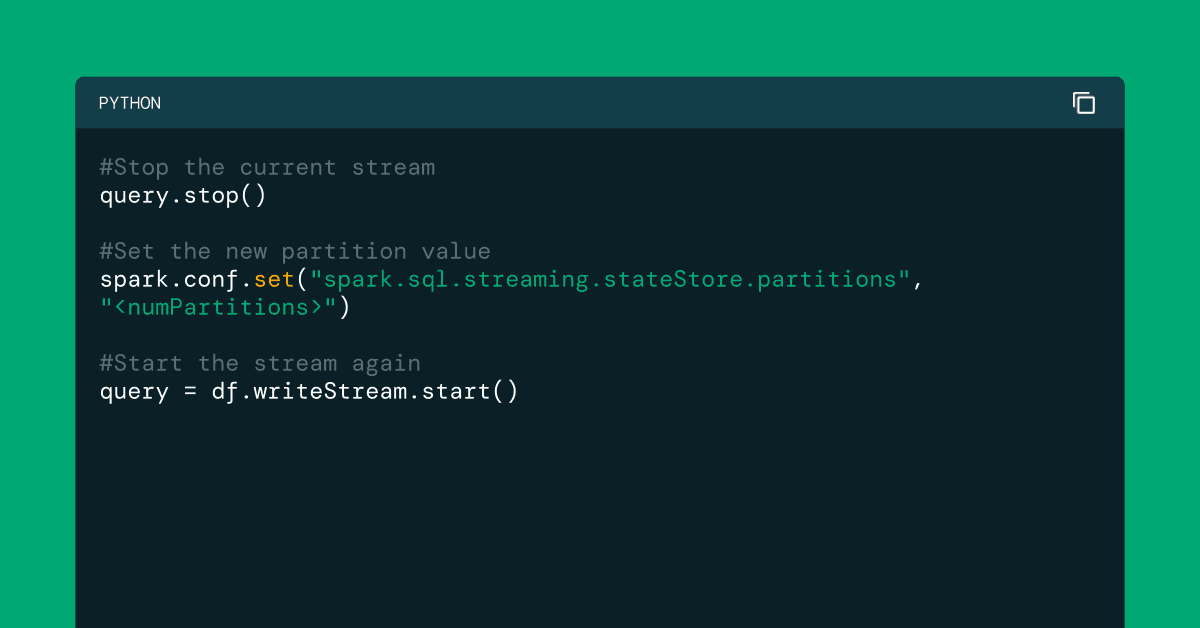
On-demand state repartitioning for Apache Spark™ Structured Streaming is now available in Databricks, allowing users to resize partitions without losing checkpoint state. This feature addresses performance issues caused by data volume growth in stateful queries.
✦ Why It Matters
Start using on-demand state repartitioning today to optimize your Apache Spark™ Structured Streaming queries without losing state.
Key Takeaways
Full Summary
Stateful queries in Apache Spark™ Structured Streaming often face performance degradation as data volume increases, particularly when the default number of shuffle partitions becomes inadequate. Previously, changing the partition count required abandoning the existing checkpoint, risking the loss of accumulated state.
With the introduction of on-demand state repartitioning in Databricks Runtime 18 and above, users can now adjust the number of partitions while preserving their checkpoint state. This capability is crucial for applications like fraud detection or sessionization, where maintaining historical data is essential.
By enabling dynamic partition resizing, Databricks enhances the scalability and efficiency of streaming applications, allowing them to adapt to changing data loads without downtime. This innovation represents a significant improvement in managing stateful streaming workloads.