Trusted Data Apps for the Agentic Data Cloud, powered by Looker
cloud.google.com·7h ago
TL;DR
Big AI models can enhance smaller models' performance, but their high operational costs and context limitations hinder efficiency. Understanding these challenges is crucial for optimizing AI workflows.
✦ Why It Matters
Evaluate your team's context maturity today to enhance AI integration and performance.
Key Takeaways
How It Works
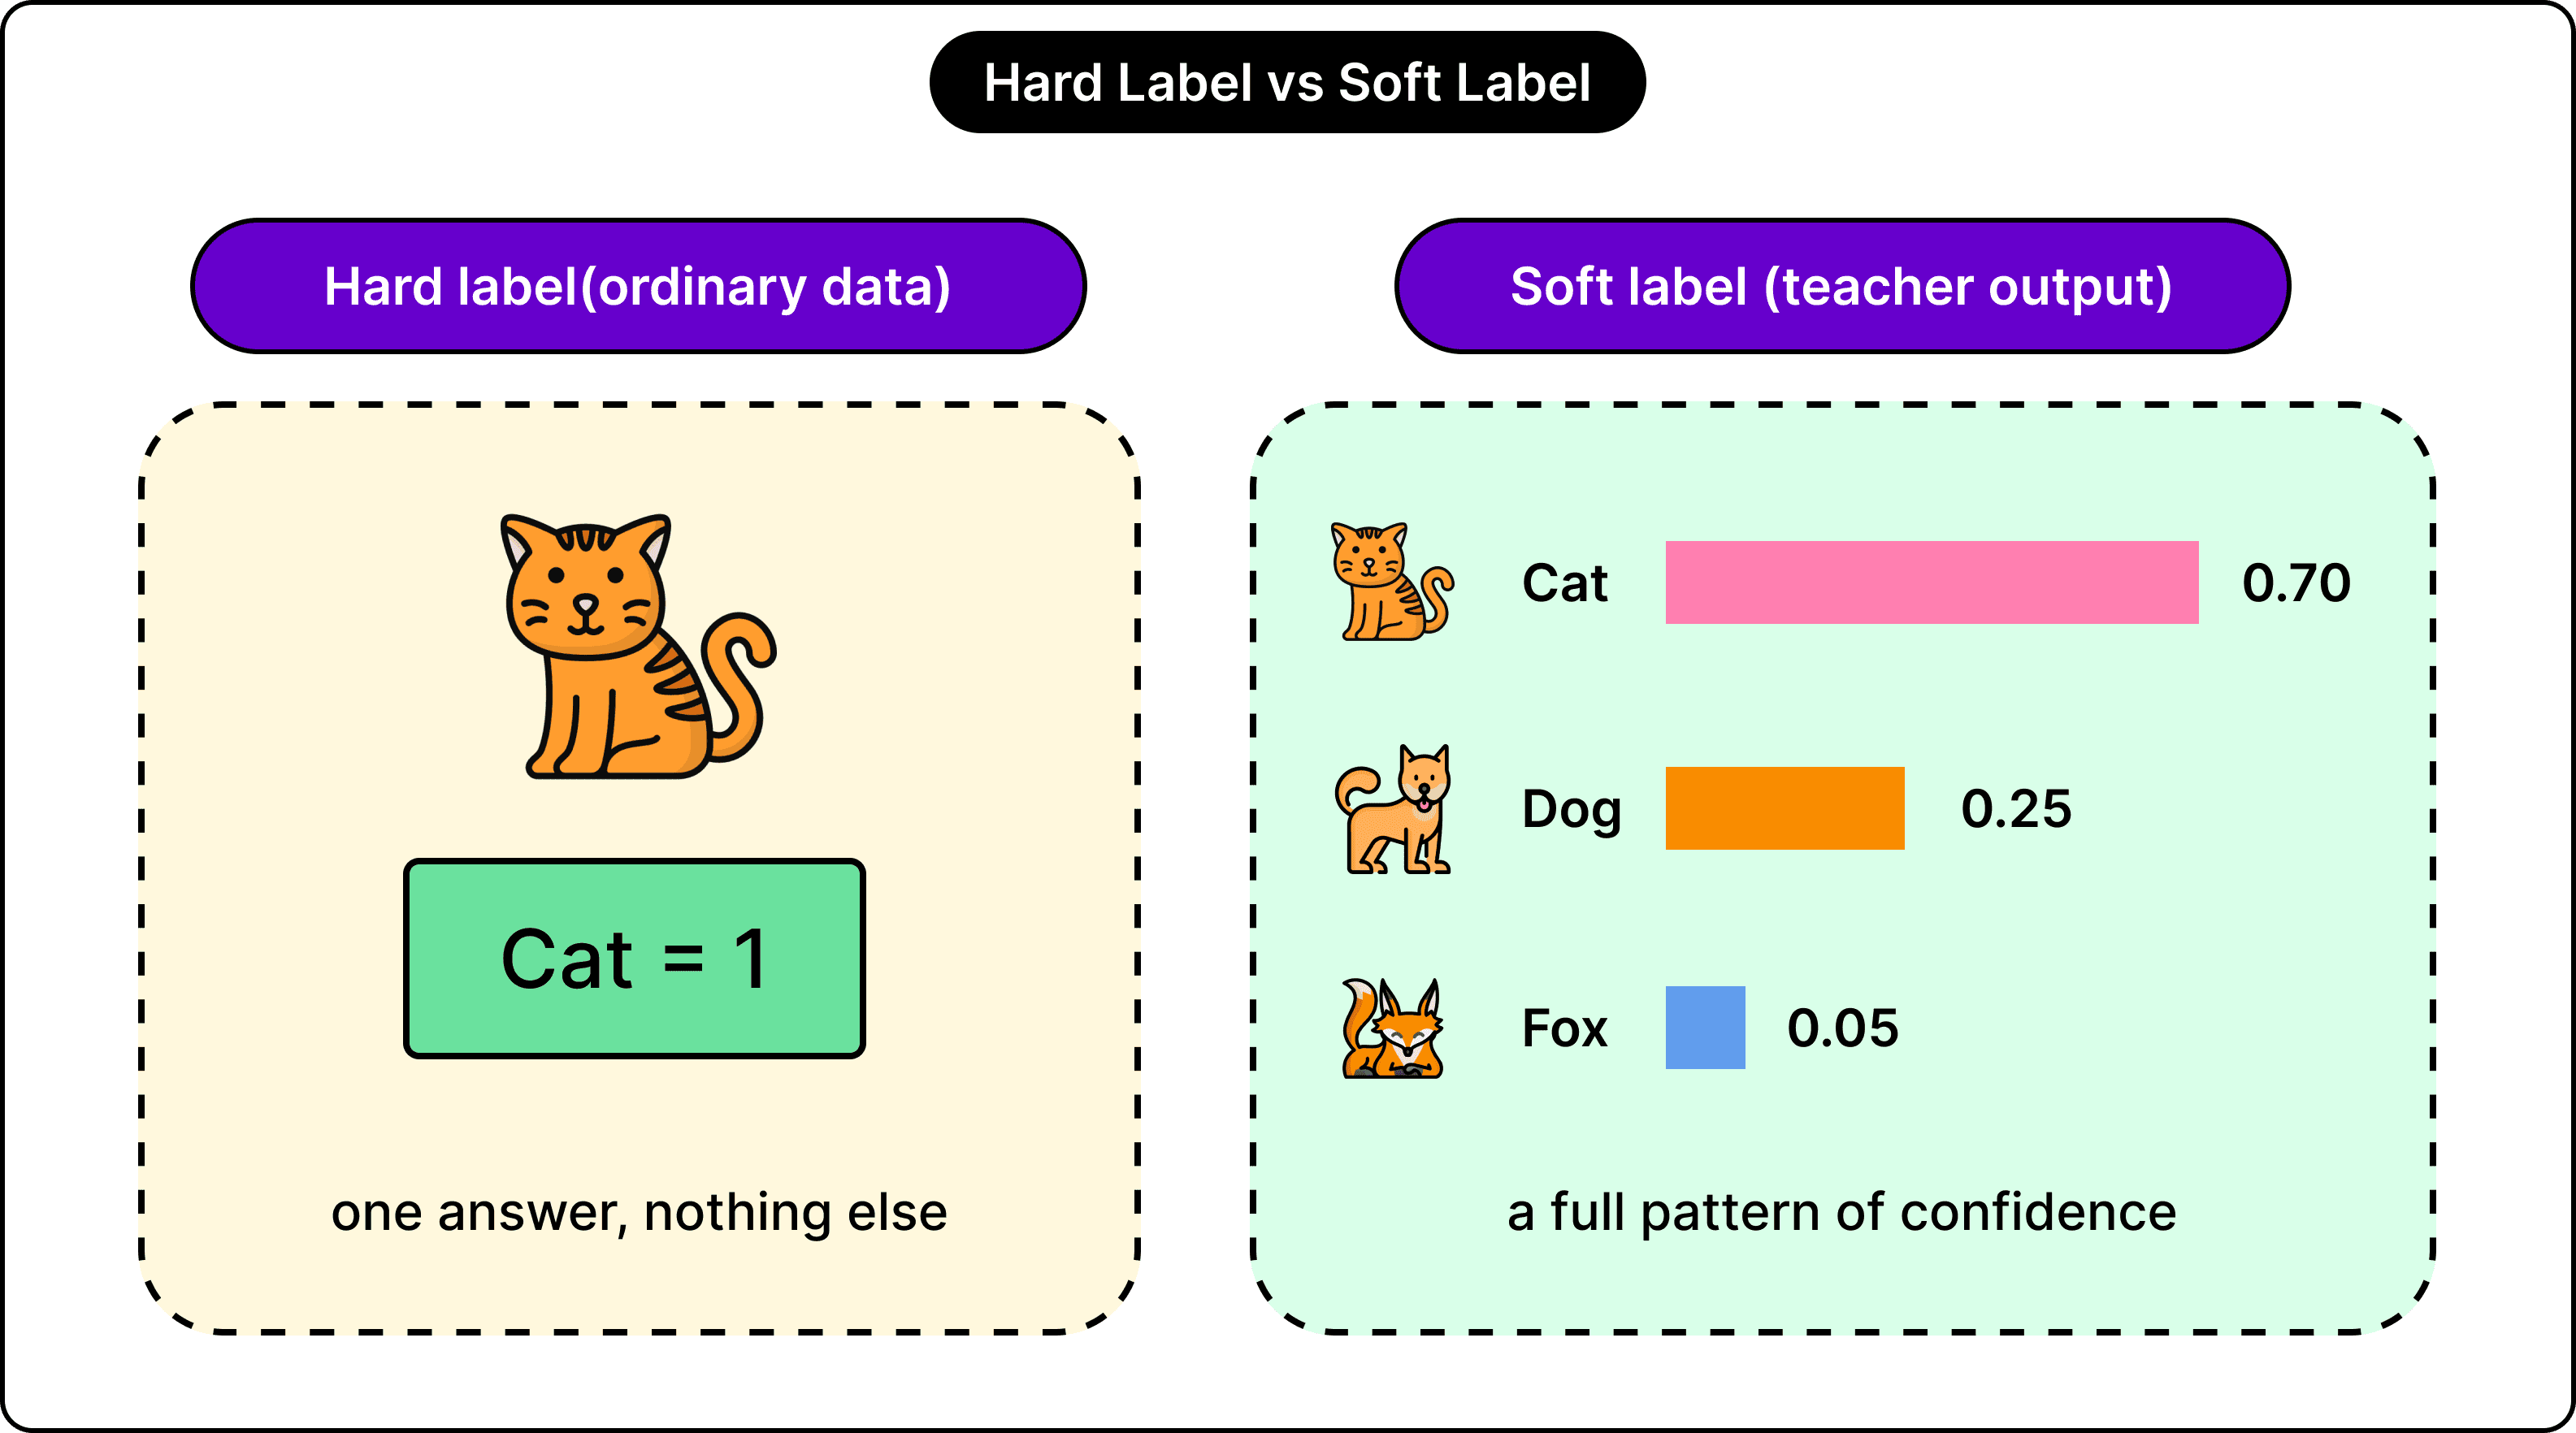
Knowledge distillation involves training a smaller model (student) to mimic a larger model (teacher). The student learns from the teacher's outputs, which include soft labels that provide a probability distribution over possible answers, rather than just a single correct label.
This richer information allows the student to understand the relationships between different categories, leading to improved performance.
⚠ The Catch
The quality of the student model is limited by the teacher model's performance; if the teacher makes errors, the student learns those errors as well. Additionally, a significant size gap between the teacher and student can hinder effective knowledge transfer.
Related