Agentic data science with the Data Agent Kit
cloud.google.com·6h ago
TL;DR
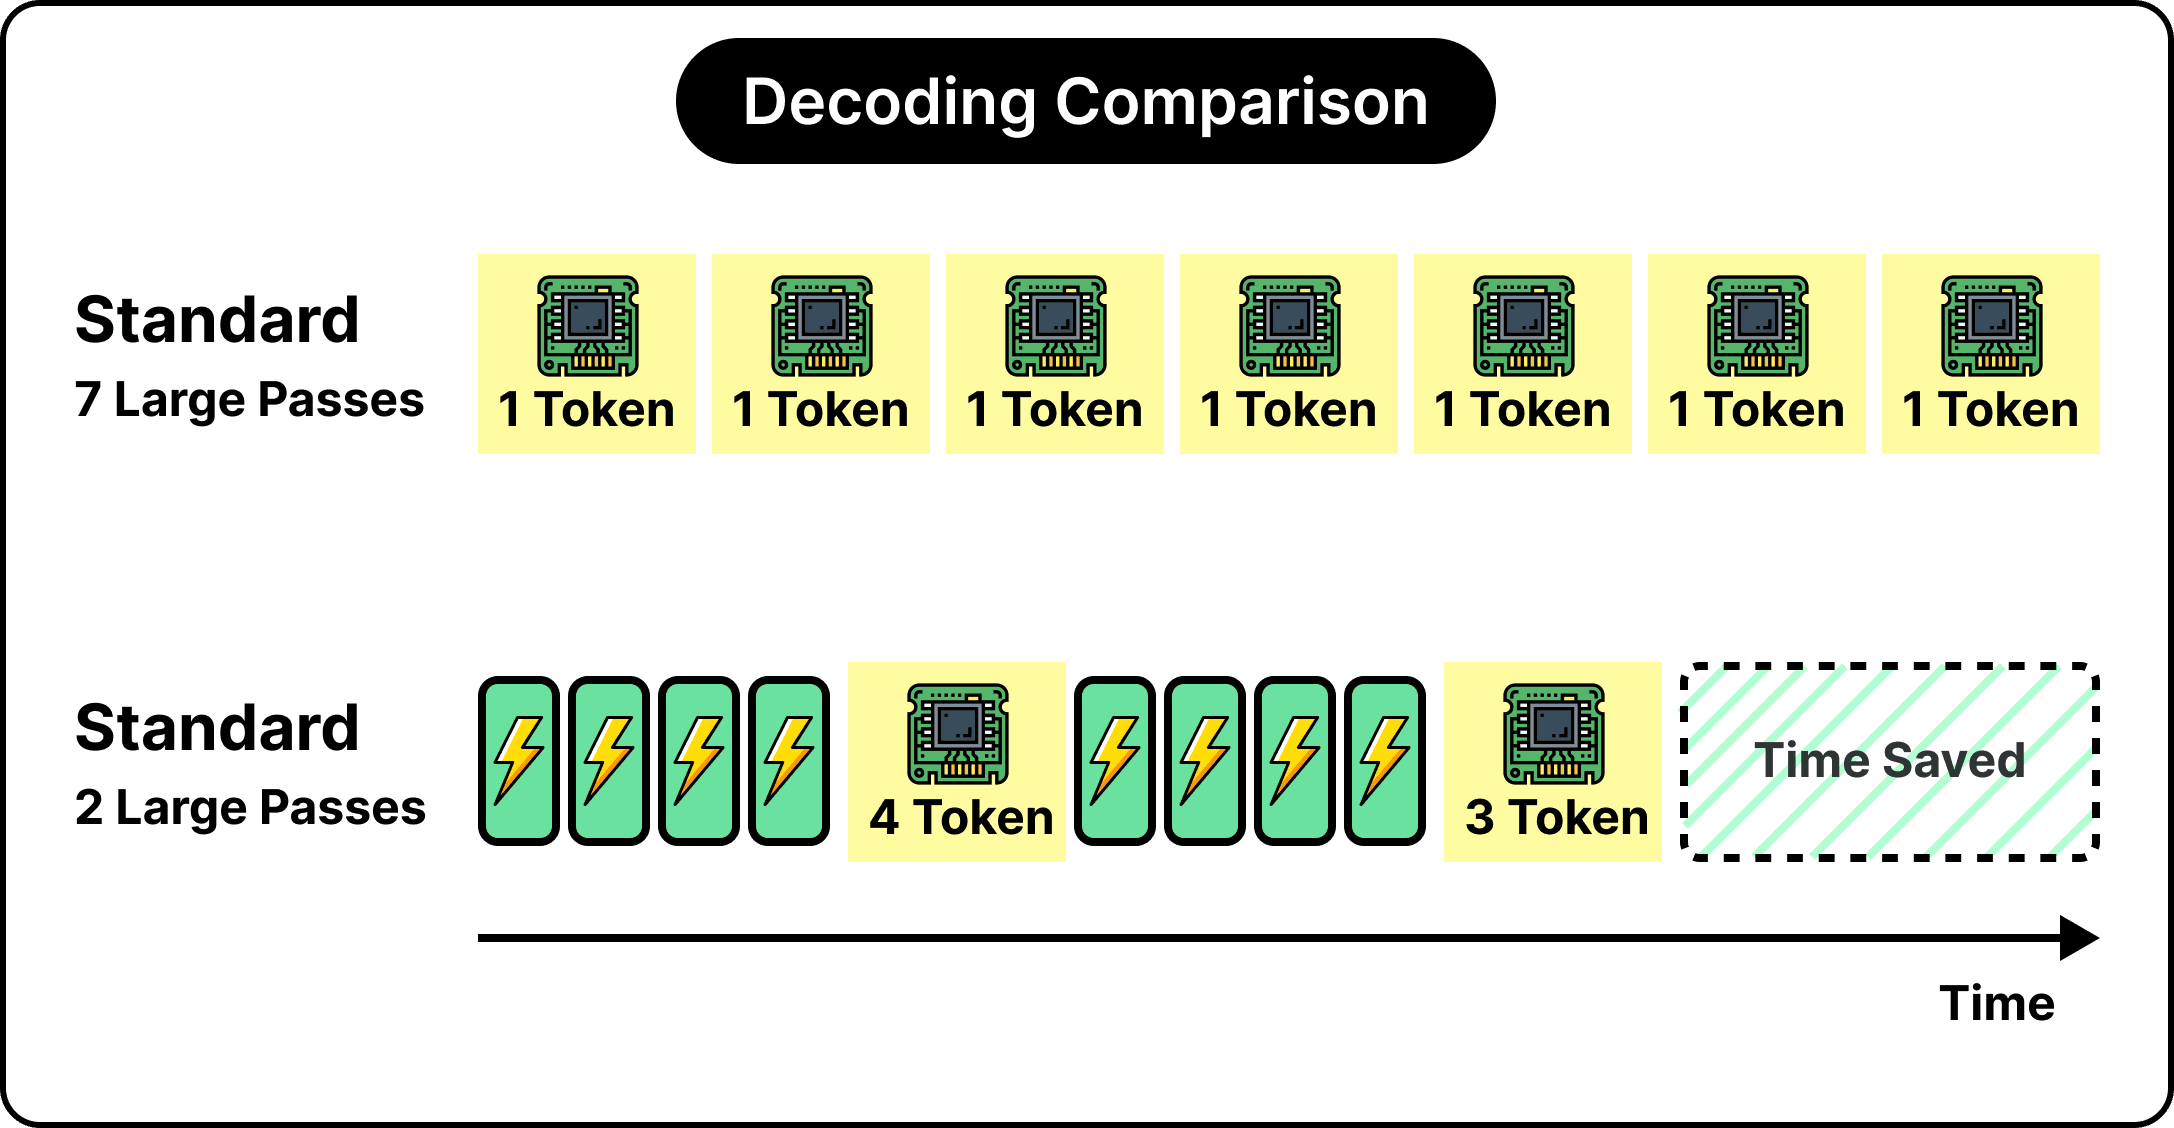
Speculative decoding is introduced as a method to enhance the speed of large language models (LLMs) by up to three times. This technique allows for faster generation of text while maintaining quality.
✦ Why It Matters
Implement speculative decoding in your LLM projects to enhance response times and user experience.
Key Takeaways
How It Works
Speculative decoding leverages a smaller draft model to generate several candidate tokens, which are then evaluated in one forward pass of the larger target model. This allows the model to utilize its compute capacity more effectively, as it can process multiple predictions simultaneously while maintaining the coherence of the output through causal masking.
Related