Trusted Data Apps for the Agentic Data Cloud, powered by Looker
cloud.google.com·7h ago
TL;DR
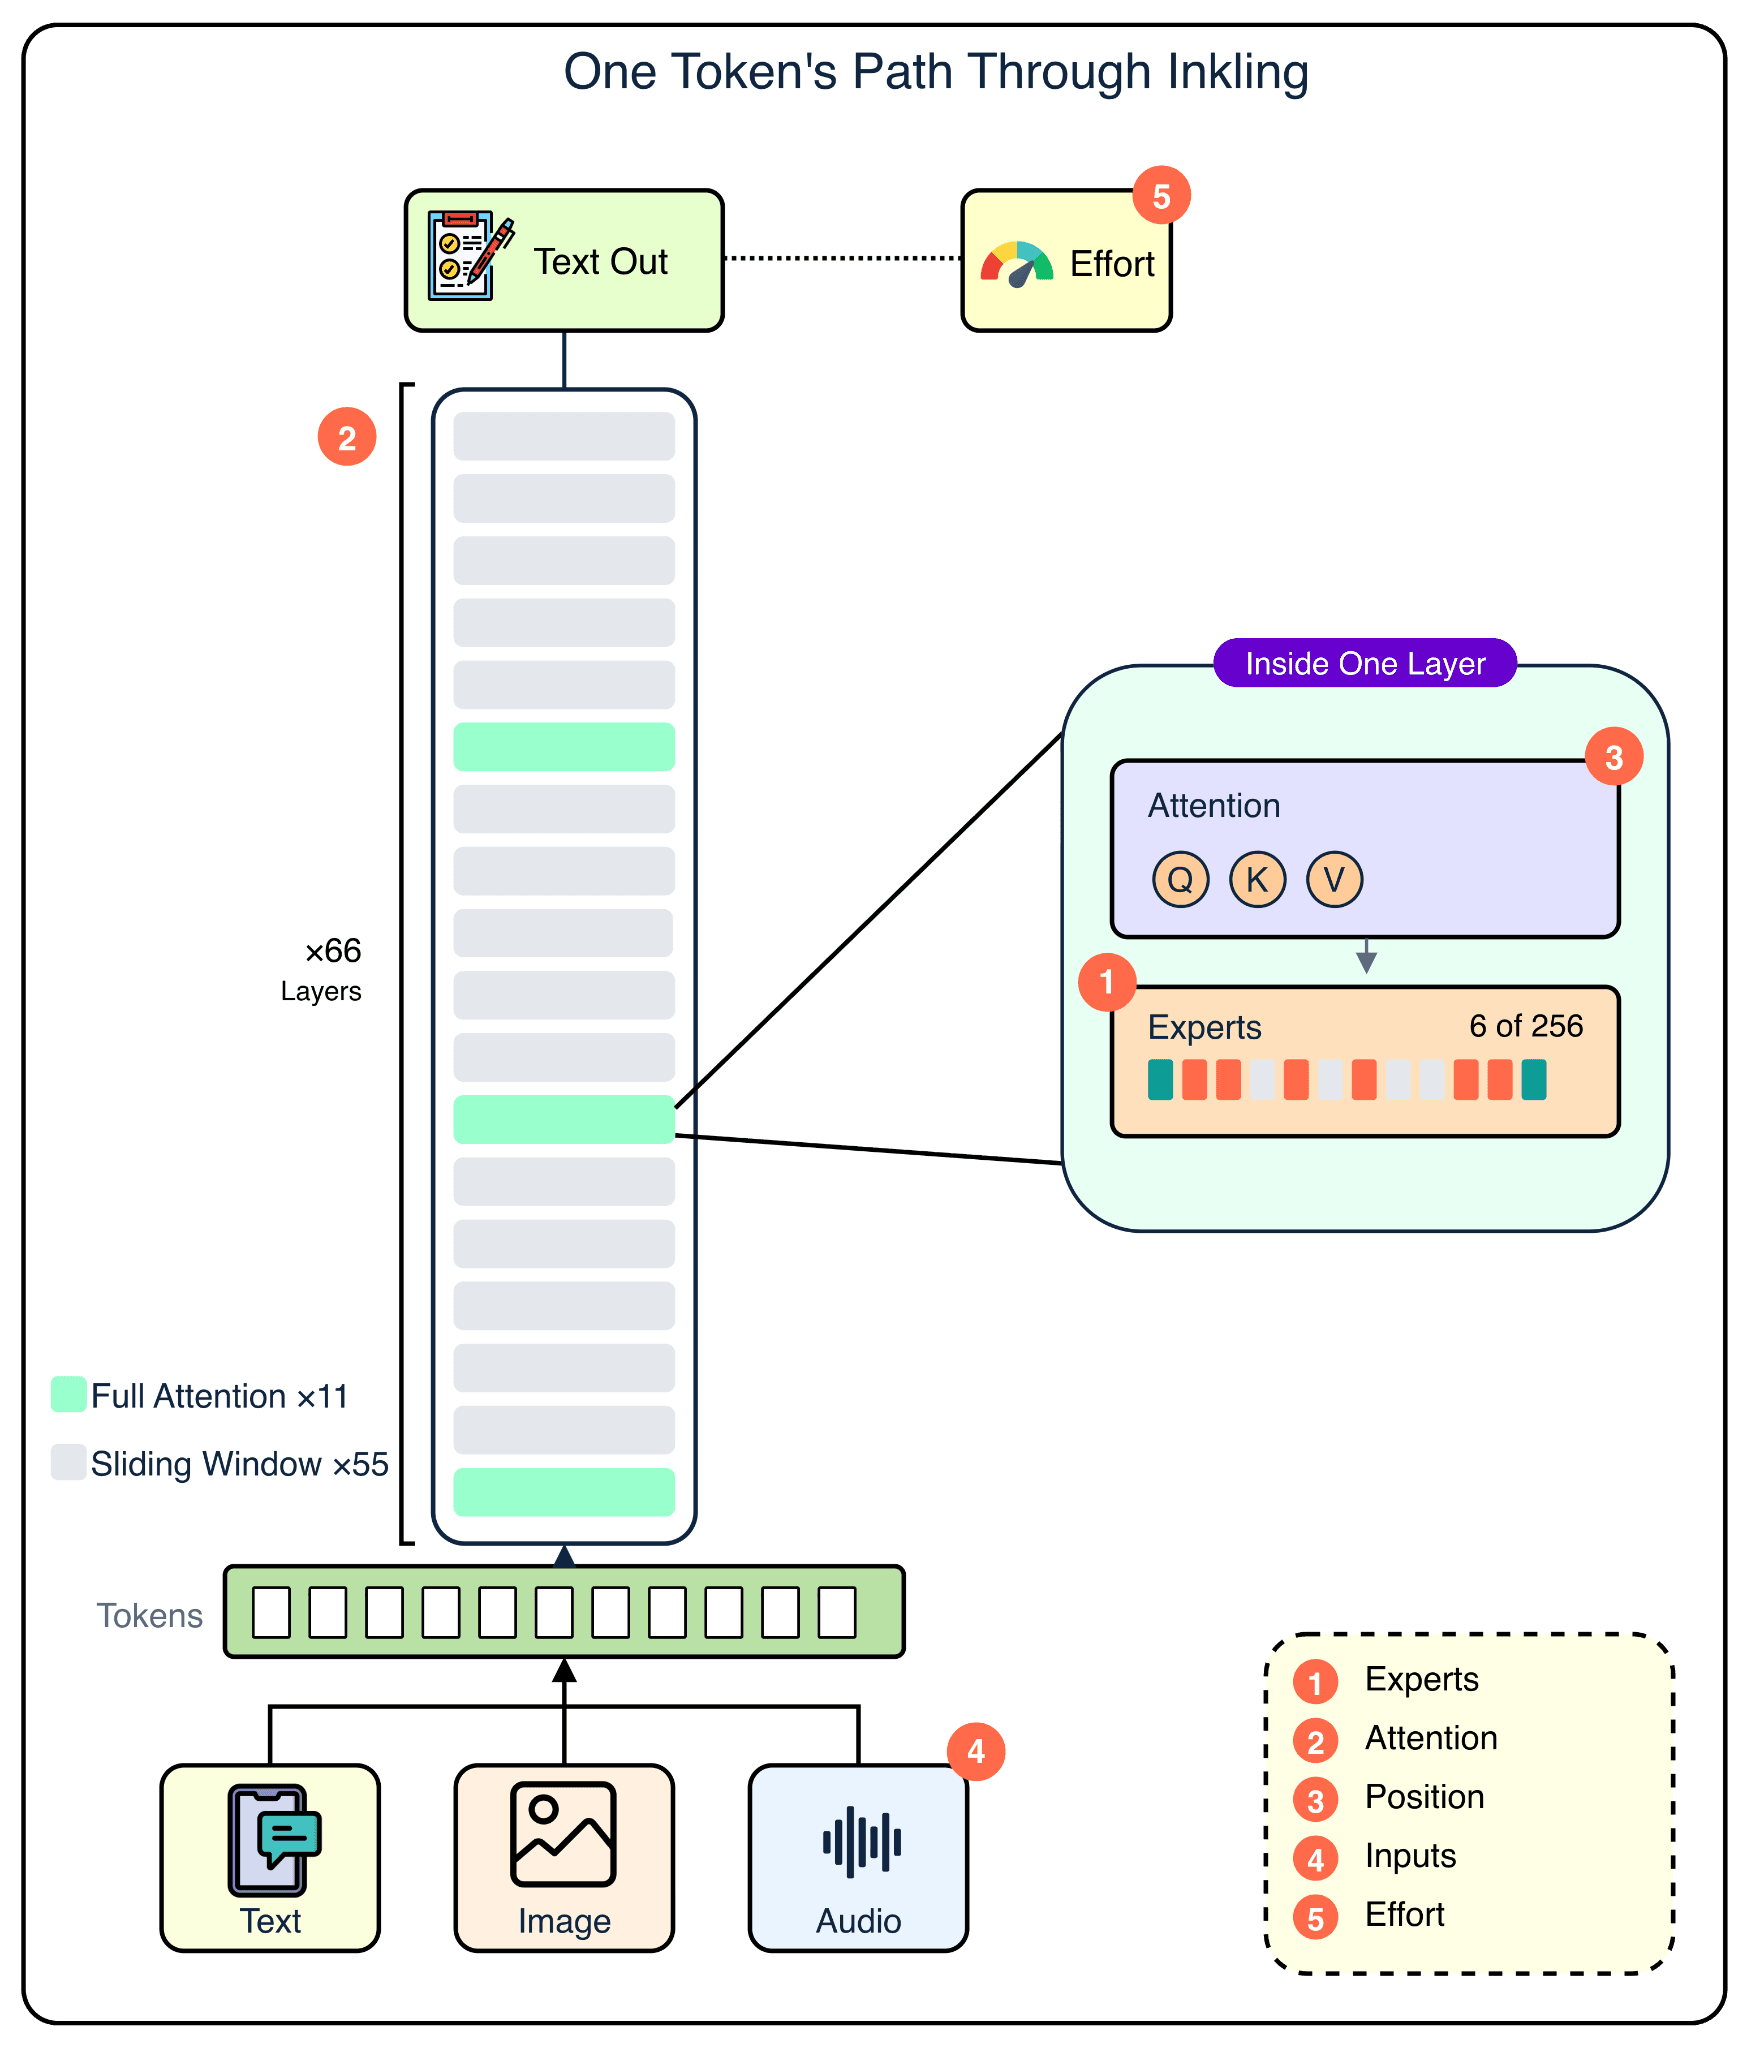
Thinking Machines has introduced Inkling, a customizable AI model with 66 layers and 256 experts per layer, achieving 36% lower token consumption and 92% fewer defects during code generation.
✦ Why It Matters
Consider integrating Inkling into your coding workflows to reduce defects and improve efficiency.
Key Takeaways
How It Works
Inkling's architecture employs a Mixture of Experts strategy, activating only a subset of experts for each token, which reduces computational costs. It combines sliding-window layers with full-attention layers to manage a large context effectively, allowing the model to access both recent and distant information.
The use of relative position encoding helps maintain the order of tokens without being limited by training data constraints.
Related