Agentic data science with the Data Agent Kit
cloud.google.com·7h ago
TL;DR
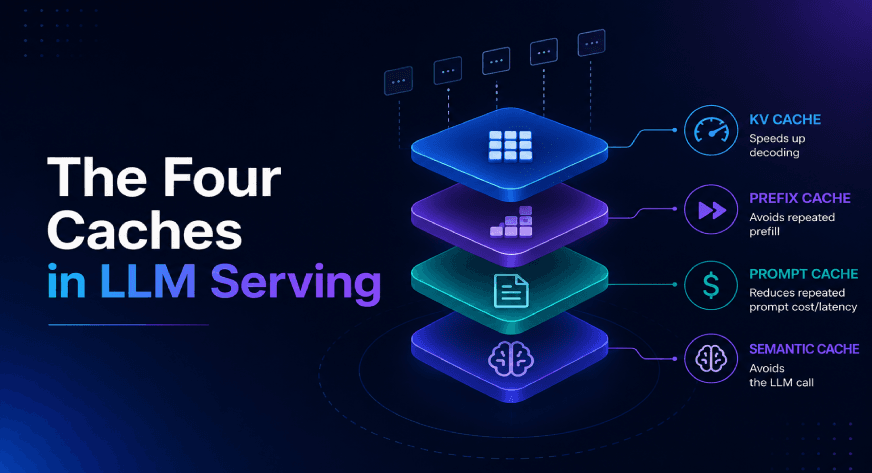
Caching is essential in large language model (LLM) applications to reduce inference costs and latency by avoiding redundant processing of tokens. Four specific caching strategies are identified to optimize performance.
✦ Why It Matters
Implement caching strategies in your LLM applications today to enhance performance and reduce costs.
Key Takeaways
How It Works
KV caching stores Key and Value tensors in memory to prevent recomputation during token generation. Prefix caching identifies shared prompt segments and reuses their KV states, while prompt caching allows API providers to cache common prompt content.
Semantic caching uses embeddings to compare new queries against previously answered questions, enabling the reuse of answers without invoking the LLM.
Related