Accelerating the search for antimicrobial peptides with Google Antigravity
deepmind.google·3d ago
TL;DR
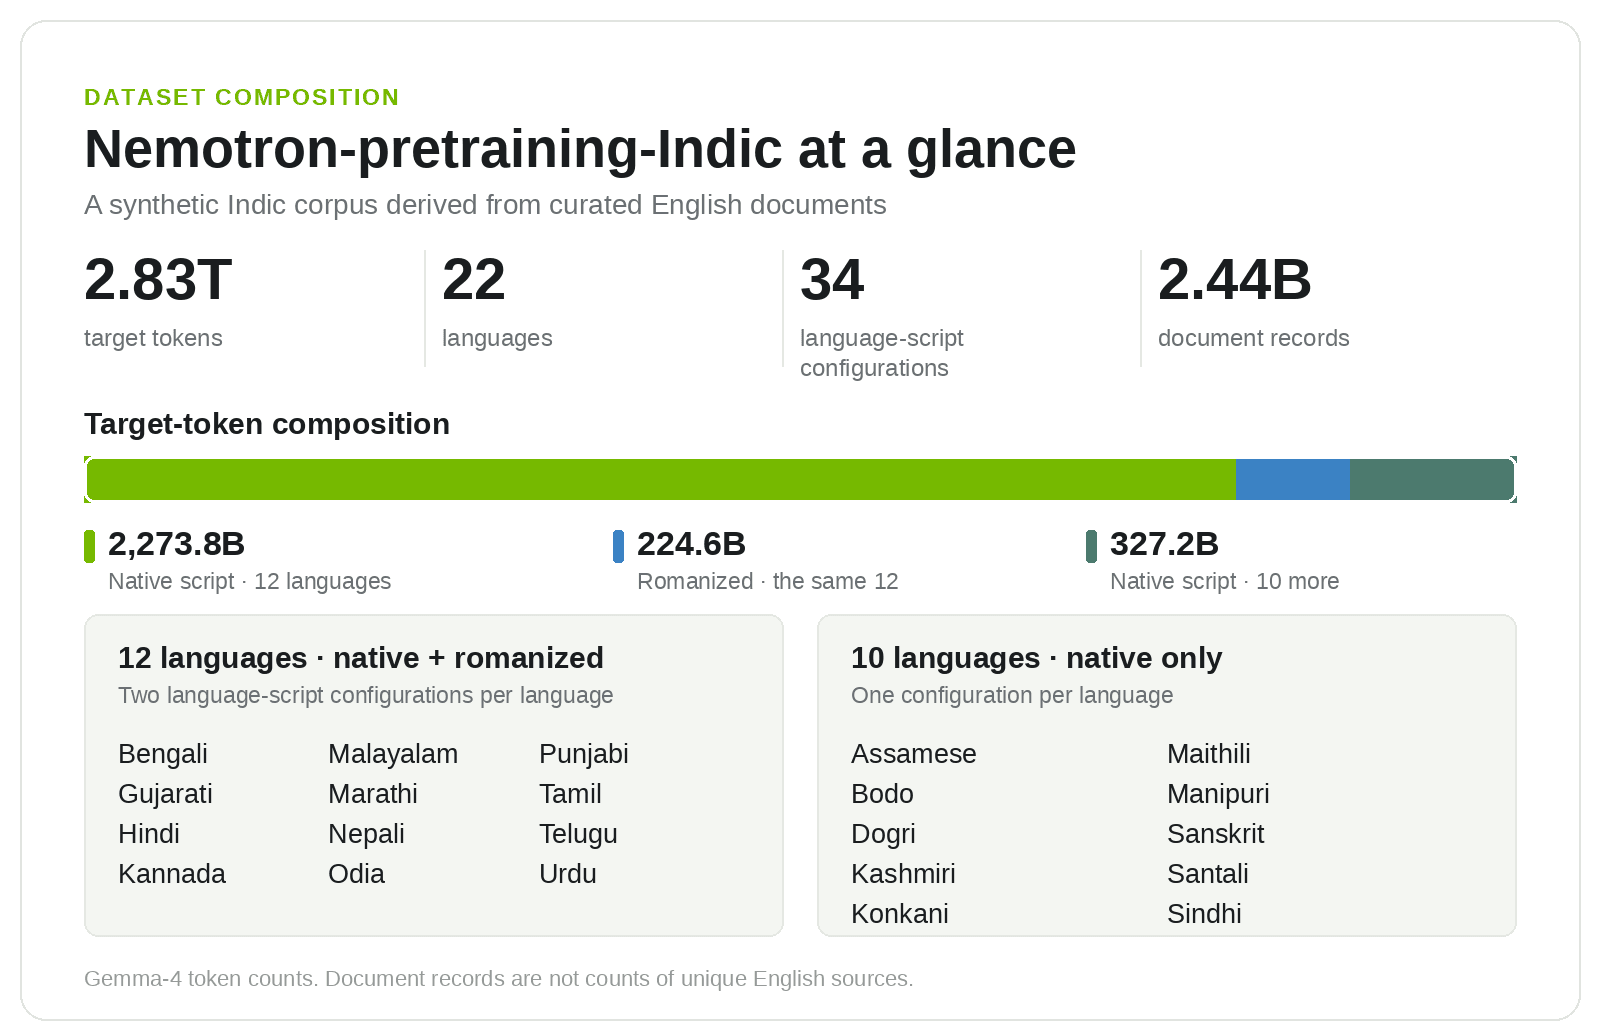
Nemotron-pretraining-Indic-v1 introduces a massive dataset of 2.8 trillion tokens across 22 Indian languages, enhancing resources for Indic language model training. This initiative aims to bridge the data gap in Indian language technology.
✦ Why It Matters
Start using the Nemotron-pretraining-Indic-v1 dataset to enhance your Indic language models today.
Key Takeaways
How It Works
The data generation pipeline employs a four-stage process: translating English documents, assessing translation quality, repairing low-quality outputs, and converting accepted translations into romanized text. This ensures high-quality synthetic data while maintaining traceability to original documents.
Related