Agentic data science with the Data Agent Kit
cloud.google.com·7h ago
TL;DR
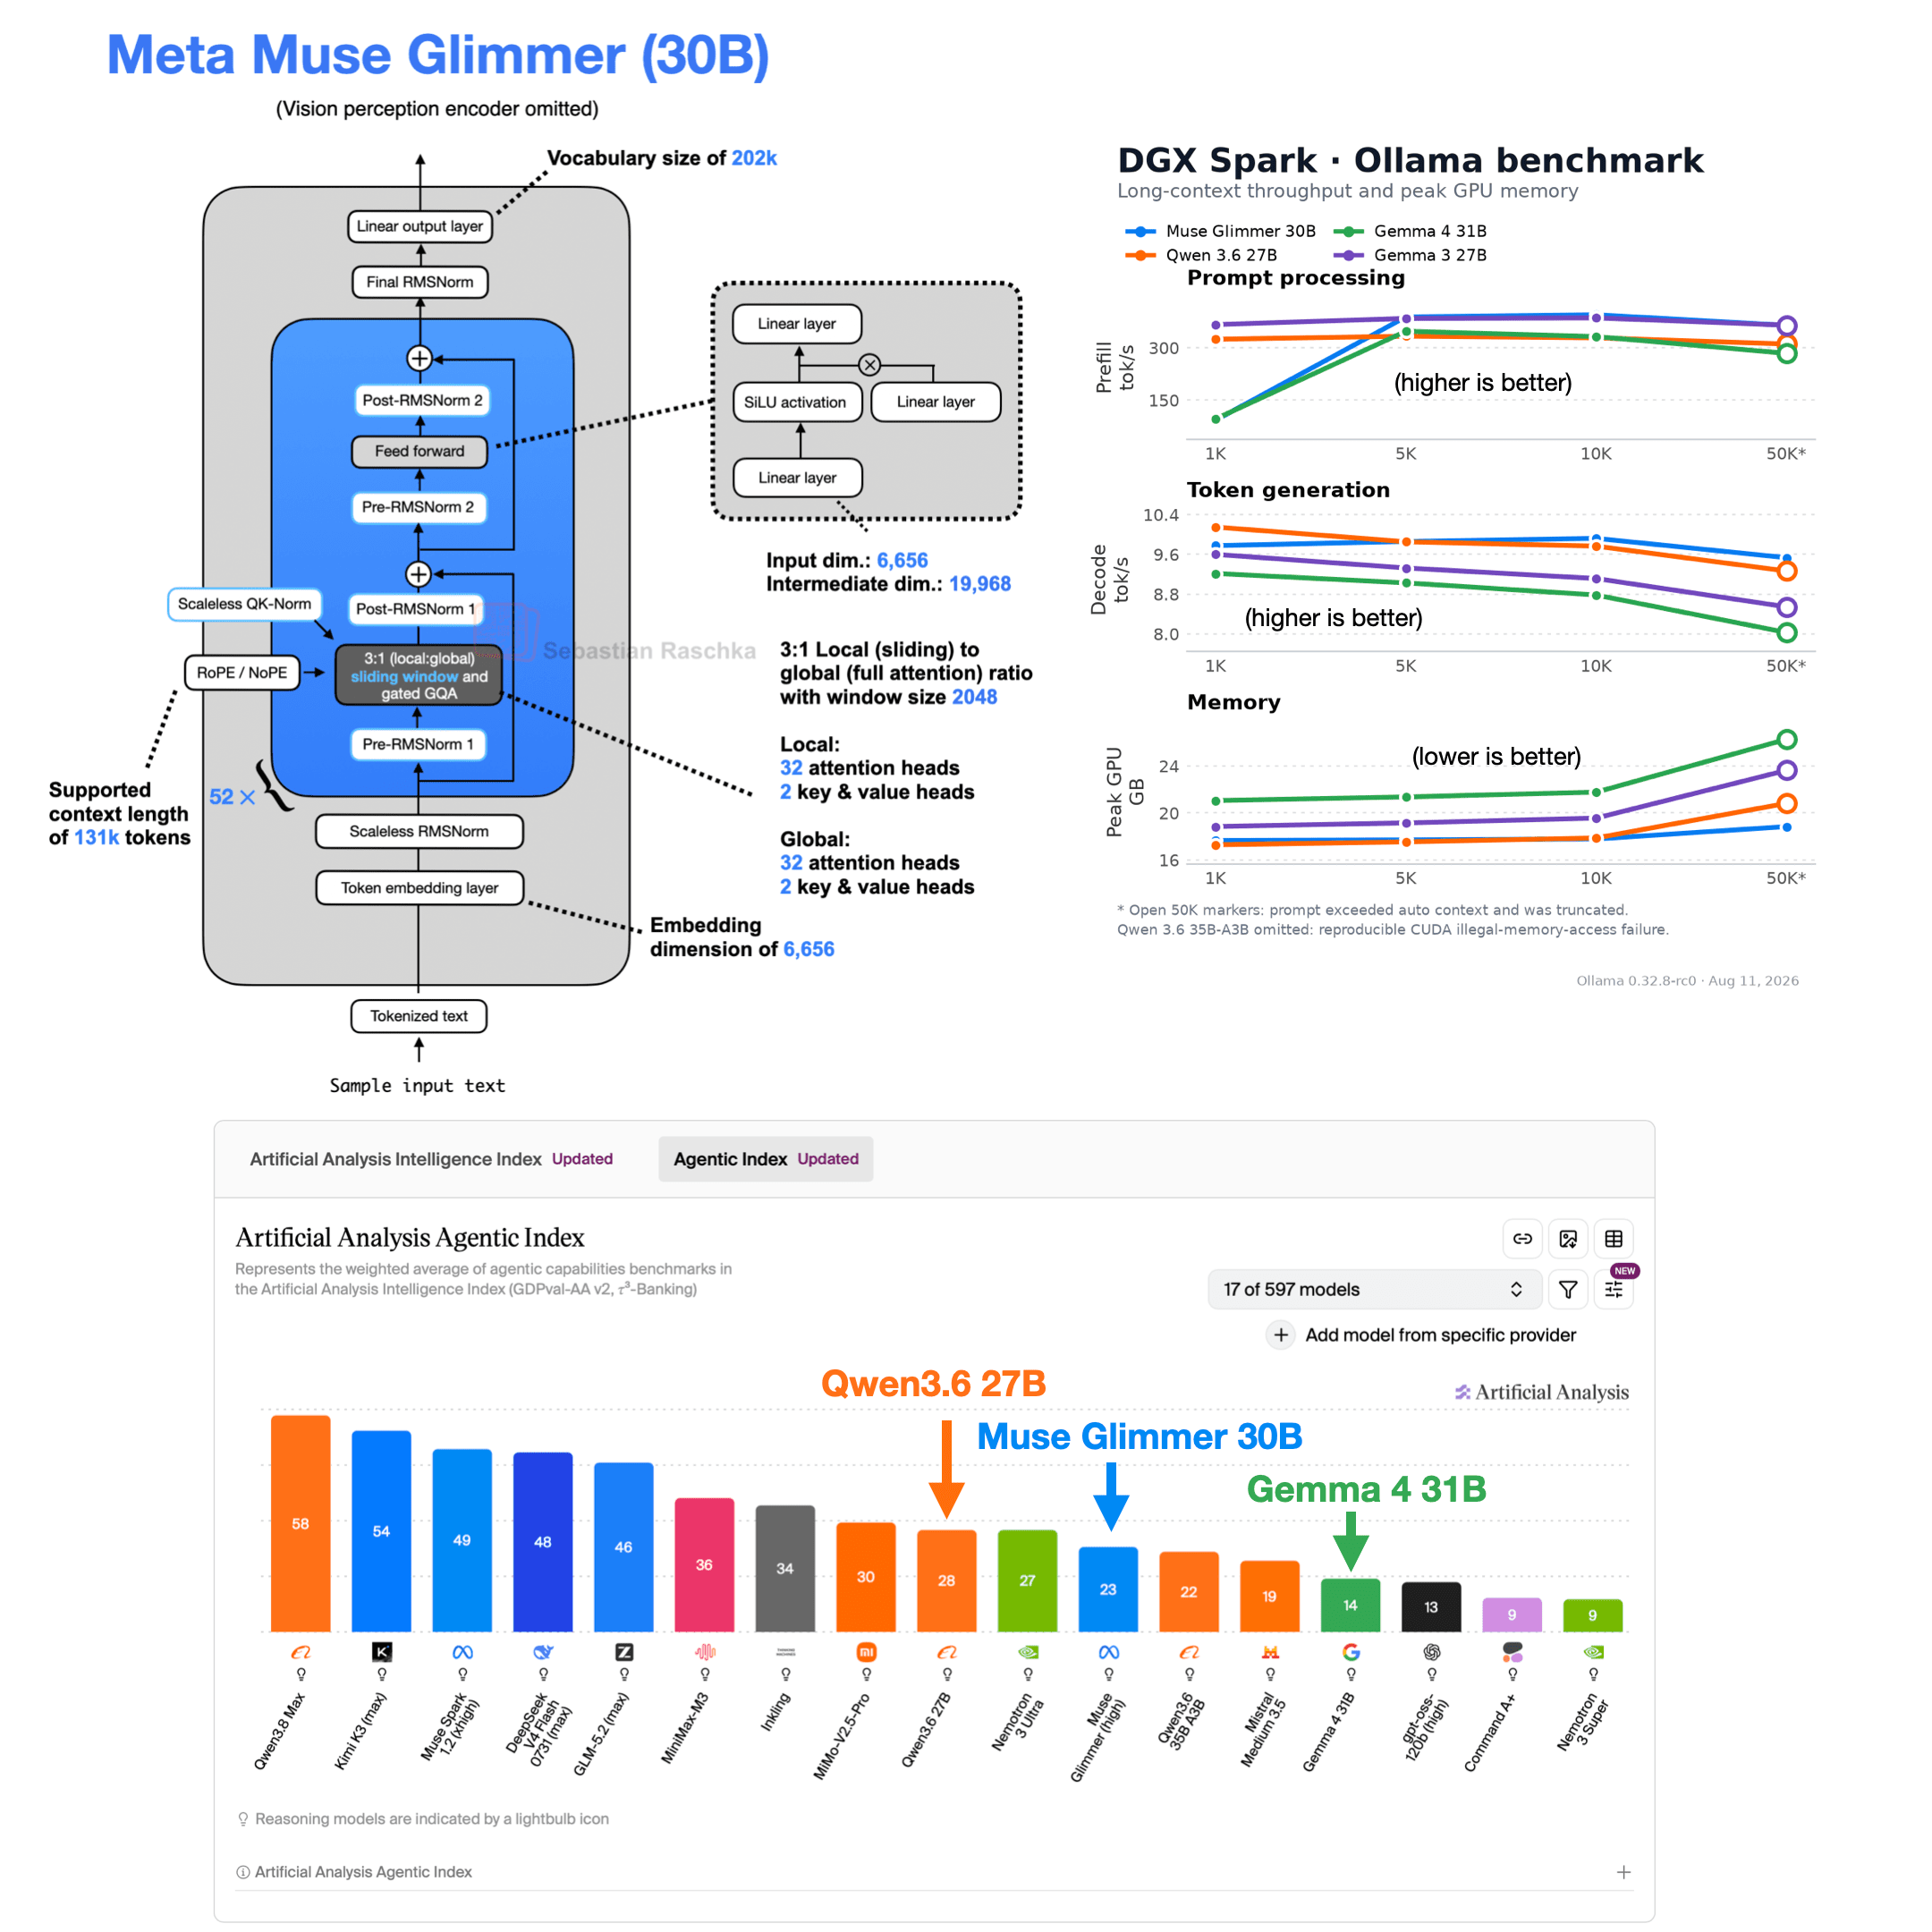
Meta's Muse Glimmer 30B introduces an advanced architecture featuring gated local and global GQA (Global Query Attention) and improved KV-cache efficiency, enhancing performance benchmarks significantly.
✦ Why It Matters
Consider integrating Muse Glimmer 30B into your AI projects for improved performance and efficiency.
Key Takeaways
How It Works
Muse Glimmer employs a hybrid attention mechanism that combines grouped-query attention (GQA) and sliding window attention (SWA). This design allows it to efficiently manage context and memory, with a unique 3:1 local-to-global attention ratio.
Gated attention is applied to control the flow of information, enhancing the model's performance by determining how much attention data is retained in the residual connections.
Related