Agentic data science with the Data Agent Kit
cloud.google.com·7h ago
TL;DR
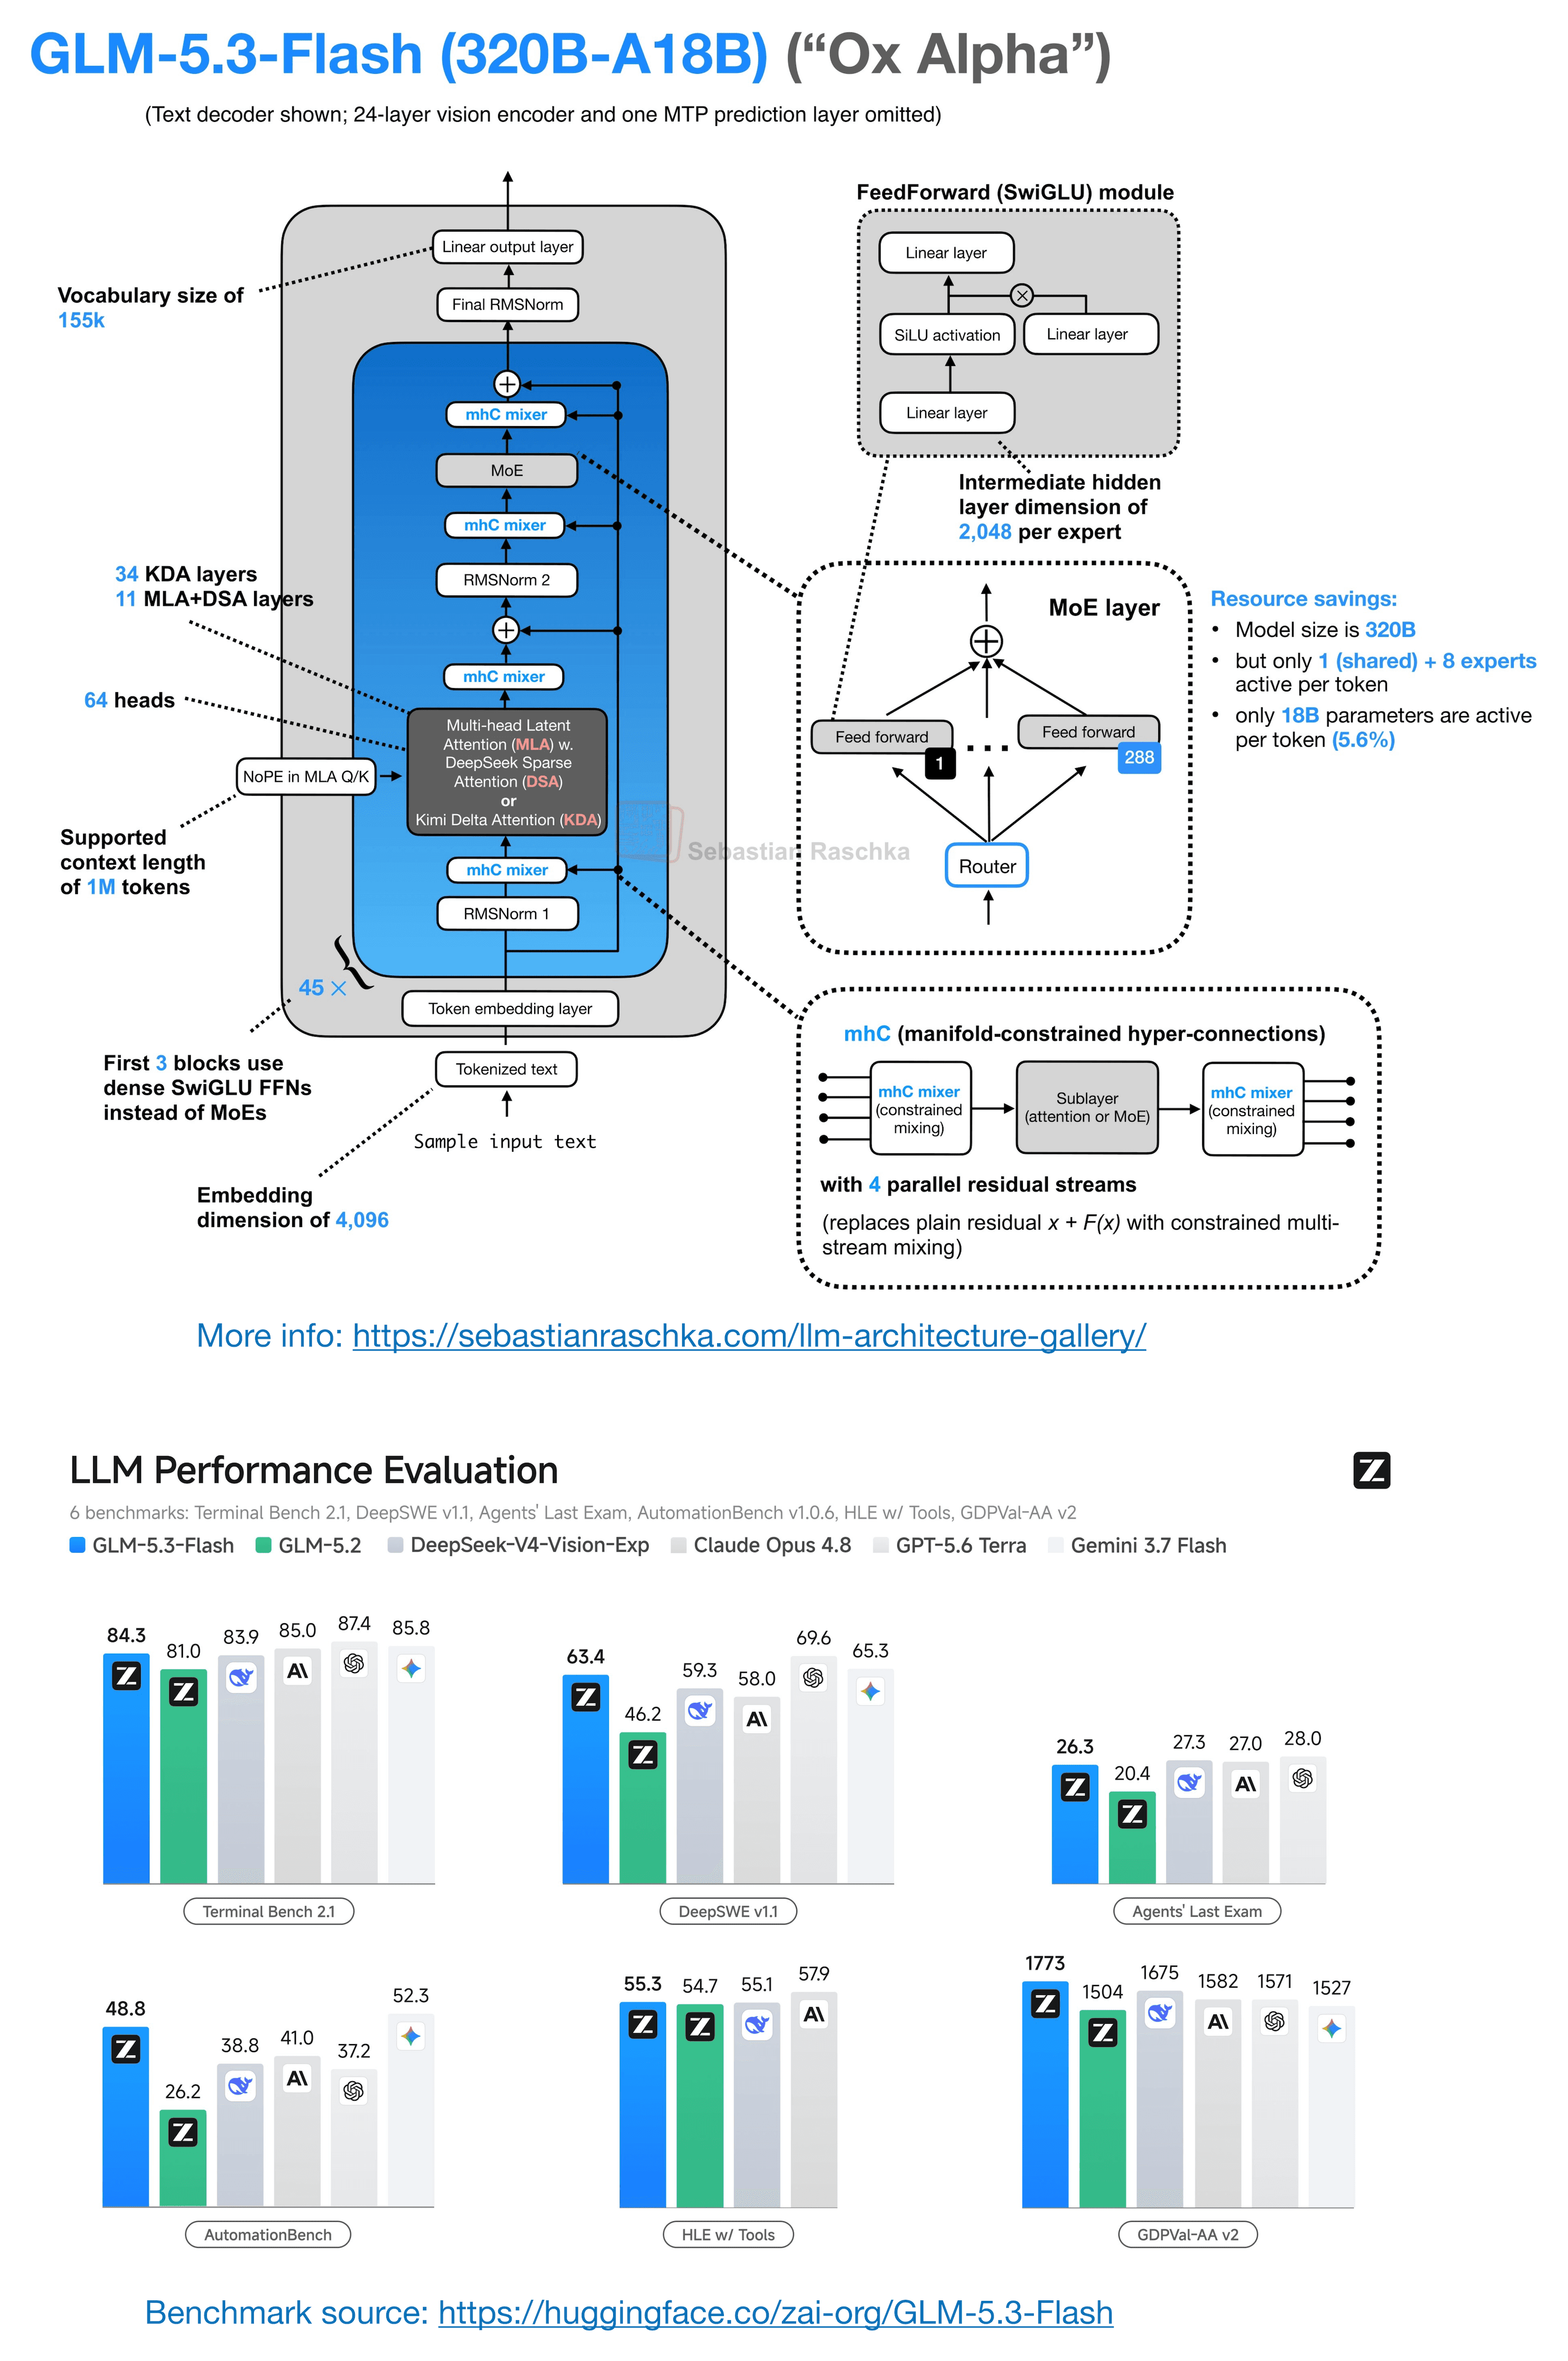
GLM-5.3-Flash introduces a hybrid attention mechanism combining KDA and MLA/DSA, supported by a sparse MoE backbone and a four-stream mHC residual path, enhancing model efficiency.
✦ Why It Matters
Explore implementing hybrid attention mechanisms in your next AI project to enhance efficiency.
Key Takeaways
Full Summary
GLM-5.3-Flash is an evolution of the GLM-5.2 model, designed to improve efficiency in large language models (LLMs). It incorporates a Kimi Linear-style 3:1 hybrid attention pattern, which combines 34 Kimi Delta Attention (KDA) layers with 11 Multi-head Latent Attention (MLA) and DeepSeek Sparse Attention (DSA) layers.
The model's backbone has been scaled down from 744 billion parameters to 320 billion, optimizing performance while maintaining capability. Additionally, it features a DeepSeek V4-style mHC residual path with four parallel streams and includes a native vision encoder.
These innovations aim to enhance the model's efficiency and versatility in processing both text and visual data.
Related