Agentic data science with the Data Agent Kit
cloud.google.com·6h ago
TL;DR
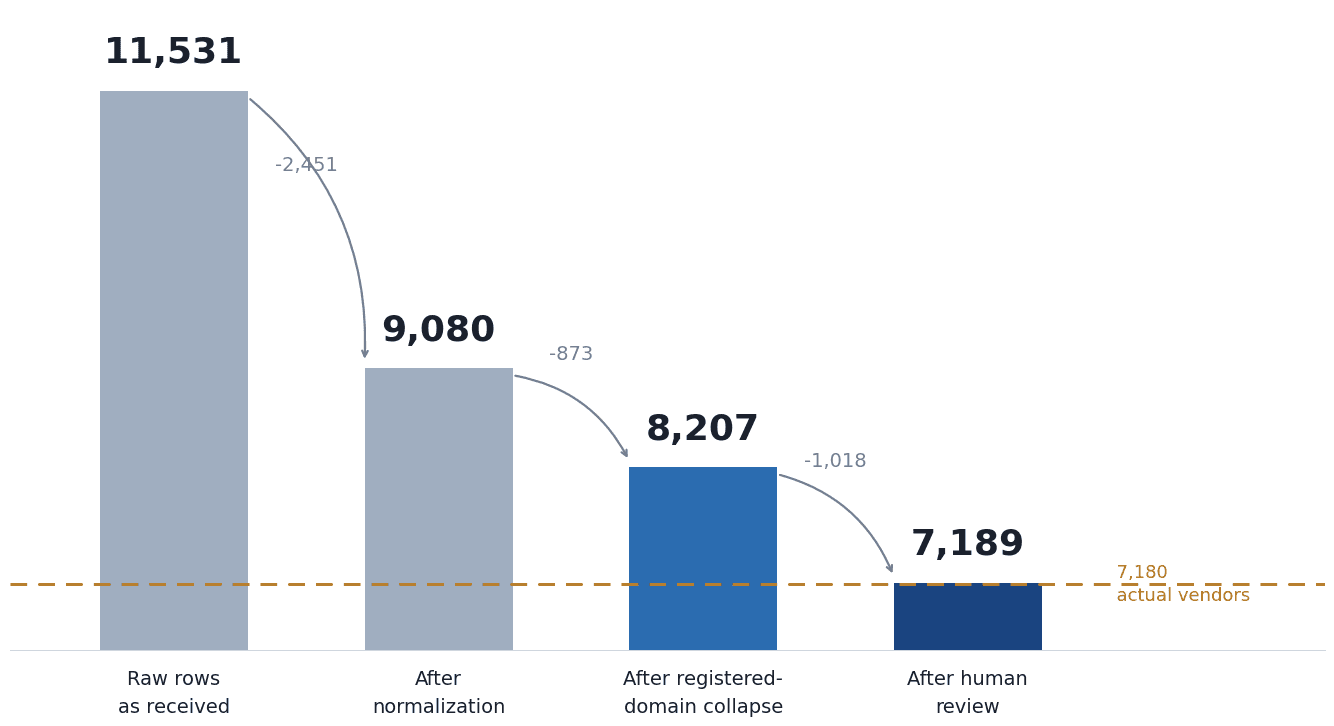
A Python-based approach effectively deduplicates a 10,000-row supplier list by using deterministic stages instead of relying solely on similarity scores. This method improves accuracy in identifying unique entries despite variations in spelling.
✦ Why It Matters
Implement deterministic stages in your data deduplication processes to enhance accuracy and reliability.
Key Takeaways
How It Works
The pipeline consists of two main stages: normalization, which standardizes vendor names by converting them to lowercase and removing unnecessary components, and subdomain collapsing, which consolidates records based on registered domains using the Public Suffix List. This approach effectively reduces the number of duplicates before applying similarity scoring.
⚠ The Catch
Despite the efficiency of the pipeline, many ambiguous pairs remained, particularly those with similar names across different country domains, necessitating human intervention for accurate resolution.
Related