EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
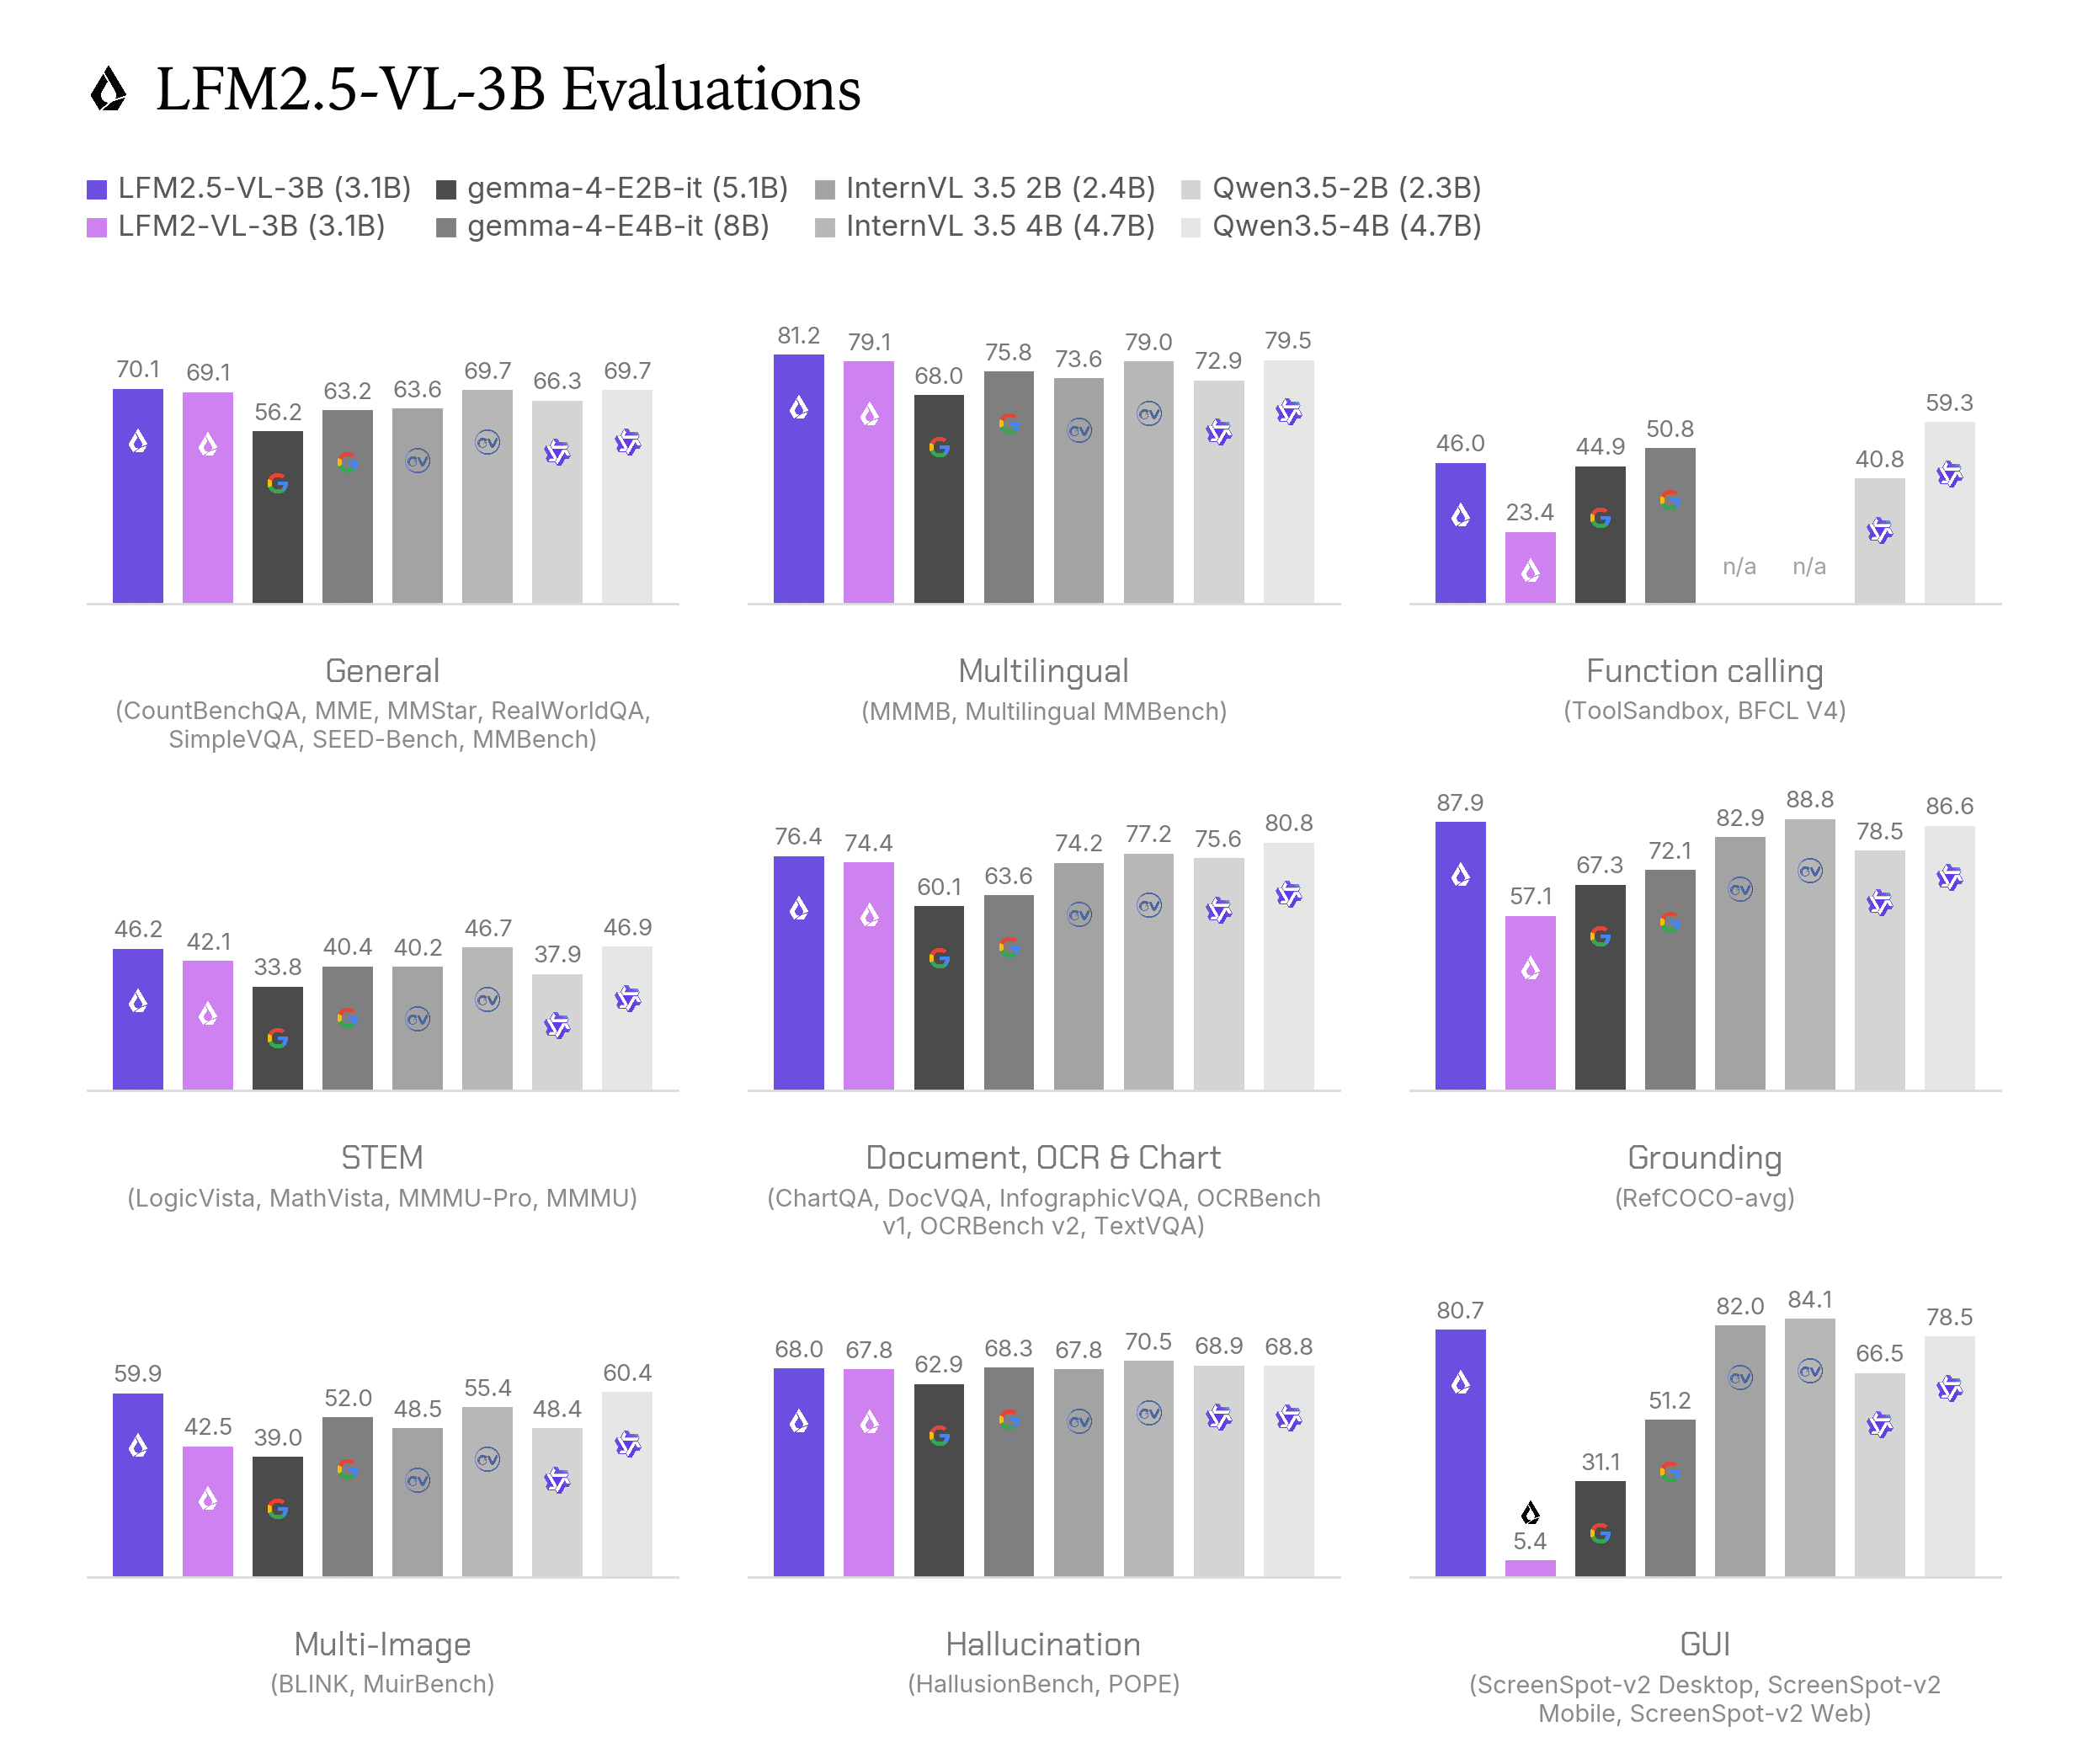
LFM2.5-VL-3B enhances vision-language capabilities with improved screen understanding, grounding, multi-image reasoning, and function calling, making it more effective for edge applications.
✦ Why It Matters
Integrate LFM2.5-VL-3B into your applications to enhance user interaction with visual data today.
Key Takeaways
How It Works
LFM2.5-VL-3B combines a vision encoder with a pre-trained text model, allowing it to process and understand both images and text. The model's architecture supports improved grounding, enabling it to accurately detect and describe objects based on natural language queries.
Its training on a vast dataset enhances its ability to handle diverse visual tasks, including reading digital content and performing complex reasoning across multiple images.
Related