EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
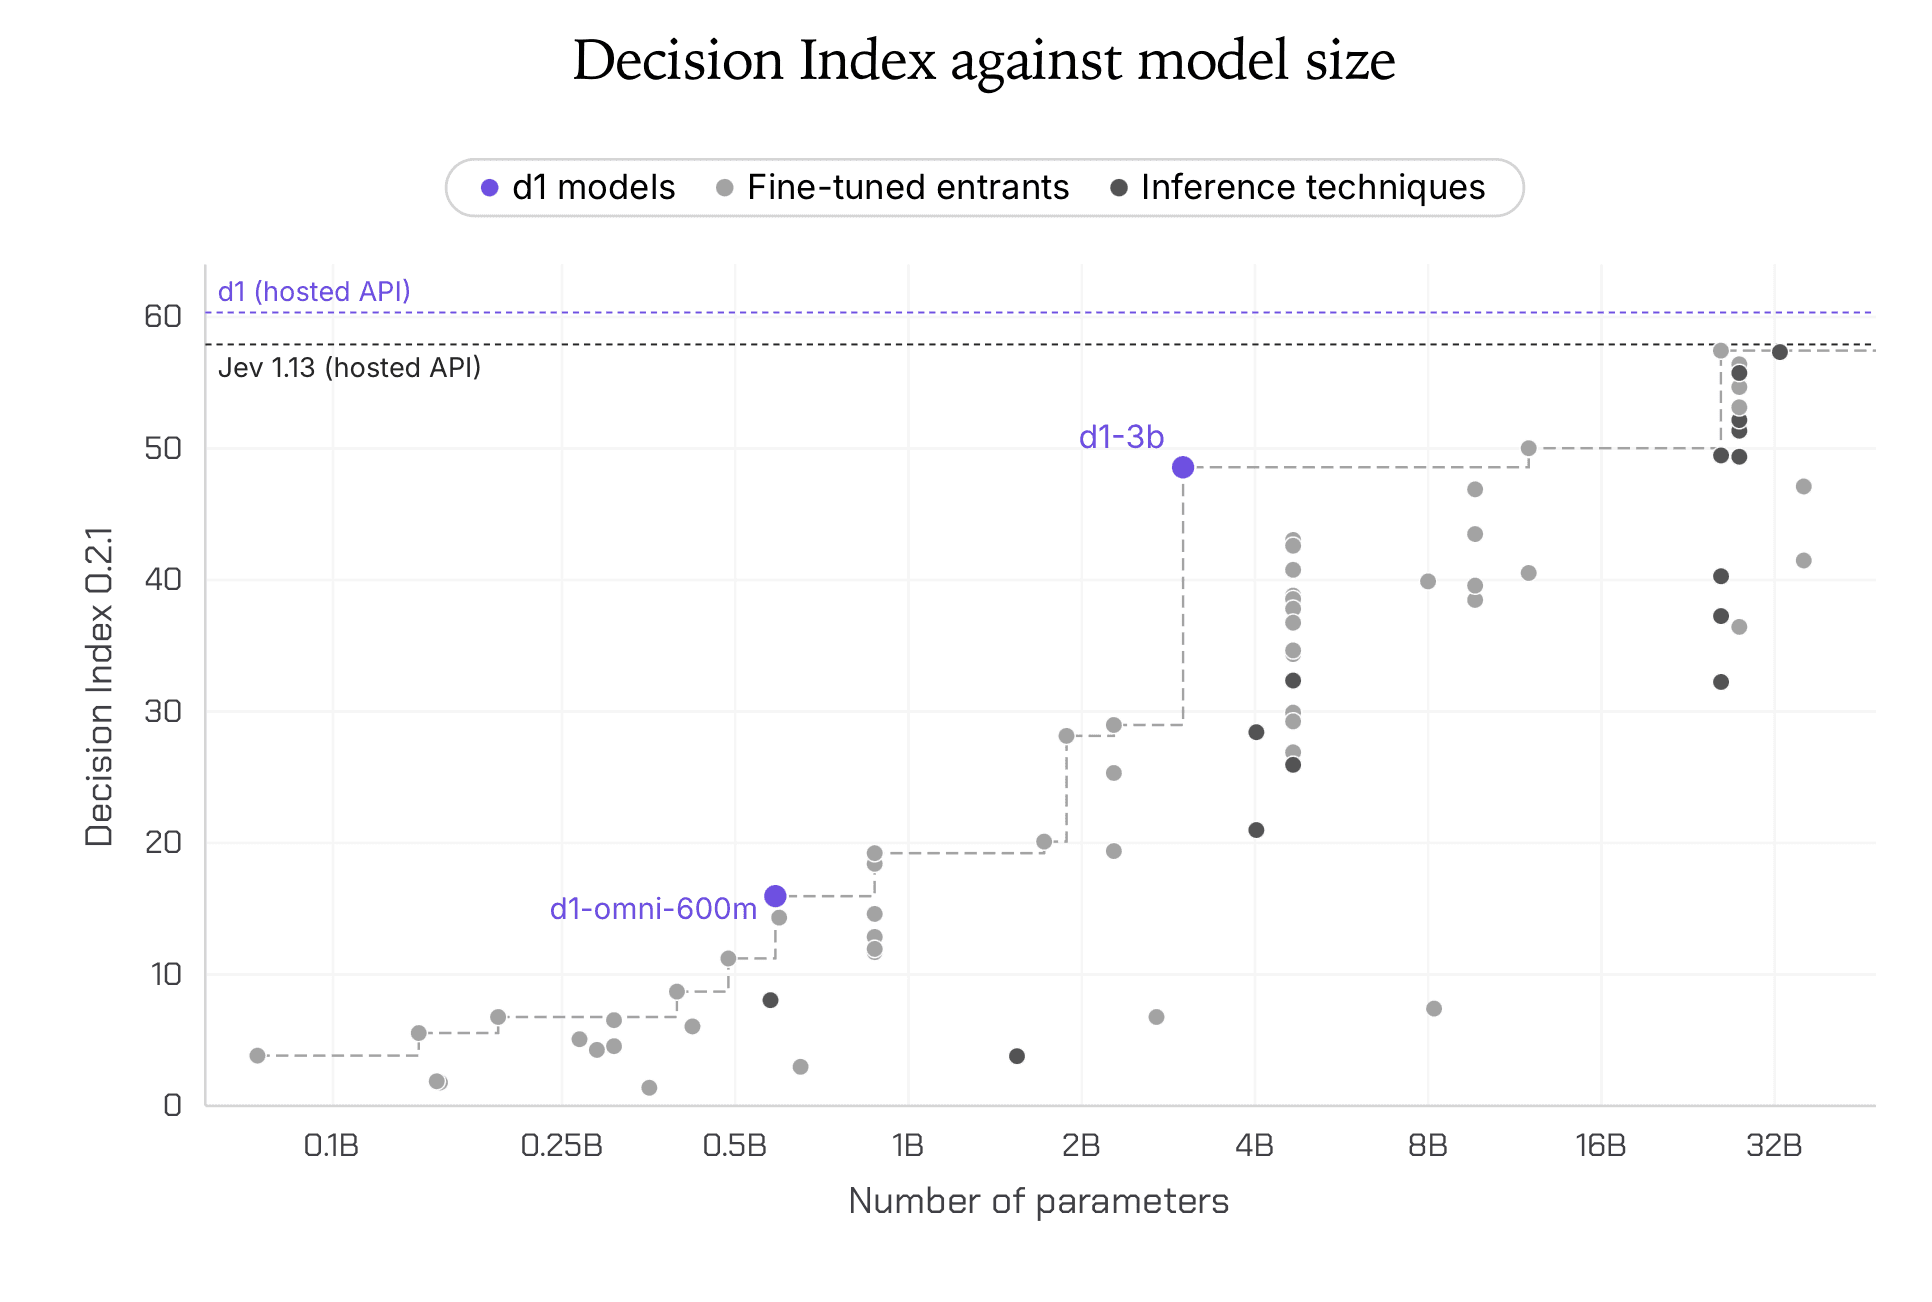
Hugging Face has introduced two multimodal decision models, d1-3B and d1-omni-600M, achieving top scores in decision-making tasks while processing inputs rapidly. d1-3B excels with a score of 82.9 on the Decision Index, outperforming larger models.
✦ Why It Matters
Developers can implement d1-3B for high-quality, fast decision-making in their applications today.
Key Takeaways
Full Summary
Hugging Face's new d1 decision models, d1-3B and d1-omni-600M, are designed for fast, structured decision-making using multimodal inputs, including text, images, and audio. d1-3B, a 3 billion parameter model, achieved a score of 82.9 on the Decision Index, outperforming larger models like Decider 35B-A3B. It processes questions in under 50 milliseconds on various NVIDIA devices, while d1-omni-600M, a smaller model with 600 million parameters, supports both text and images or text and audio.
Both models were benchmarked across seven datasets, with d1-3B showing superior performance in reading comprehension and intent classification. These models are built on Liquid Foundation Models (LFMs) and are available for public use, enabling developers to integrate advanced decision-making capabilities into their applications.
Related