EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
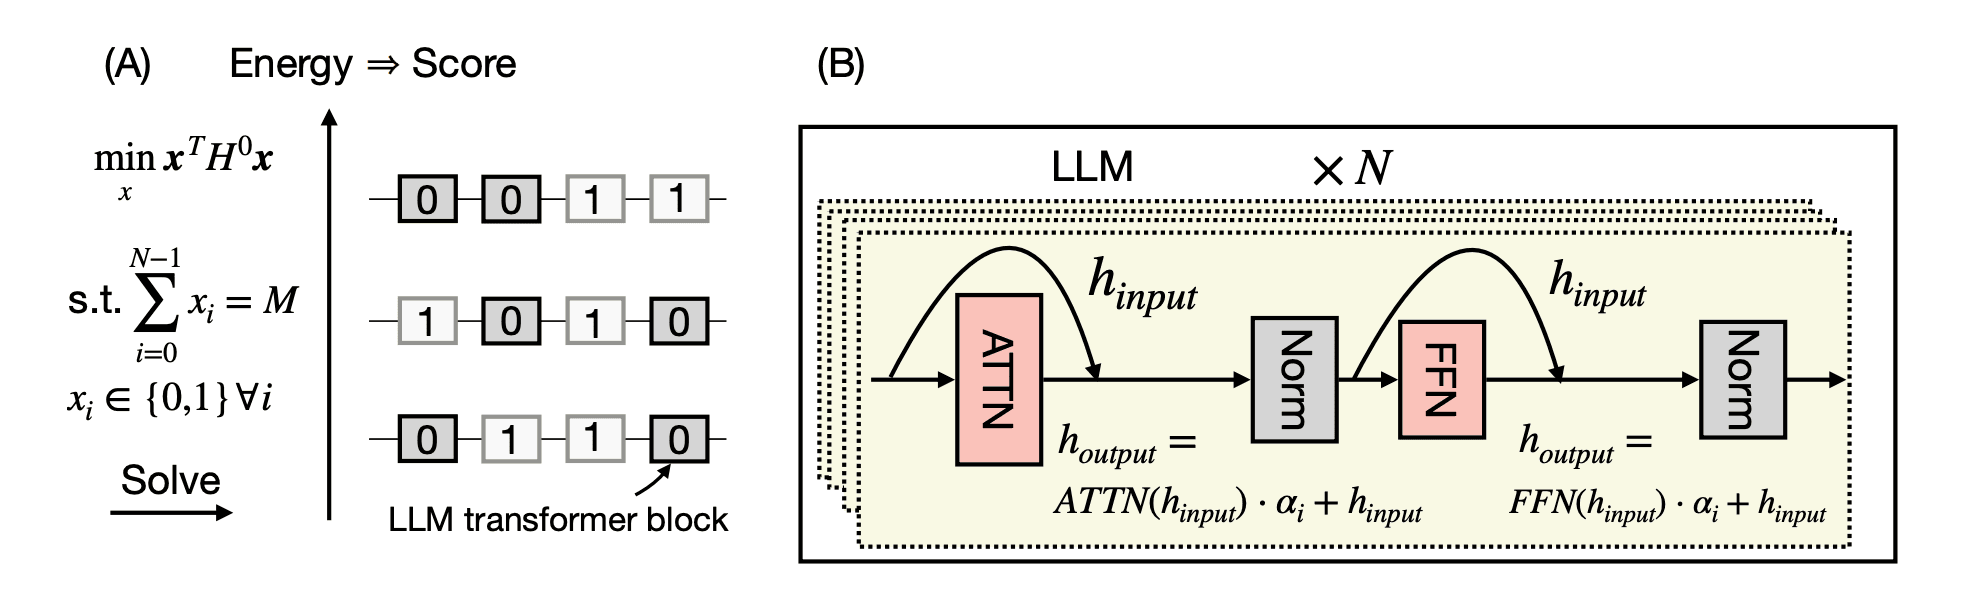
A new method for pruning large language models (LLMs) reformulates block selection as a constrained binary optimization problem, significantly improving model performance. This approach achieved a 23 percentage point increase on MMLU benchmarks at 50% compression of Llama-3.3-70B-Instruct.
✦ Why It Matters
Consider adopting constrained binary optimization techniques for model pruning to enhance performance significantly.
Key Takeaways
How It Works
The method reformulates block selection as a constrained binary optimization problem, using a Hessian matrix to capture both individual block importance and their interactions. This allows for efficient exploration of block combinations, leading to optimal pruning configurations.
Related