EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
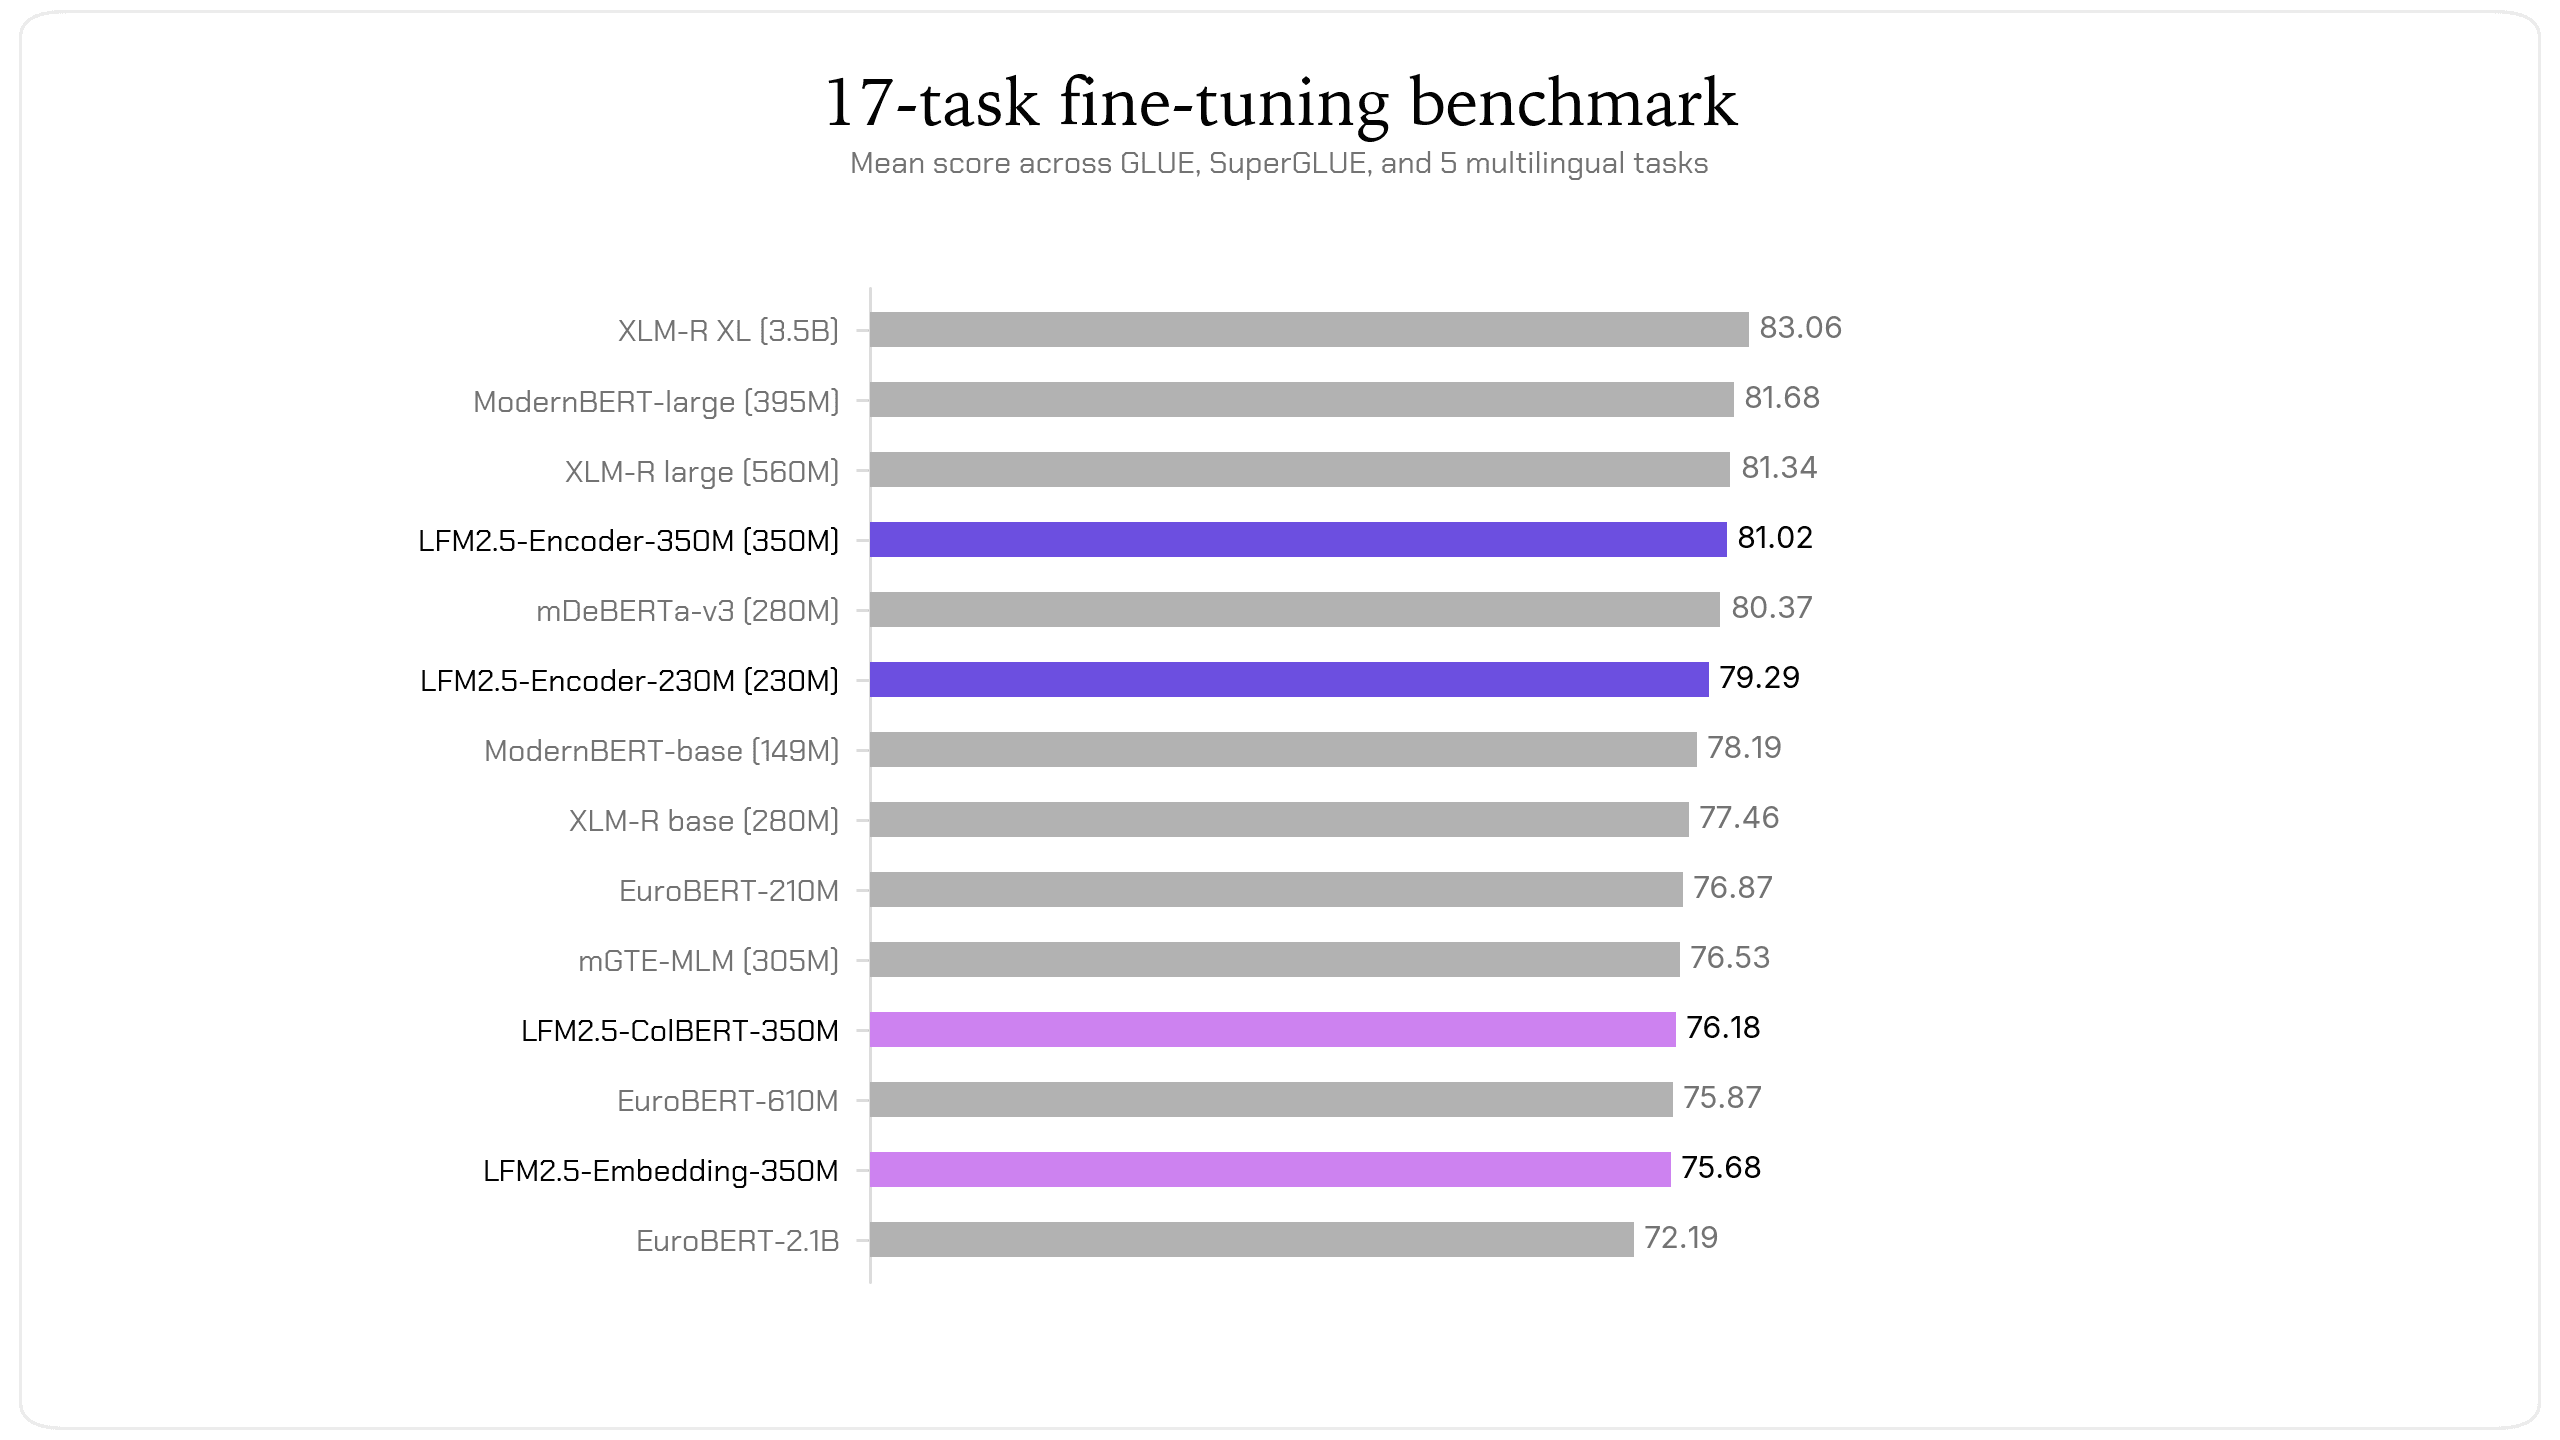
LFM2.5-Encoders are new models that outperform larger encoders on various benchmarks while offering fast inference on CPUs with an 8,192-token context. They enable efficient applications like intent routing and text classification.
✦ Why It Matters
Start integrating LFM2.5-Encoders into your applications for efficient long-context processing today.
Key Takeaways
How It Works
LFM2.5-Encoders leverage a bidirectional attention mechanism, allowing each token to consider its surrounding context. They are trained using a two-stage process: first, they develop general language skills with a masked-language objective, and then they adapt to long contexts by extending their training to 8,192 tokens.
This architecture enables efficient processing of lengthy inputs while maintaining high accuracy.
Related