EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
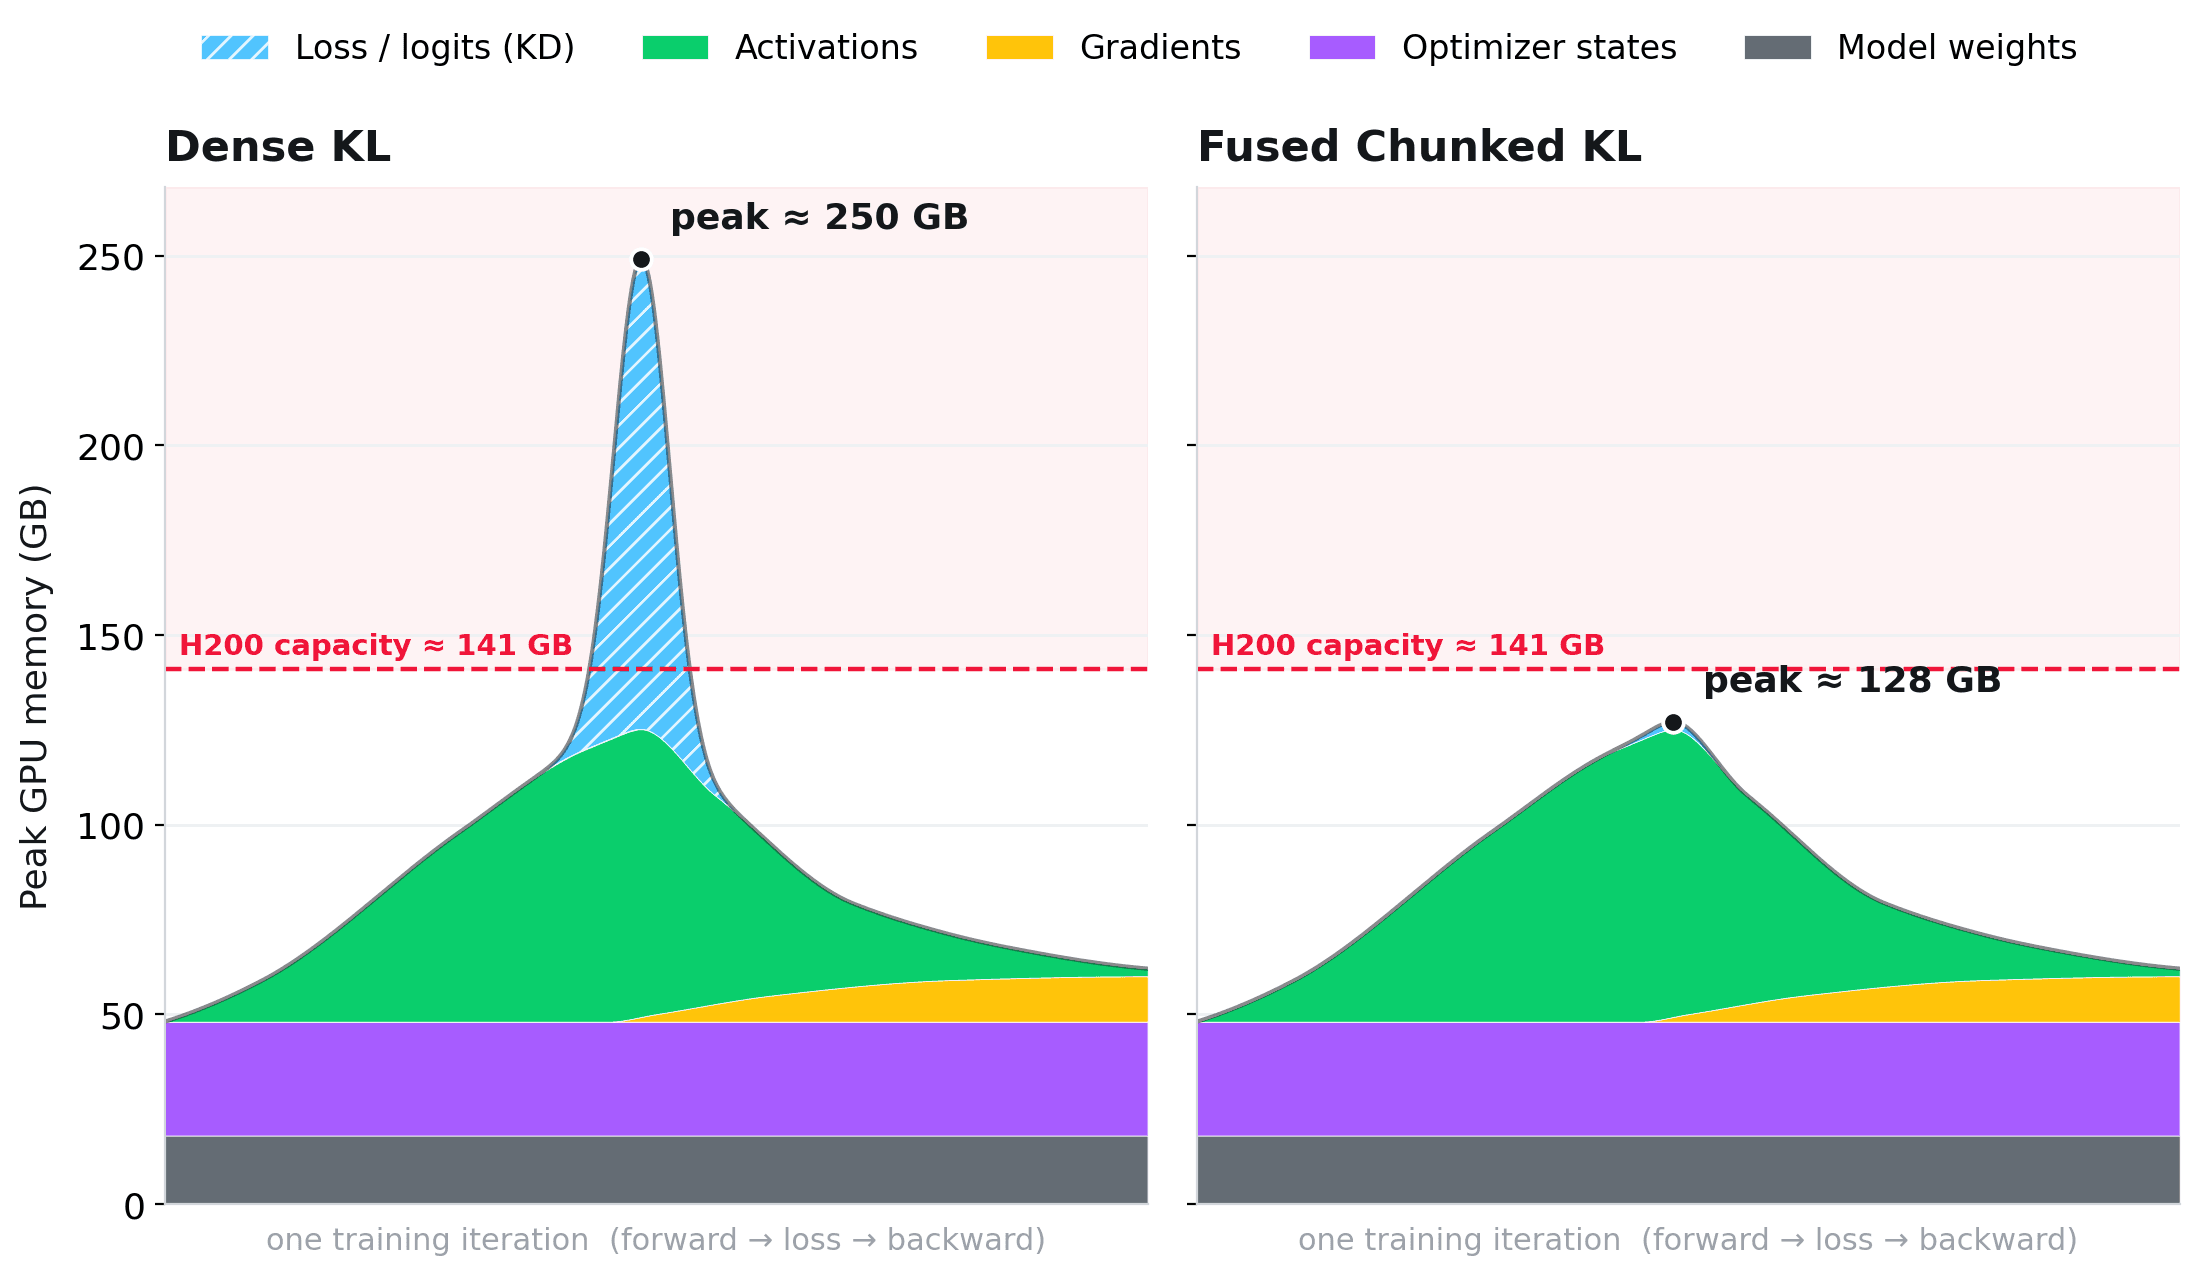
Efficient Knowledge Distillation techniques have been developed to significantly reduce the VRAM requirements for training large language models, enabling single-GPU training. This advancement makes large-scale experimentation more feasible and cost-effective.
✦ Why It Matters
Implement these techniques to reduce VRAM costs and enable efficient training of large models on single GPUs.
Key Takeaways
How It Works
The method caches the teacher model's top-100 logits, allowing the student to train against this fixed output rather than recalculating it at every step. The fused chunked KL loss processes the student's predictions in smaller segments, avoiding the need to hold large tensors in memory, thus optimizing VRAM usage.
Related