EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
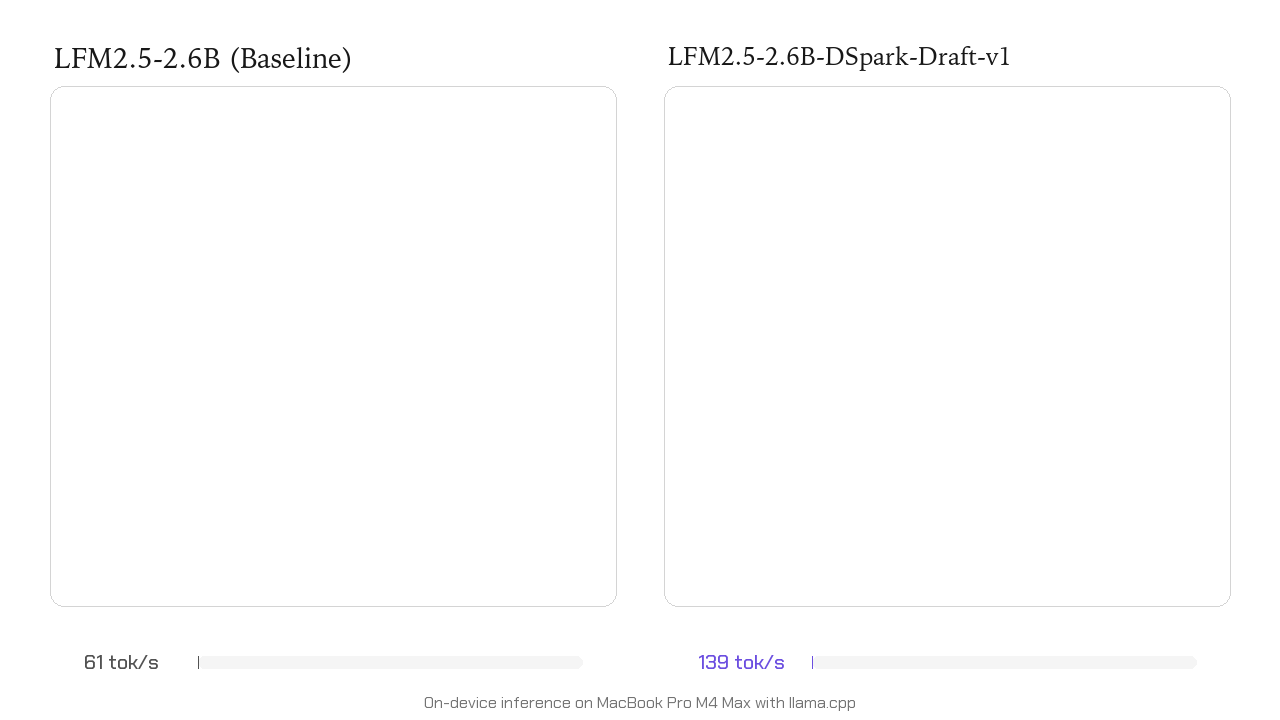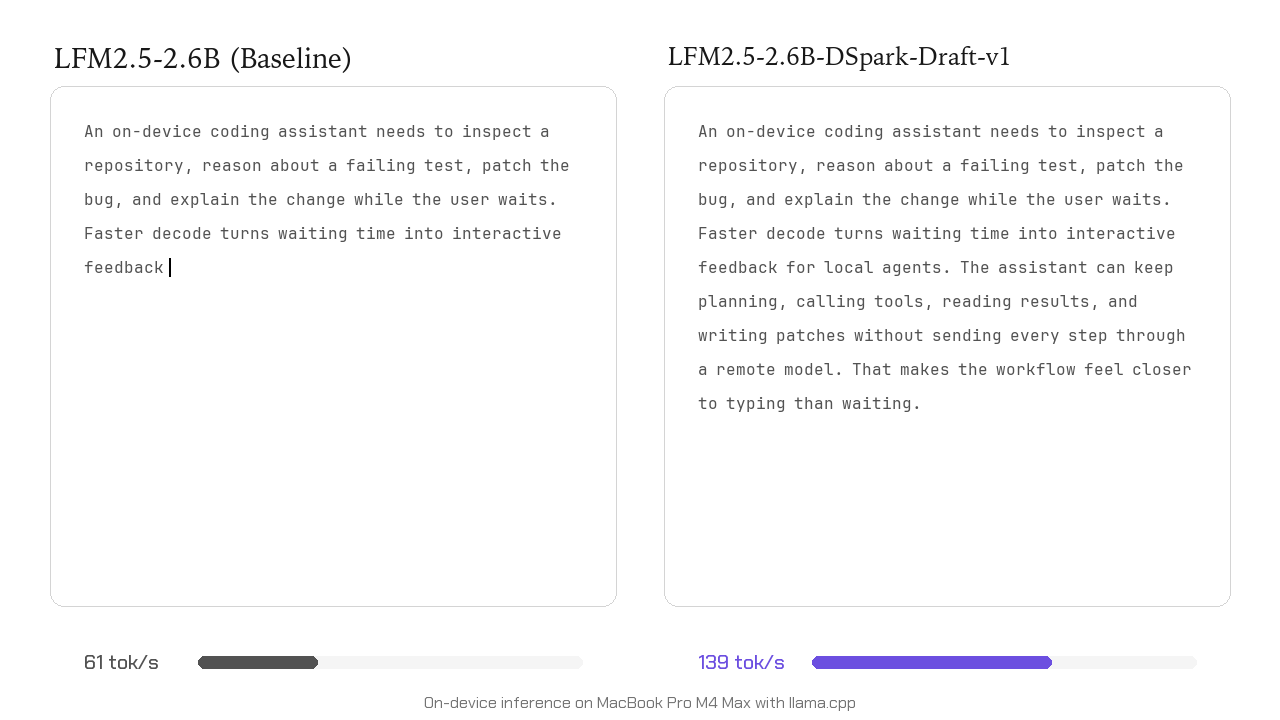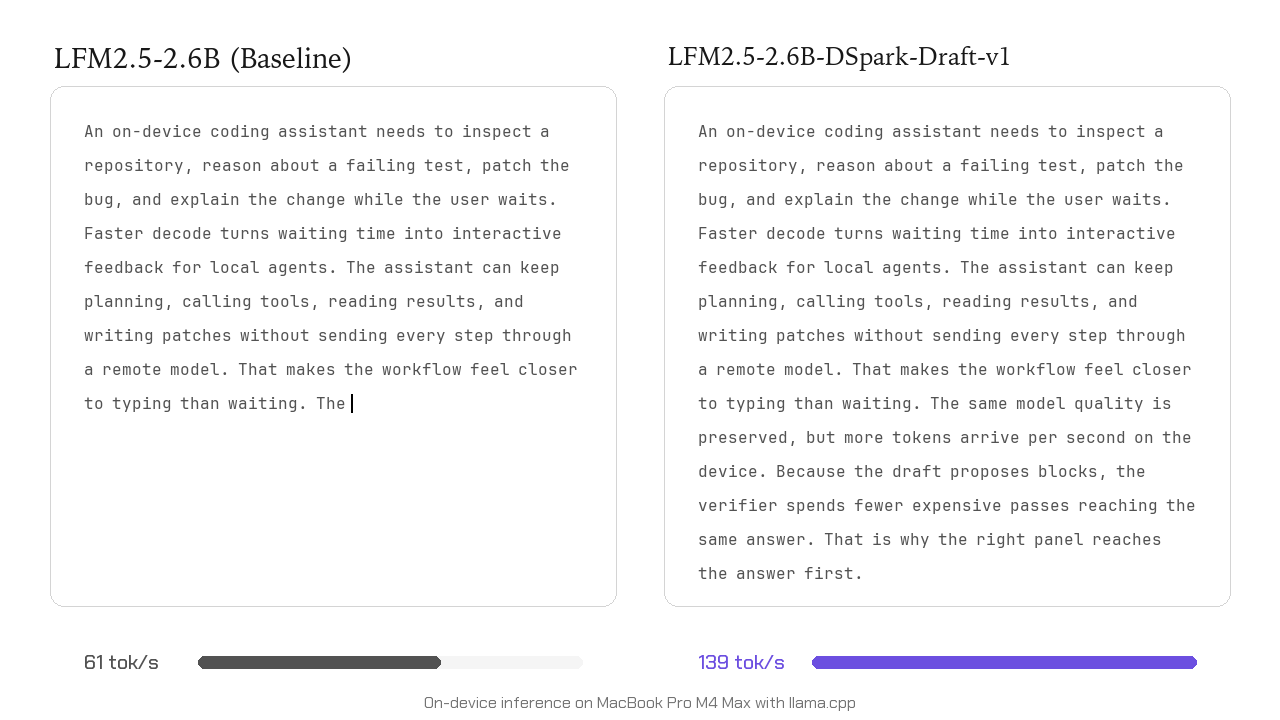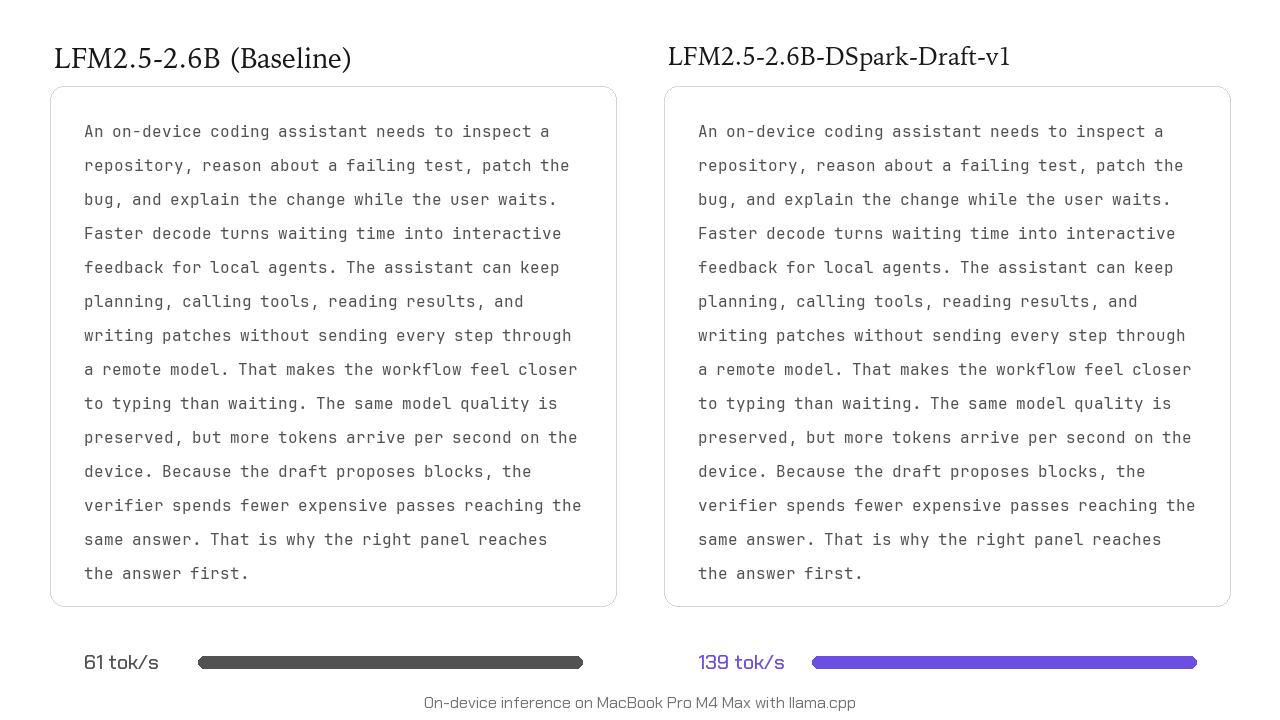
LFM2.5-DSpark achieves up to 3.2x faster inference for large language models (LLMs) by reducing latency and improving throughput on GPUs and devices. This advancement supports on-device agentic inference and integrates with llama.cpp and SGLang.
✦ Why It Matters
Implement LFM2.5-DSpark to enhance your LLM inference speed and reduce latency in your applications.
Key Takeaways
How It Works
LFM2.5-DSpark employs speculative decoding, which generates candidate tokens using a lightweight draft model. This draft model produces hidden states for all tokens in a single forward pass, allowing the main model to verify them efficiently.
The architecture includes a Markov chain-based head to maintain inter-token dependencies and a confidence-scheduled verifier that prunes low-confidence tokens, optimizing the overall inference process.
Related