EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
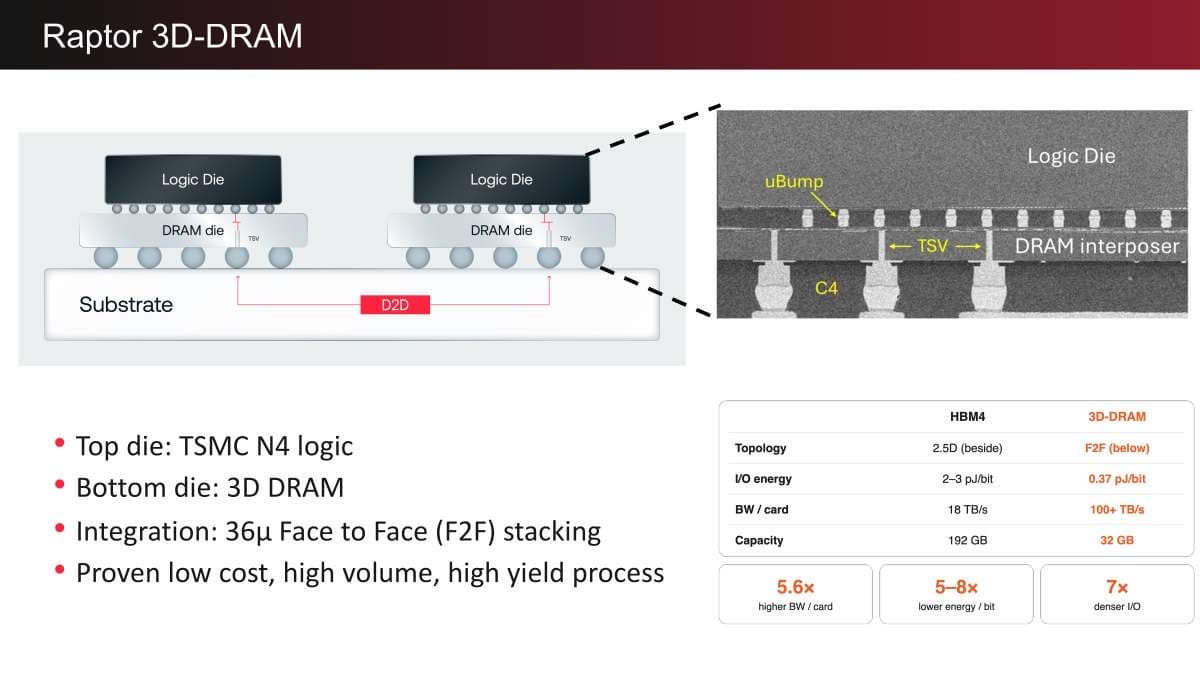
d-Matrix unveiled its Raptor 3D-DRAM accelerator designed for generative inference, addressing the growing demands of model weights and KV cache. This innovation aims to tackle both capacity and bandwidth challenges in AI inference workloads.
✦ Why It Matters
Evaluate your current infrastructure to see if it can support the growing demands of generative AI models.
Key Takeaways
How It Works
Raptor stacks compute logic on top of DRAM dies, allowing for high bandwidth and low power consumption. It employs stream blocking to optimize memory access, ensuring efficient data flow and minimizing bandwidth waste.
Related