EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
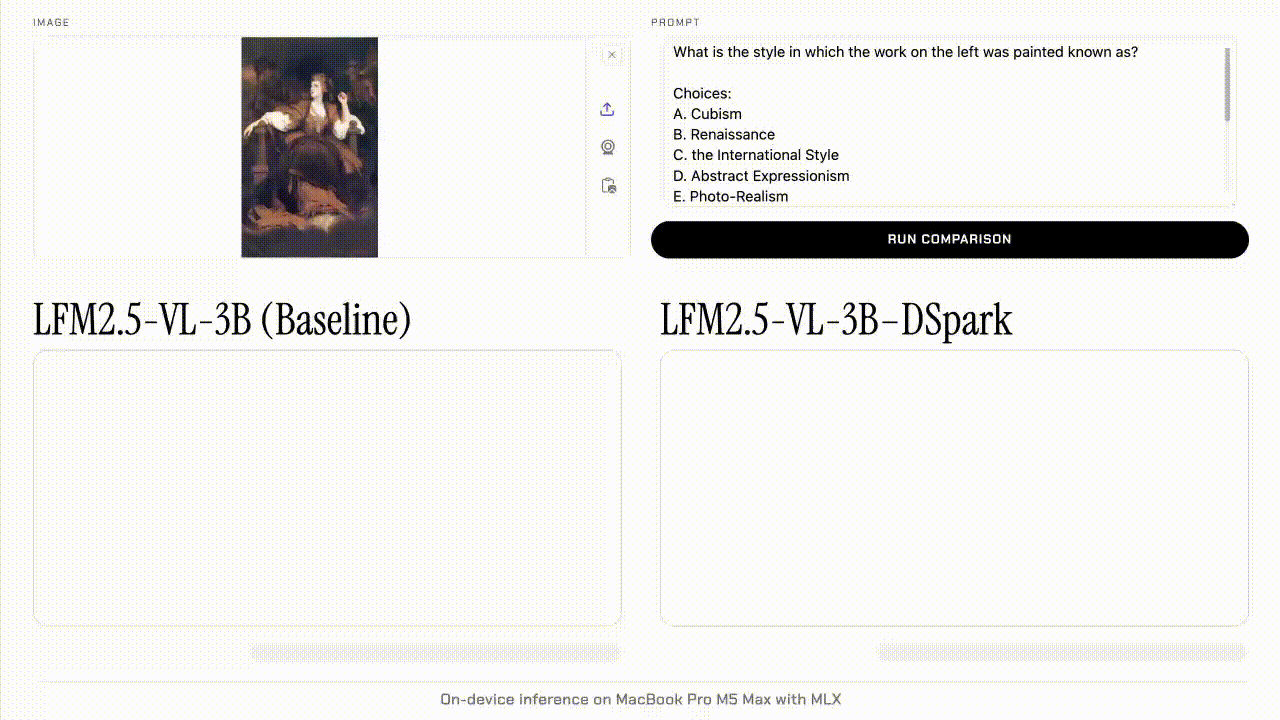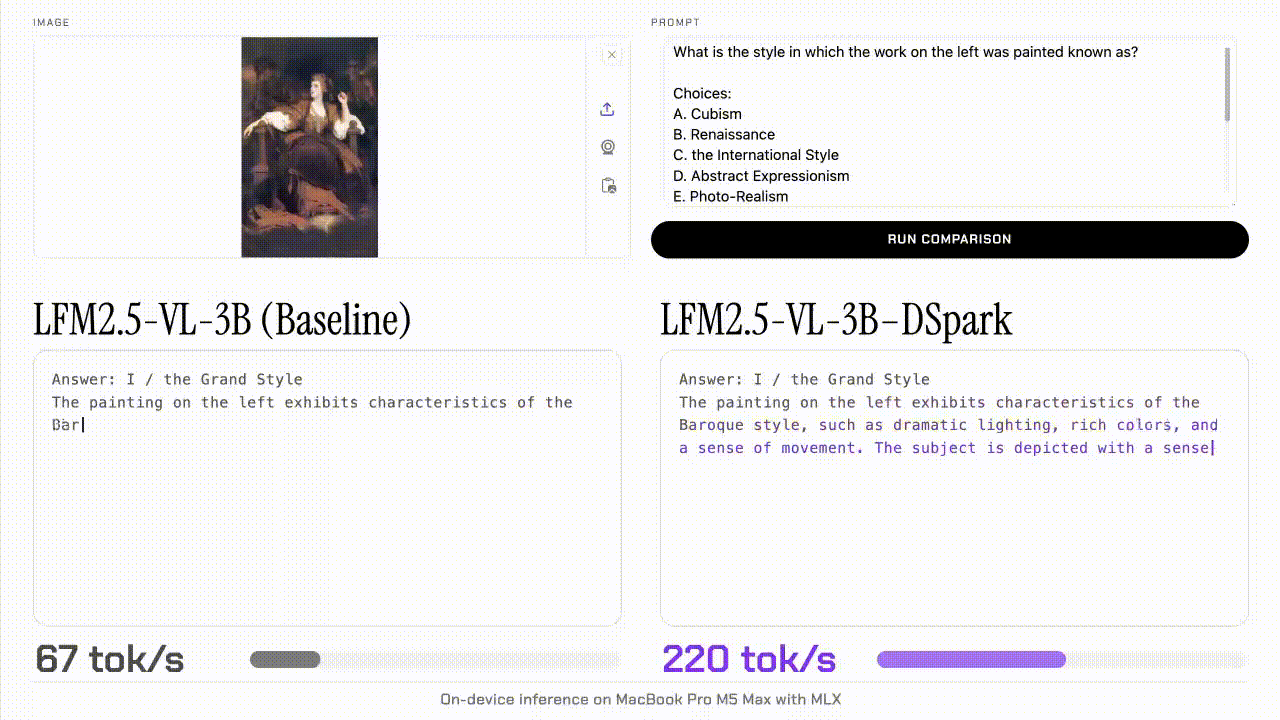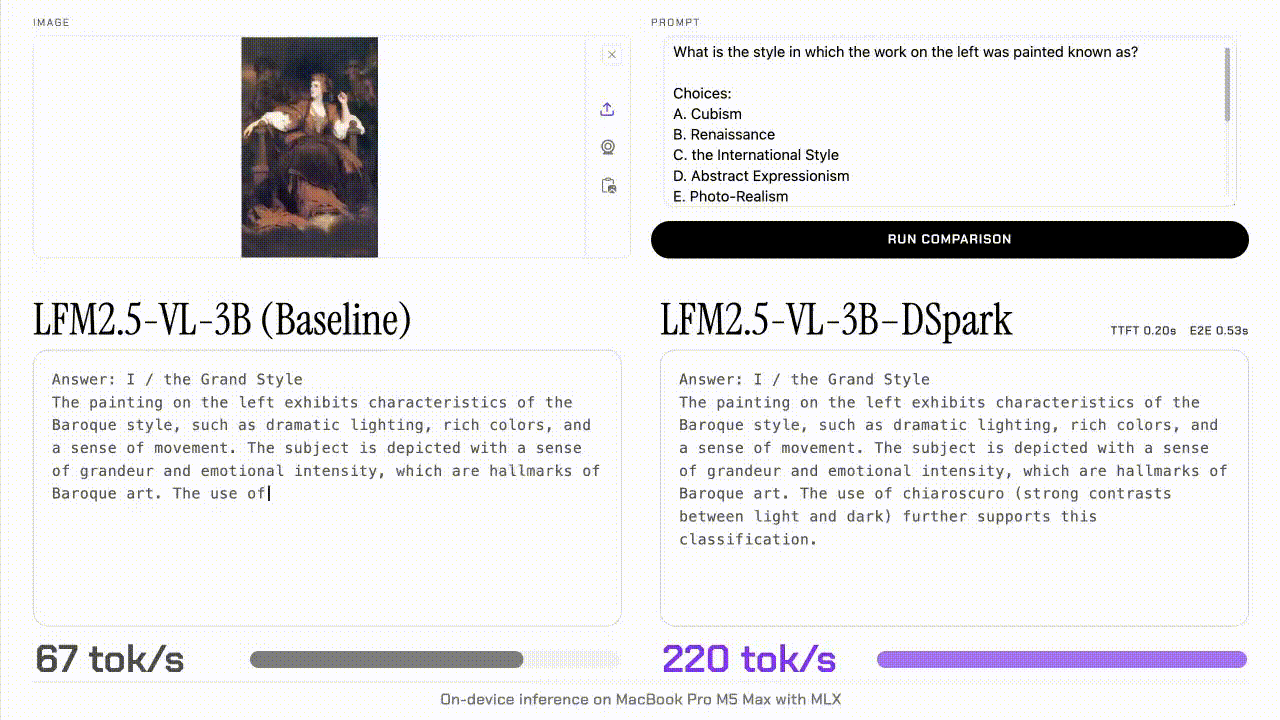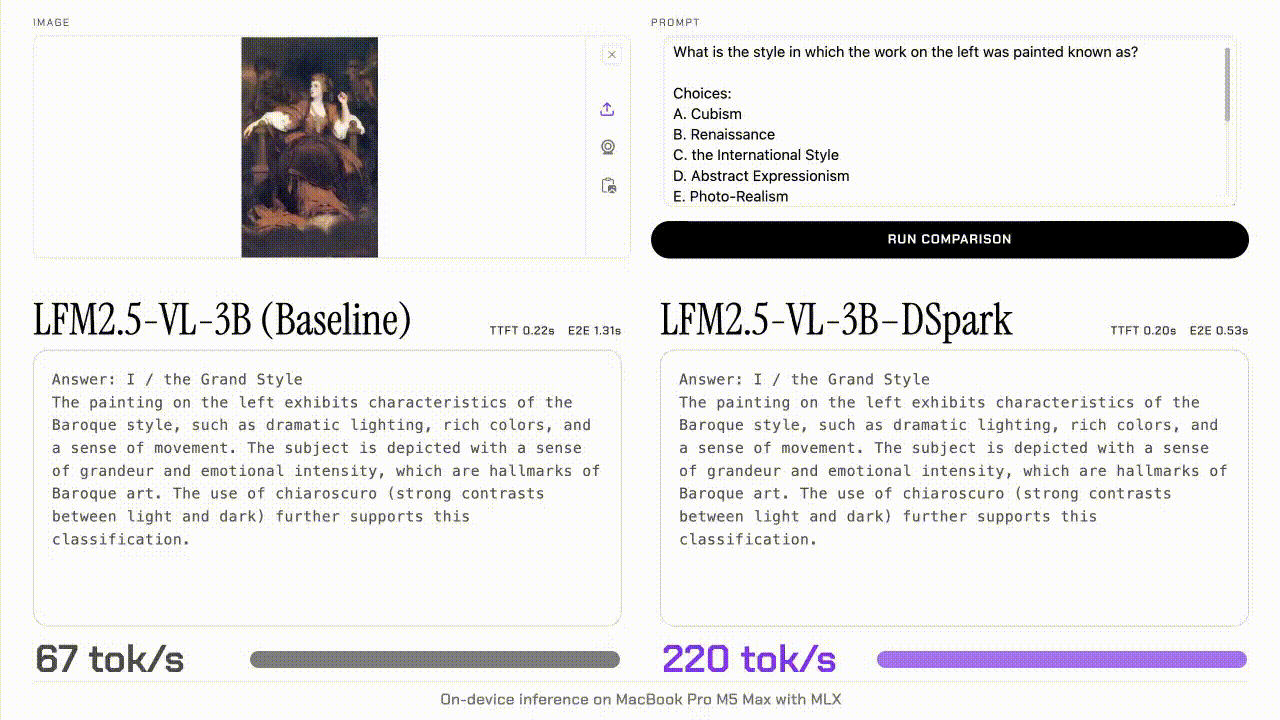
LFM2.5-VL-DSpark accelerates vision-language model inference, achieving speedups of up to 3.13x on-device and 2.66x on H100 GPUs, with a modest parameter increase. It integrates seamlessly with existing frameworks like llama.cpp and MLX-VLM.
✦ Why It Matters
Consider integrating LFM2.5-VL-DSpark into your vision-language projects for improved inference speed.
Key Takeaways
How It Works
The drafter captures hidden states from fixed layers of the model, processing both image and text inputs in a shared representation. This allows for efficient token generation while maintaining consistent dimensionality across modalities.
Related