EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
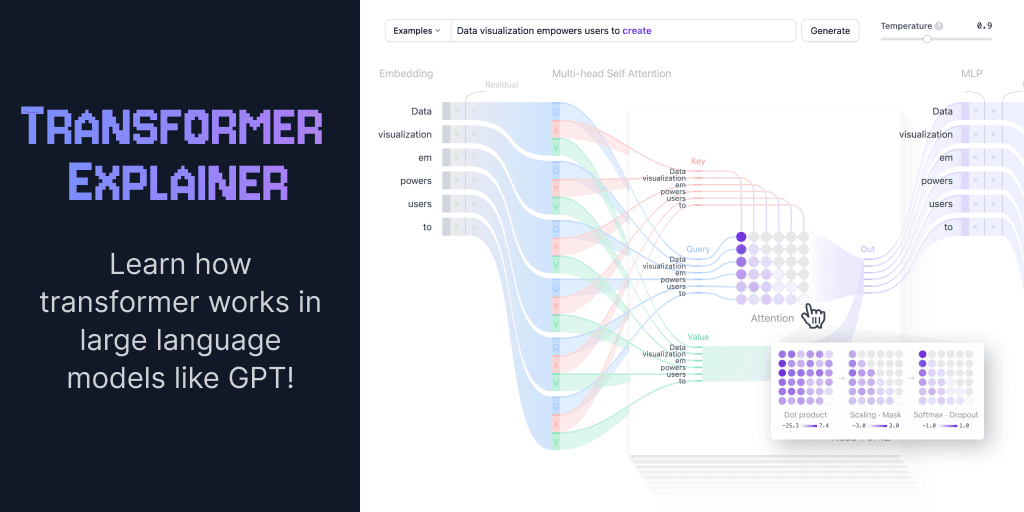
Transformers, introduced in 2017, revolutionized AI with their self-attention mechanism, enabling effective next-token prediction in text generation. They power models like GPT, Llama, and Gemini across various domains including text, audio, and image processing.
✦ Why It Matters
Explore using Transformer models like GPT-2 for your next text generation project to leverage their advanced capabilities.
Key Takeaways
Full Summary
Transformers are a neural network architecture that has transformed the field of Artificial Intelligence since their introduction in the paper 'Attention is All You Need' in 2017. They excel in tasks such as text generation, audio processing, image recognition, and even game playing.
The core functionality of text-generative Transformers revolves around next-token prediction, where the model predicts the most likely next word or subword based on a given prompt. A key innovation is the self-attention mechanism, which allows the model to consider the entire input sequence and capture long-range dependencies more effectively than previous architectures.
The GPT-2 family, with models like the 124 million parameter GPT-2 (small), serves as a foundational example of this technology. While not the latest model, it retains essential architectural features that are present in more advanced versions, making it a useful starting point for understanding Transformers.
Related