EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
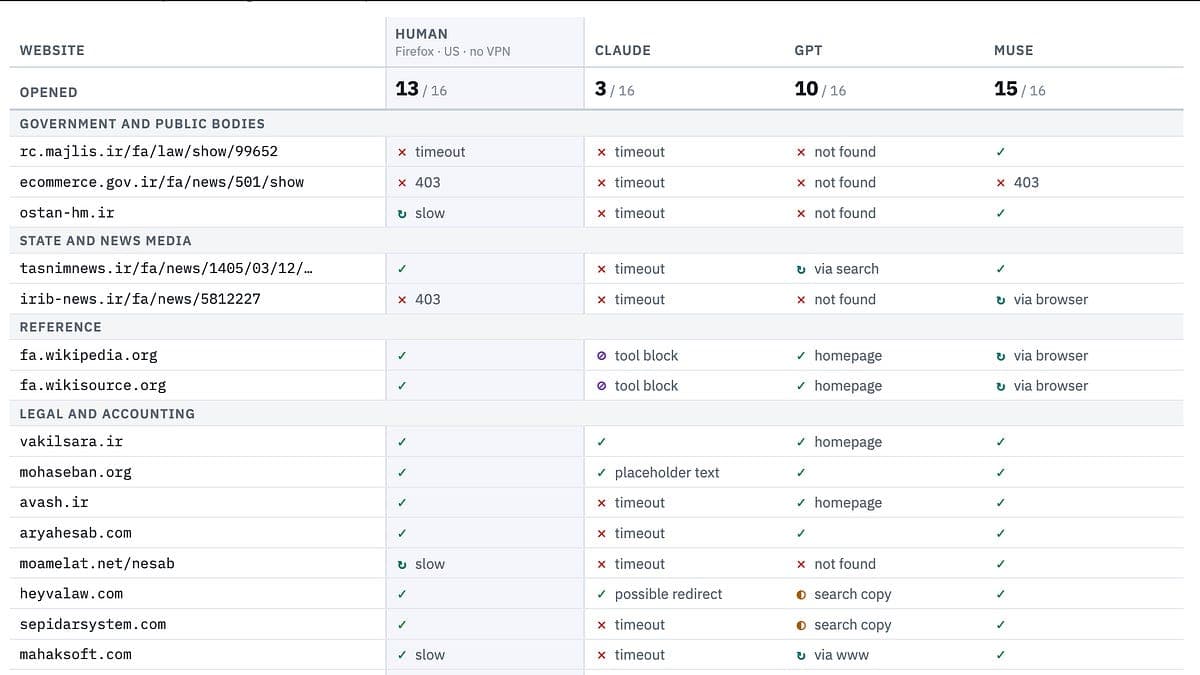
An open-source platform was developed to analyze language model (LLM) responses across different languages, focusing on the impact of language on AI's reliability. The project evaluated how three AI agents filled gaps in the World Bank's data for the U.S. and Iran, revealing significant differences in performance based on language context.
✦ Why It Matters
Evaluate your AI models' performance across different languages to ensure equitable outcomes.
Key Takeaways
How It Works
The experiment involved three AI agents tasked with updating a database, where their interactions with the user and information sources were closely monitored. Each agent's approach to accessing data varied, with some requiring repeated permissions while others acted autonomously, reflecting different design philosophies regarding user oversight.
Related