EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
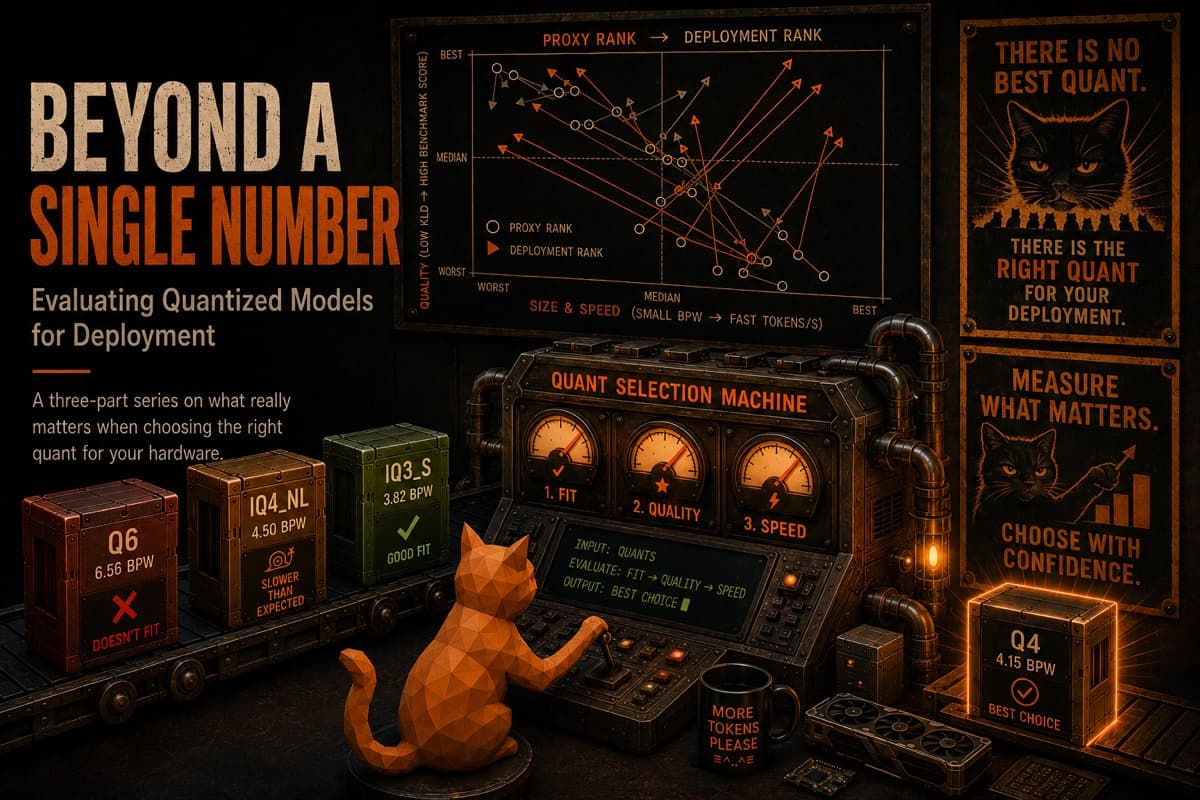
ByteShape introduces a comprehensive framework for evaluating quantized models that goes beyond single metrics, focusing on fit, quality, and speed for practical deployment.
✦ Why It Matters
Evaluate your quantized models using a multi-faceted approach to ensure effective deployment today.
Key Takeaways
Full Summary
Quantized models are typically assessed using single metrics like model size or perplexity, but these do not fully address deployment needs. ByteShape's framework evaluates models based on three criteria: fit, which determines compatibility with hardware; quality, assessed through downstream task benchmarks; and speed, measured by token-generation throughput.
The study reveals that traditional fidelity metrics like Kullback-Leibler divergence (KLD) fail to rank models effectively when they are close to baseline quality. Additionally, bits per weight (BPW) does not reliably predict speed among similarly sized models due to various factors like quantization format and hardware architecture.
The findings suggest that the best quantization choice is one that fits the hardware, performs well in benchmarks, and achieves adequate speed in real-world scenarios.
Related