EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
Quantization techniques for large language models (LLMs) have been visually explained, showcasing how these methods can significantly reduce model size while maintaining performance. The key outcome is a clearer understanding of the trade-offs involved in model compression.
✦ Why It Matters
Explore quantization techniques today to optimize your LLMs for deployment on resource-constrained environments.
Key Takeaways
How It Works
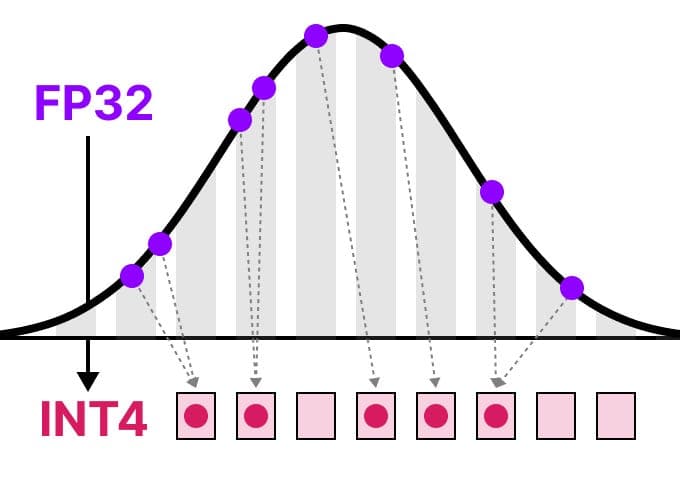
Quantization reduces the bit-width of model parameters, mapping higher precision values to lower precision representations. Symmetric quantization centers around zero, while asymmetric quantization shifts the range, requiring additional calculations for zero-point adjustments.
Calibration techniques help determine the optimal range for quantization, ensuring minimal loss of accuracy.
Related