EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
Local implementations of large language models (LLMs) often underperform compared to their reference implementations due to hardware and software discrepancies. This article explores how these differences impact model performance and user experience.
✦ Why It Matters
Evaluate your hardware and software setup to improve LLM performance today.
Key Takeaways
How It Works
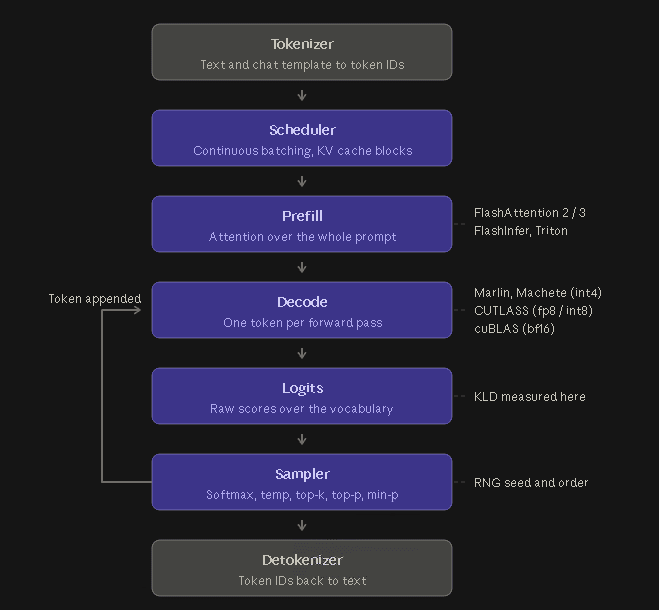
The article explains that LLMs generate text by predicting the next token based on previous context, using logits that are converted into probabilities. The choice of attention backend and quantization method can lead to different outcomes in token predictions, affecting overall model performance.
Related