EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
vLLM is a high-throughput inference system designed for large language models (LLMs), achieving significant performance improvements in processing speed and resource efficiency. It enables faster and more scalable deployment of LLMs in real-world applications.
✦ Why It Matters
Consider integrating vLLM into your LLM deployment strategy to enhance performance and reduce costs.
Key Takeaways
How It Works
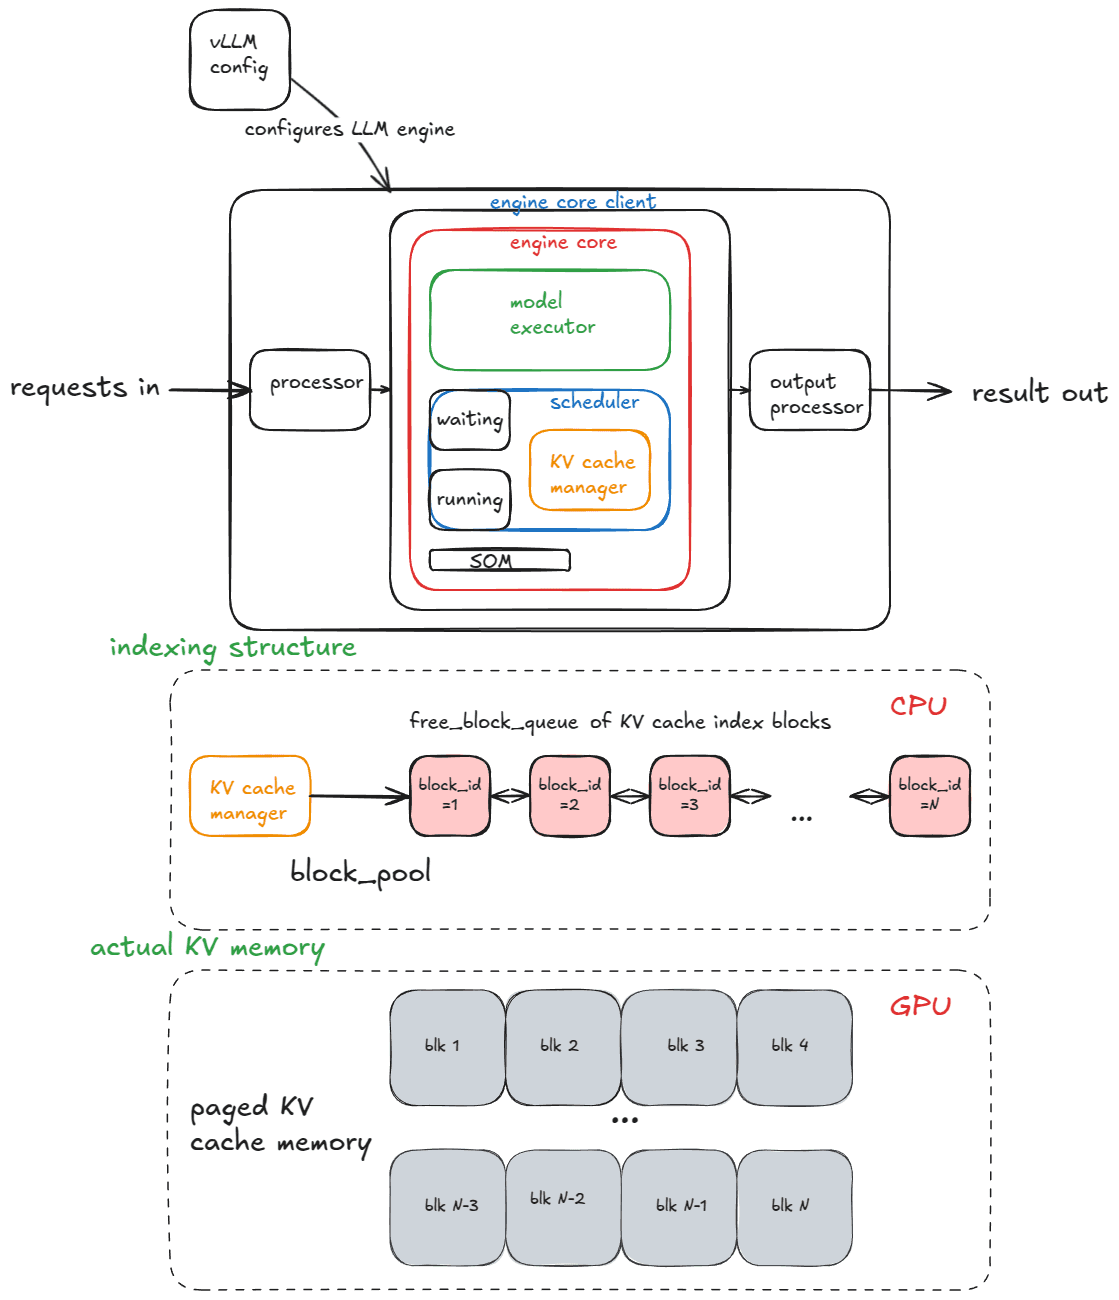
vLLM employs a KV-cache manager to optimize memory usage during inference, allowing for paged attention that efficiently maps tokens to their computed cache blocks. The scheduler intelligently prioritizes requests, enabling mixed workloads of prefill and decode requests.
Advanced features like chunked prefill break long prompts into manageable pieces, while prefix caching reuses previously computed tokens, significantly reducing processing time.
Related