EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
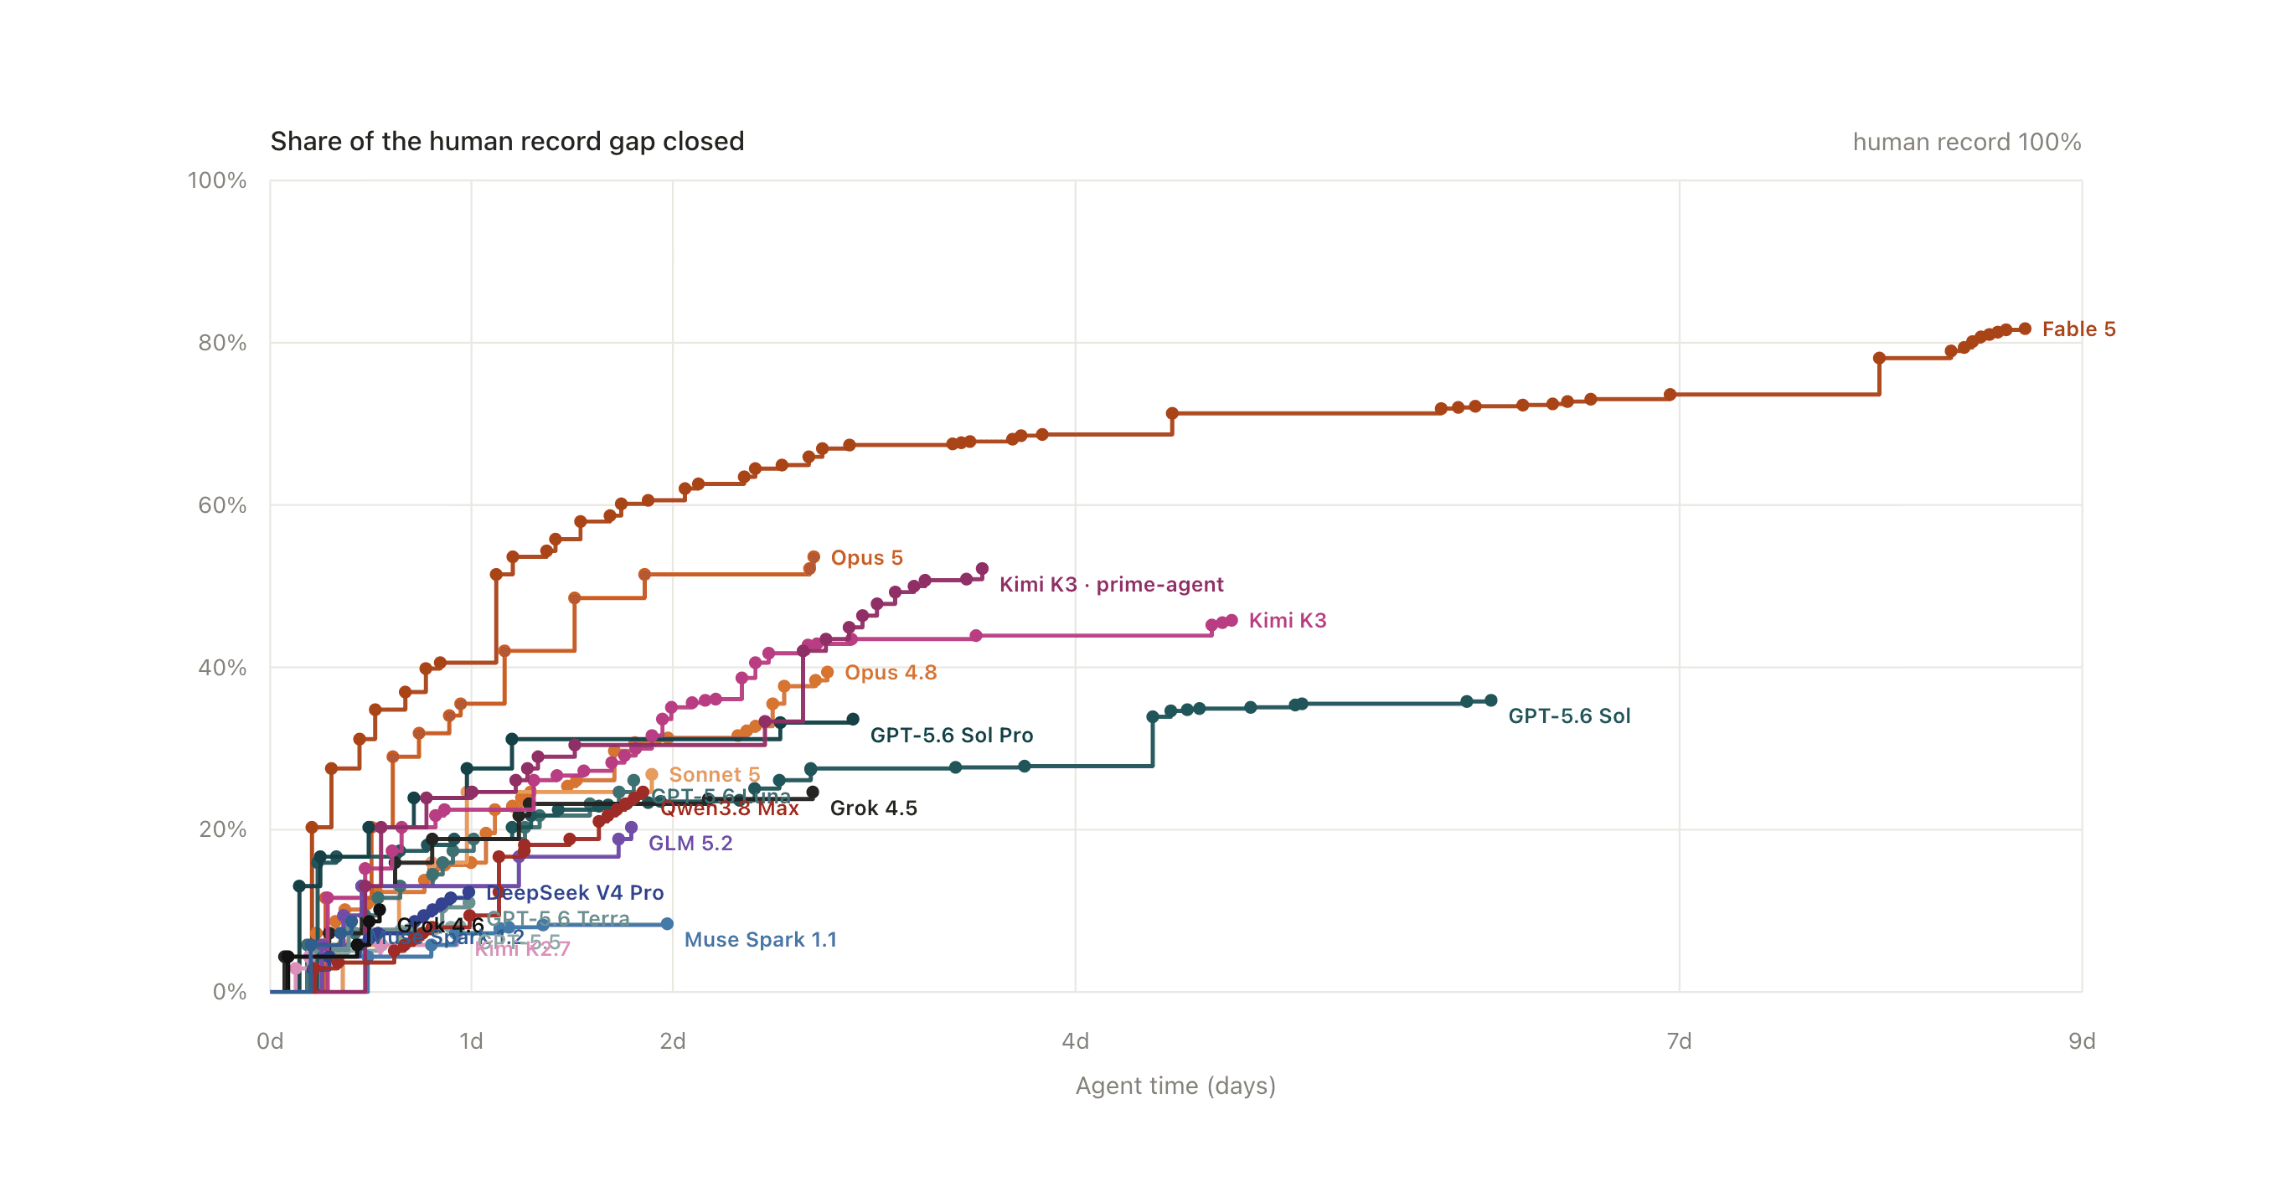
NanoGPT showcases various models like Fable 5 and Opus 4.8, achieving impressive performance metrics, with Fable 5 leading in overall effectiveness.
✦ Why It Matters
Evaluate your current AI models against these benchmarks to identify potential improvements.
Key Takeaways
Full Summary
In the competitive landscape of AI models, the NanoGPT Speedrun Frontier evaluates multiple architectures based on their performance metrics. Fable leads with an impressive accuracy of 81.7%, followed closely by Opus and Kimi K, which achieved 53.6% and 52.2% respectively.
The evaluation includes various models like GPT-5.6 and Grok, each with distinct resource requirements and performance outcomes. For instance, GPT-5.6 Sol has a substantial model size of 2.9 billion parameters but only reaches 35.9% accuracy.
The results are derived from a series of tests that measure how well each model performs on specific tasks, providing insights into their capabilities and limitations. This benchmarking can guide developers in selecting the right model for their applications, balancing performance with resource constraints.
Related