EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
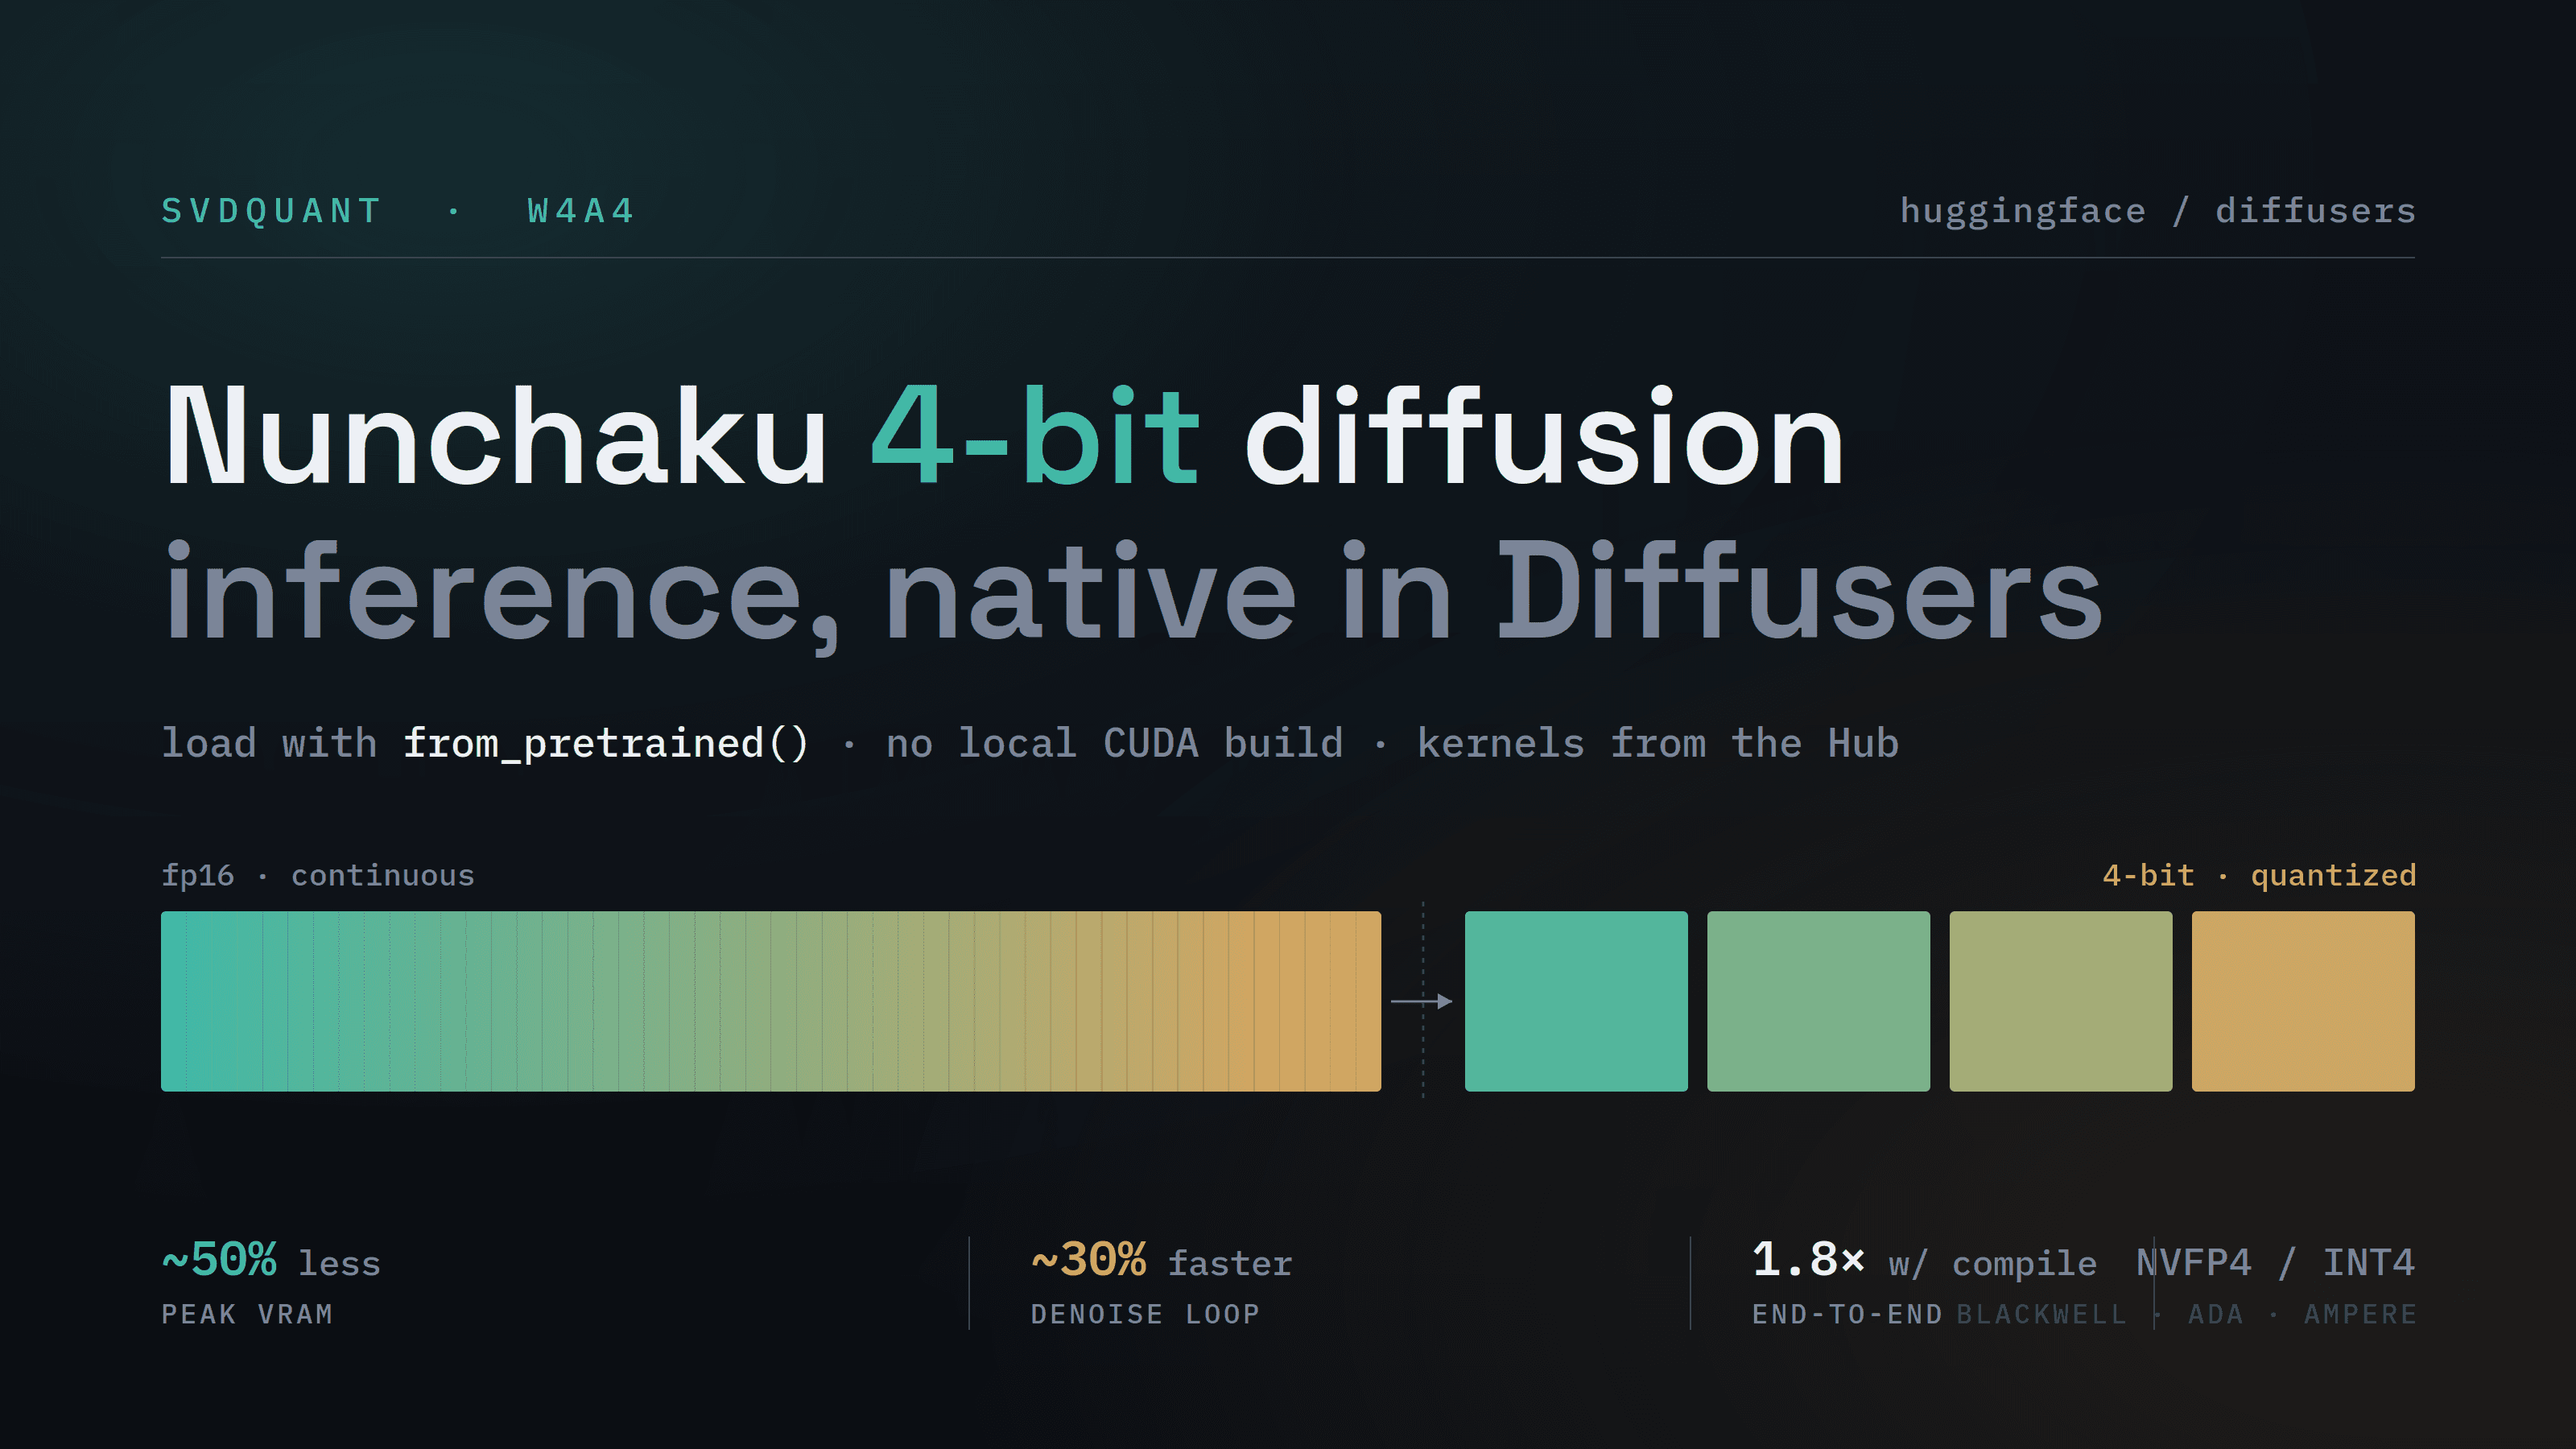
Nunchaku's 4-bit diffusion inference engine enhances memory efficiency and speeds up the denoising process by utilizing 4-bit weights and activations. This integration into the Diffusers framework simplifies the use of Nunchaku checkpoints without requiring local CUDA compilation.
✦ Why It Matters
Start using Nunchaku's 4-bit inference to enhance your diffusion model's performance today.
Key Takeaways
How It Works
Nunchaku Lite modifies standard Diffusers models by replacing certain linear layers with SVDQuant's optimized versions, allowing for 4-bit weights and activations. This process reduces memory usage and speeds up computations by handling activation outliers more effectively.
The integration is seamless, requiring no custom pipeline or local compilation, as necessary CUDA kernels are downloaded automatically.
Related