EmbeddingGemma 2: an open, lightweight multimodal embedding model
deepmind.google·6d ago
TL;DR
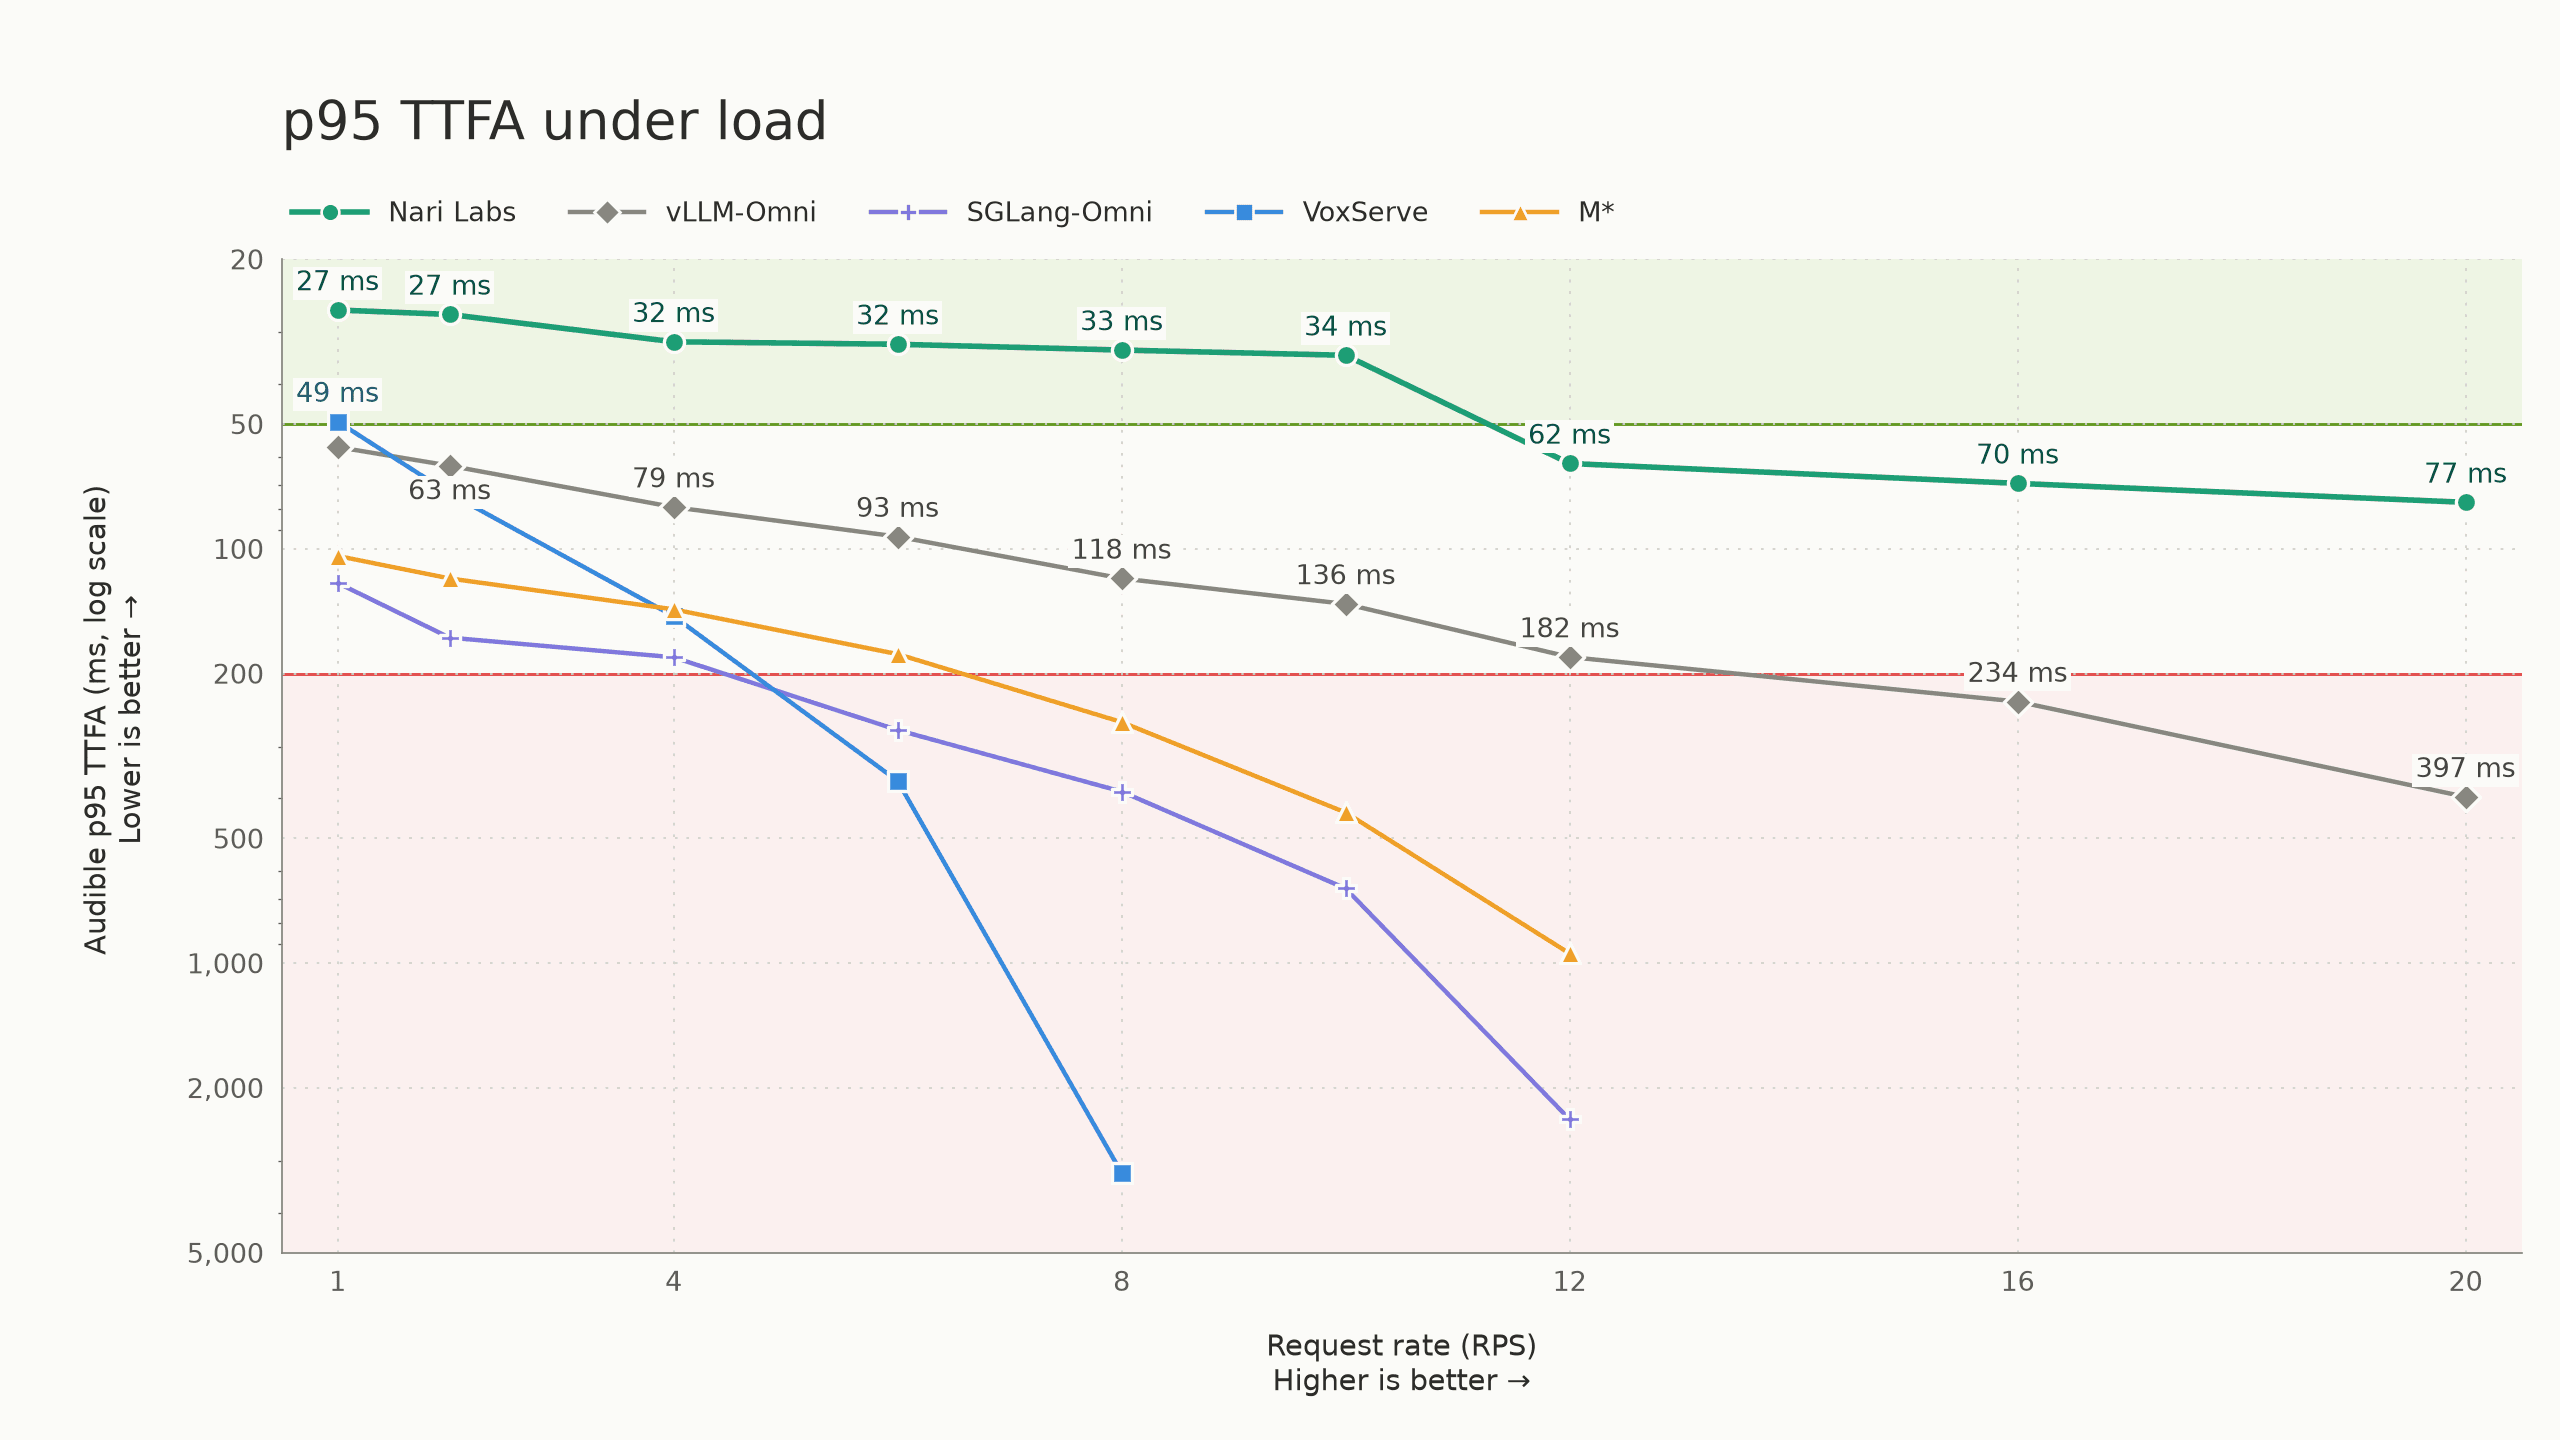
Qwen3-TTS 1.7B CustomVoice achieves sub-50 ms time-to-first-audio and 10 requests per second on a single NVIDIA H100 SXM, outperforming competitors.
✦ Why It Matters
Consider adopting Qwen3-TTS for cost-effective, low-latency TTS applications in your projects.
Key Takeaways
How It Works
Qwen3-TTS operates with a three-part architecture: the Talker predicts audio tokens, the Code Predictor generates additional tokens, and the Codec converts these tokens into audio. By scheduling these tasks together, the system can prioritize urgent requests and optimize processing efficiency, reducing latency.
Related